Game2Player builds 568 verified web games to train visual game agents
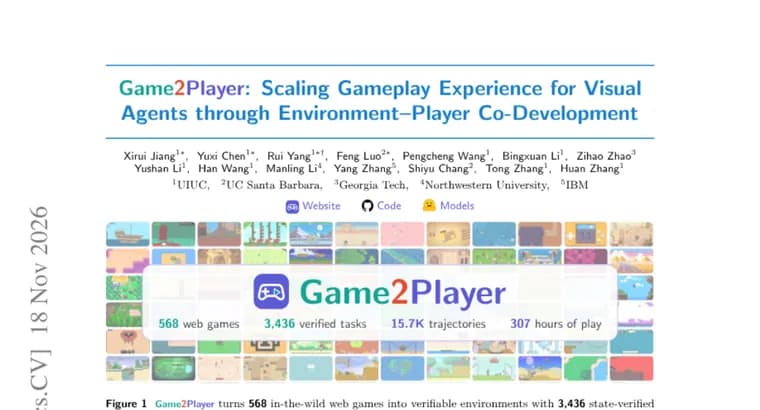
Games are a rich testbed for visual agents, the paper says, because they demand perception, long-horizon planning and precise control. Training data is the bottleneck. Collecting human gameplay is costly, learning from gameplay videos requires inferring the missing actions, and existing datasets cover a limited range of games, often without explicit tasks or verifiable outcomes.
The authors introduce Game2Player, a framework that co-develops game environments and players to collect diverse and verifiable gameplay experience at scale. It runs as a loop. A Builder agent adapts existing web games, exposes their internal state, and defines tasks with state-based progress measures and success checks. A Coding Player and a VLM Player then attempt the tasks and report problems back to the Builder for repair. In this way play serves as both environment validation and training data collection.
With the loop, the authors build 568 verified web games with 3,436 tasks. They collect 15.7K trajectories, which amount to 307 hours of gameplay. They hold out 50 of the games as a benchmark called PlayerBench.
To test the collected experience as training data, they train VLM agents with progress-weighted SFT, a supervised fine-tuning scheme that gives greater weight to steps that advance task progress. The resulting Game2Player-9B improves progress from 14.3% to 31.2% on PlayerBench and from 30.0% to 53.1% on the external GameWorld benchmark. These are absolute progress percentages, not relative gains.
The authors frame the result modestly: their work suggests a path for visual agents to scale their gameplay experience by building, verifying and learning from existing game worlds.
Key facts
- Game2Player is a loop in which a Builder agent adapts existing web games, exposes their state and defines tasks, while a Coding Player and a VLM Player attempt them and report problems for repair.
- The authors build 568 verified web games with 3,436 tasks and collect 15.7K trajectories (307 hours of gameplay); 50 games are held out as PlayerBench.
- Training VLM agents with progress-weighted SFT, which weights steps that advance task progress more heavily, yields Game2Player-9B.
- Game2Player-9B improves progress from 14.3% to 31.2% on PlayerBench and from 30.0% to 53.1% on the external GameWorld benchmark.
- The motivation: human gameplay is costly to collect, gameplay videos lack explicit actions, and existing datasets have limited game coverage and often no verifiable outcomes.
Why it matters
Training data for agents that act on screens is hard to get. Human play is expensive, and video does not record the actions taken. Game2Player tries to get around both problems by having agents build verifiable game environments and then play them, so the same play checks the environment and produces training data. The reported gains are large in absolute terms: on PlayerBench progress goes from 14.3% to 31.2%, and on the external GameWorld benchmark from 30.0% to 53.1%.
Who it affects
Researchers building visual and VLM-based agents, especially those who need game-like environments with explicit tasks and checkable outcomes. It also bears on anyone who builds agent benchmarks, since the loop produces tasks with state-based progress measures and success checks.
How to use it
The source describes a method rather than a product. The practical idea for agent builders is the loop itself: let a Builder expose game state and define tasks with progress measures, let player agents attempt them and report breakage, and train on the resulting trajectories with progress-weighted SFT. No release of code, data, models or the benchmark is mentioned.
How solid is it
This is a preprint listed on Hugging Face Papers, and the evidence is the abstract's own numbers. The headline results are measured on PlayerBench, a set of 50 held-out games from the authors' own pipeline, and on one external benchmark, GameWorld, which gives some independence. No authors or institutions are named in the text. The base model behind Game2Player-9B is not named, and the abstract does not say explicitly which model the 14.3% and 30.0% starting figures belong to. No comparison with other agents, proprietary models or human players is given.
Risks and caveats
The authors say only that their work suggests a path, not that it proves one. The abstract does not say what counts as progress numerically beyond state-based progress measures, nor how many tasks PlayerBench contains. No compute cost, training details or dataset split for SFT are given, so it is hard to judge how much of the gain comes from the data and how much from the training recipe. The figures are absolute progress percentages and should not be read as relative improvements.
“play serves as both environment validation and training data collection”
— Game2Player paper abstract