Mind2Act World benchmark finds strongest agent solves 12.0% of combined tasks
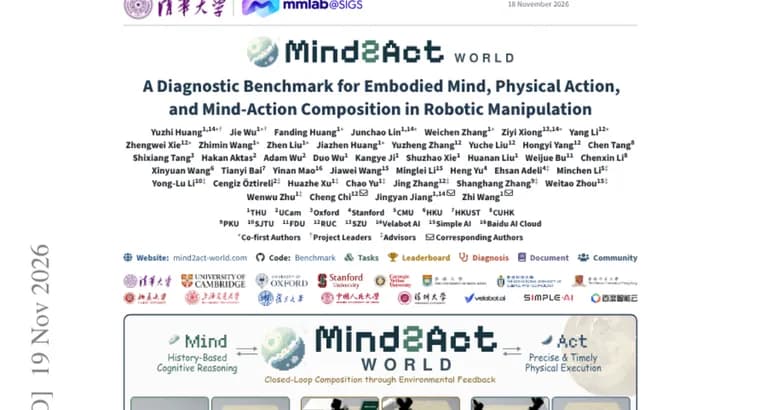
Mind2Act World is a diagnostic benchmark for robotic manipulation, introduced in a paper listed on Hugging Face. Its starting point is that embodied intelligence needs three complementary capabilities: reasoning from history, precise and timely physical execution, and the composition of the two through environmental feedback. The authors argue that existing benchmarks either test reasoning and execution inside the same tasks, or test them separately without their composition. Either way, they reveal little about whether a failure comes from reasoning, execution, or the way the two are combined.
The benchmark has 30 simulated manipulation tasks drawn from five real-world application domains. Each task comes in three difficulty levels and two scene settings, Clean and Random, which gives 180 configurations. The tasks are grouped into three views. Mind tests decisions based on past observations. Act tests precise and timely execution. Mind2Act combines both in closed-loop tasks, where the outcome of an action guides later decisions. Comparing a system's results across the three views shows whether it lacks a capability or fails to compose capabilities it already has.
The authors also built a diagnosis harness. It attributes the failed episodes of three representative systems to Mind, Act, or their composition, and it summarizes each system in a profile card.
They evaluated multimodal agents, vision-language-action models (VLAs) and world-action models (WAMs). The main finding is that competence in a single view does not carry over to Mind2Act tasks. Even the strongest agent succeeds in 52.7% of Mind episodes and 39.0% of Act episodes, but in only 12.0% of Mind2Act episodes.
The failure patterns differ by system type. The strongest agent retains task state but struggles with sustained contact. End-to-end policies execute practiced motions but retain little task state. The authors conclude that composing reasoning and execution through environmental feedback is the main open problem.
Key facts
- Mind2Act World has 30 simulated manipulation tasks from five real-world application domains, with three difficulty levels and two scene settings (Clean and Random), giving 180 configurations.
- Tasks form three views: Mind (decisions from past observations), Act (precise, timely execution) and Mind2Act (closed-loop tasks combining both).
- The strongest agent succeeds in 52.7% of Mind episodes and 39.0% of Act episodes, but in only 12.0% of Mind2Act episodes.
- The strongest agent retains task state but struggles with sustained contact; end-to-end policies execute practiced motions but retain little task state.
- A diagnosis harness attributes failed episodes of three representative systems to Mind, Act, or their composition and produces a profile card for each.
Why it matters
When a robot fails a manipulation task, it is often unclear whether it reasoned badly, moved badly, or could not connect the two. The authors say existing benchmarks reveal little about this. Mind2Act World is built to separate the causes. Its headline result is a steep drop: the strongest agent reaches 52.7% in Mind and 39.0% in Act, but only 12.0% when both must work together in a closed loop. That points to composition through environmental feedback, which the authors call the main open problem.
Who it affects
The benchmark targets researchers building embodied AI systems. It evaluates three families: multimodal agents, vision-language-action models (VLAs) and world-action models (WAMs). The finding that single-view competence does not carry over to Mind2Act tasks applies to all the families the authors tested.
How to use it
The intended use is diagnostic. A team runs a system on all three views and compares the results. A gap between Mind or Act scores and the Mind2Act score suggests the system has the capabilities but fails to compose them. A low score in one single view suggests the capability itself is missing. The diagnosis harness goes further, attributing failed episodes to Mind, Act, or composition and summarizing each system in a profile card. The configurations let a team vary difficulty and test Clean versus Random scenes.
How solid is it
The numbers come from the paper's own abstract, so they are the authors' reported results. They are success rates for the strongest agent only: 52.7% (Mind), 39.0% (Act) and 12.0% (Mind2Act). The abstract names no authors or institutions. The strongest agent is not named, and neither are the specific VLA, WAM or multimodal-agent models evaluated. No success rates are given for the VLAs or WAMs, nor for the strongest agent per difficulty level or per scene setting. It does not say how many episodes were run per configuration, or how the success rates are aggregated.
Risks and caveats
All tasks are simulated; no real-robot results are reported. The diagnosis harness covers only three representative systems, and which three is not stated. The abstract does not name the five application domains. No release date, code, dataset or leaderboard availability is mentioned, so it is not clear from this source how others can run the benchmark. The failure analysis of the strongest agent and of end-to-end policies is the authors' own reading of their results.
“These findings point to composing reasoning and execution through environmental feedback as the main open problem.”
— Mind2Act World paper abstract