NVIDIA adds native Rust support for CUDA GPU kernels
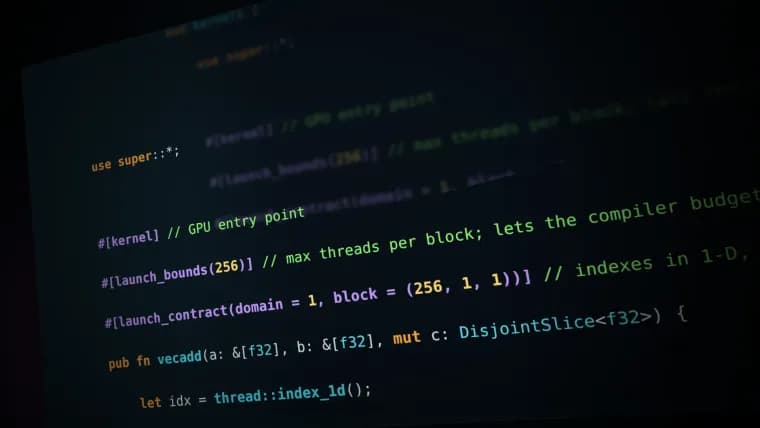
In September 2026, NVIDIA said it is leaning into native GPU programming in Rust. Until now you could launch a CUDA kernel from Rust, but the kernel body itself had to be written in another language such as CUDA C++ or CUDA Python. Two new projects close that gap: kernels can be written entirely in Rust and compiled natively to PTX rather than wrapped around code from elsewhere. NVIDIA frames this as part of a broader shift: Rust already runs through much of the AI systems layer (inference engines, serving infrastructure, drivers, agent runtimes), and NVIDIA itself already uses it elsewhere, including the Nova Linux driver, a Rust core inside NVIDIA Dynamo, and Rust bindings for NVTX.
The two new projects match CUDA's two existing programming models. cuda-oxide covers SIMT, the model already used in CUDA C++ or numba-cuda, where a kernel describes what one thread does and launches thousands of them. It is a custom rustc codegen backend: it intercepts compilation, routes #[kernel] functions through Rust MIR, the Pliron IR framework, and LLVM IR down to PTX, and hands everything else to the standard Rust backend. It requires Linux, a GPU with compute capability 8.0 or later, a CUDA toolkit of 12.x or newer, clang with its libclang headers, and a pinned nightly Rust toolchain; it is installed with 'cargo +nightly-2026-04-03 install --git https://github.com/NVlabs/cuda-oxide.git cargo-oxide', and 'cargo oxide doctor' checks the setup before 'cargo oxide new' and 'cargo oxide run' scaffold and run a demo.
cutile-rs covers the newer Tile model, which is also available in C++ and Python. Here a kernel body runs once as a single logical thread over one tile (a sub-tensor of data), and the compiler decides how many real GPU threads implement it. A #[cutile::module] macro embeds the kernel's AST in the host binary and JIT-compiles it through CUDA Tile IR the first time it is actually launched. Its requirements are lighter: a GPU with compute capability 8.0 or later, CUDA 13.3, stable Rust 1.89 or newer, and Linux, with no nightly toolchain and no separate LLVM needed. It ships as an ordinary published crate, added with 'cargo add cutile' after a plain 'cargo new'.
NVIDIA recommends reaching for Tile first, because the compiler decides how tiles map onto each GPU architecture, so the source code does not encode architecture-specific choices; SIMT is for when a developer needs that control, or wants to manage memory and threads directly. Which language to use is treated as a separate question from which model to use, and NVIDIA says it plans to support interop between the Rust tracks and the existing C++/Python CUDA frontends, so choosing Rust does not lock a developer out of the others, though that interop is not yet built.
Both projects are demonstrated with the same example: an elementwise addition over 1,024 floats. In cuda-oxide, the kernel's mutable output is typed as a DisjointSlice
Key facts
- NVIDIA released two Rust-native CUDA kernel toolchains in September 2026: cuda-oxide for the SIMT model and cutile-rs for the newer Tile model, so GPU kernels no longer have to be written in another language.
- cuda-oxide requires Linux, a GPU with compute capability 8.0 or later, a CUDA toolkit of 12.x or newer, clang with libclang headers, and a pinned nightly Rust toolchain.
- cutile-rs needs a GPU with compute capability 8.0 or later, CUDA 13.3, and stable Rust 1.89 or newer, with no nightly toolchain and no separate LLVM required, and ships as a normal published crate.
- NVIDIA recommends starting with the Tile model, since the compiler maps tiles onto each GPU architecture automatically, and dropping to SIMT only when manual control over memory and threads is needed.
- NVIDIA says it plans interop between the two Rust tracks and the existing C++/Python CUDA frontends, though that is not built yet, and intends to keep growing CUDA Rust into 2027 and beyond.
Why it matters
GPU kernels were the one part of the AI systems stack that could not be written in Rust: you could launch a kernel from Rust, but the kernel body itself had to be C++ or Python. NVIDIA already uses Rust elsewhere in that stack, in the Nova Linux driver, a Rust core inside NVIDIA Dynamo, and NVTX's Rust bindings, and inference engines, serving infrastructure, drivers and agent runtimes increasingly are written in Rust too, for the compile-time bug-catching it offers without giving up native performance. cuda-oxide and cutile-rs remove the last place where that stack had to drop into another language.
Who it affects
Developers building or maintaining Rust-based systems that sit next to the GPU, such as inference engines, serving infrastructure, drivers and agent runtimes, who previously had to reach outside Rust just for the kernel itself. It also affects existing CUDA C++ or numba-cuda users who want compile-time memory-safety guarantees for kernel code without changing the rest of their toolchain.
How to use it
For the SIMT track, install cuda-oxide with 'cargo +nightly-2026-04-03 install --git https://github.com/NVlabs/cuda-oxide.git cargo-oxide' on Linux with a GPU of compute capability 8.0 or later, CUDA toolkit 12.x or newer, clang with libclang headers, and the pinned nightly toolchain; 'cargo oxide doctor' checks the setup, and 'cargo oxide new' plus 'cargo oxide run' scaffold and run a demo. For the Tile track, add cutile-rs to an ordinary project with 'cargo add cutile' on a GPU of compute capability 8.0 or later, CUDA 13.3, and stable Rust 1.89 or newer, with no nightly toolchain or separate LLVM install needed. NVIDIA's own guidance is to default to Tile and use SIMT only when direct control over memory and threads is required.
How solid is it
NVIDIA presents this as an ongoing, multi-year effort, saying it will keep growing and maturing CUDA Rust into 2027 and beyond, rather than a finished, stable product. No individual engineer or team is credited for either project, and no benchmark or performance comparison against CUDA C++ or CUDA Python accompanies the announcement. Both worked examples shown are the same simple elementwise addition over 1,024 floats, not a production workload, so how either track performs and behaves on real kernels is not demonstrated here.
Risks and caveats
NVIDIA does not state whether cuda-oxide or cutile-rs is production-ready or still experimental beyond listing hardware and toolchain requirements, and gives no general-availability date, version number, pricing or licensing terms. cuda-oxide depends on a pinned nightly Rust toolchain and, optionally, a system LLVM install, a heavier and less stable dependency chain than the stable-Rust cutile-rs path. Interop between the two Rust tracks and the existing C++/Python CUDA frontends is described only as planned, so mixing them into a single codebase is not yet supported.