NVIDIA releases Cosmos3-H-Dreams, a real-time generative surgical simulator
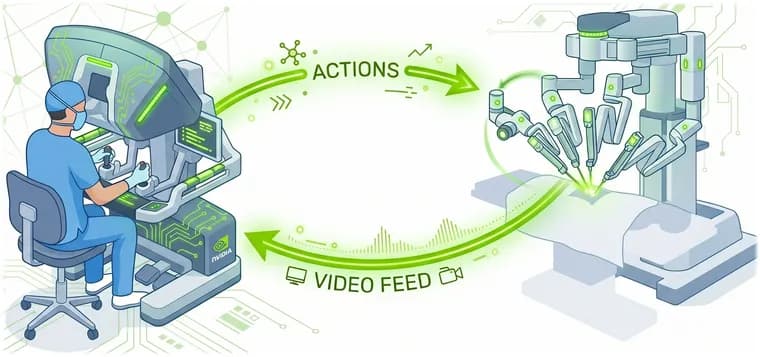
NVIDIA has published Cosmos3-H-Dreams, a generative surgical simulator. It learns from synchronized video and robot kinematics recorded during clinical procedures on the CMR Surgical Versius platform. NVIDIA says that, to its knowledge, this is the first real-time generative surgical simulator trained on clinical cholecystectomy recordings to support live kinematic control. It is powered by Cosmos 3 and accelerated with FlashDreams, NVIDIA's accelerated streaming-inference library, and it runs interactively on a single NVIDIA RTX PRO 6000 GPU.
The release follows the earlier Cosmos-H-Dreams, which was built on Cosmos-Predict2.5 and brought interactive generative simulation to dVRK tabletop suturing. That model, a world foundation model, skipped explicit modelling of scene geometry, tissue deformation and physical interactions and instead learned visual dynamics directly from video and kinematics. The new version moves from a controlled tabletop with a simple background to scenes inside the body, where small instrument movements can affect the whole view: tissue stretches under traction, reflections shift, structures become occluded and smoke changes visibility. Given an initial image and supplied tool actions, the simulator has to capture these responses while keeping anatomy and instruments stable as it generates each new block of video. Small errors can accumulate and gradually change instrument geometry or anatomical structure, so temporal consistency is essential. NVIDIA also notes that visual realism is a starting point for validation, not proof of biomechanical accuracy, and that the generated scene must follow the controls (translation, rotation and gripper commands) rather than just look plausible.
On the model side, Cosmos3-H-Dreams builds on Cosmos3-H-Embodied-Nano, a 16-billion-parameter model pretrained on Open-H-Embodiment. A bidirectional teacher is specialized on curated cholecystectomy video and kinematics. Sample selection targets two visible, engaged instruments, a left Cadiere grasper and a right monopolar hook, and limits camera commands so the data emphasizes instrument-driven interaction. The model uses 28 action dimensions: pose and gripper information for both arms, plus energy controls, thumbstick axes and thumbstick buttons. Training uses 832 x 480 video with actions aligned at 10 Hz; NVIDIA says that sampling rate is distinct from runtime generation throughput.
The training pipeline goes from teacher to student. The bidirectional teacher is first adapted on 24 future frames, then the horizon is extended to 72 frames, which is 2.4 and 7.2 seconds at 10 Hz. Distillation then turns the teacher into a causal student that generates video in short blocks as new actions arrive. Causal teacher forcing prepares the student for sequential generation using recorded context. Self-Forcing then trains it on its own generated context, guided by the teacher and a learned critic, which NVIDIA says helps address error accumulation in interactive rollouts. The first released student uses four denoising steps per generated block. That student is trained further with a two-step schedule to produce the second checkpoint; the two-step model is separately trained, not the four-step model run with fewer sampling steps. Fewer denoising steps give faster inference at the expense of lower visual quality, and both checkpoints let developers explore that balance.
FlashDreams supplies the streaming runtime. For long rollouts, the integration uses an adapted FadeMem module that consolidates the growing key/value cache. NVIDIA presents this as complementary to Self-Forcing: distillation addresses how the model learns from its generated history, while cache consolidation addresses how that history is stored during streaming.
To show generalization beyond the training data, NVIDIA presents demonstrations of different cholecystectomy scenes conditioned on instrument actions recorded with a VR headset. Two videos start from the same initial frame but follow different action sequences. NVIDIA says they show distinct continuations of the same scene with physically accurate tissue deformations, and that such rollouts let researchers check whether instruments follow the controls, whether tissue responds coherently, and whether appearance stays consistent over time.
The release includes four-step and two-step checkpoints for cholecystectomy. NVIDIA says the system can be adapted to other datasets and embodiments with synchronized video and compatible action representations, and it provides a step-by-step recipe for teacher fine-tuning and Self-Forcing distillation covering data preparation, public teacher-training tools and the distillation stages. Controller integrations must use the same action conventions and normalization as training. Links are given for the code, the model checkpoint, Cosmos3-H-Embodied-Nano, the Open-H-Embodiment dataset, FlashDreams and Cosmos 3.
NVIDIA lists five research directions: model the full procedure across all phases of cholecystectomy; connect generative and numerical simulation, combining learned visuals with explicit geometry, contact and tissue mechanics; evaluate with surgeons; support more than two controlled instruments; and develop autonomous surgical policies by coupling world action models to the simulator in a closed loop. It states plainly that these are research directions, not established clinical capabilities, and that Cosmos3-H-Dreams is a research simulator, not a validated system for patient care.
Key facts
- Cosmos3-H-Dreams is trained on video and robot kinematics from clinical cholecystectomy procedures on the CMR Surgical Versius platform, and runs interactively on a single NVIDIA RTX PRO 6000 GPU.
- It builds on Cosmos3-H-Embodied-Nano (16 billion parameters, pretrained on Open-H-Embodiment) and uses 28 action dimensions, with training on 832 x 480 video and actions aligned at 10 Hz.
- Two distilled student checkpoints are released: a four-step model and a separately trained two-step model; fewer denoising steps mean faster inference but lower visual quality.
- Teacher horizon grows from 24 to 72 future frames (2.4 to 7.2 seconds at 10 Hz); Self-Forcing distillation and an adapted FadeMem cache module target error build-up in long rollouts.
- NVIDIA states it is a research simulator, not a validated system for patient care, and offers a recipe for adapting the approach to other datasets and controllers.
Why it matters
NVIDIA frames this as a step from tabletop suturing (the earlier Cosmos-H-Dreams on dVRK) to real clinical scenes with complex anatomy, tissue motion and occlusion. It claims, to its knowledge, the first real-time generative surgical simulator trained on clinical cholecystectomy recordings that supports live kinematic control. Instead of modelling geometry and physics explicitly, the system learns visual dynamics from synchronized video and kinematics, which is the alternative to numerical simulation the earlier release already demonstrated.
Who it affects
The release is aimed at researchers studying surgical interaction and robotics. NVIDIA invites the community to bring its own controllers, trajectories and research questions, and says the system can be adapted to other datasets and embodiments that have synchronized video and compatible action representations. The listed future directions include evaluation with surgeons and autonomous surgical policies, but those are plans, not current capabilities.
How to use it
Per NVIDIA, the model runs interactively on a single NVIDIA RTX PRO 6000 GPU through the FlashDreams streaming runtime. Developers get a four-step and a two-step checkpoint and can pick their balance between visual quality and inference cost. NVIDIA links a GitHub repository with code and examples, the Hugging Face checkpoint, Cosmos3-H-Embodied-Nano, the Open-H-Embodiment dataset, FlashDreams and Cosmos 3, plus a step-by-step recipe for teacher fine-tuning and Self-Forcing distillation on your own data. Controller integrations must use the same action conventions and normalization as training. The text gives no release date or licence terms.
How solid is it
This is a first-party NVIDIA blog post, and the "first" claim is NVIDIA's own, qualified with "to our knowledge". The post gives no frame rate, latency or throughput figure for runtime generation on the RTX PRO 6000, no quantitative visual-quality metrics, and no comparison between the four-step and two-step checkpoints. No surgeon evaluation is reported; it is listed as a future direction. The statement that the demonstrated tissue deformations are physically accurate is NVIDIA's description of its own videos, and the source does not say the deformation was verified against biomechanical measurements.
Risks and caveats
NVIDIA says visual realism is a starting point for validation, not proof of biomechanical accuracy, and that Cosmos3-H-Dreams is a research simulator, not a validated system for patient care. No clinical use or regulatory status is claimed. The simulator controls only two instruments (a left Cadiere grasper and a right monopolar hook) with limited camera commands, and the 10 Hz action sampling in training is distinct from runtime generation throughput. Fewer denoising steps cost visual quality, and error accumulation in long rollouts is a problem the pipeline works to reduce rather than one the post says is eliminated. The number, duration and source hospitals of the clinical recordings are not stated.
“Cosmos3-H-Dreams is a research simulator, not a validated system for patient care.”
— NVIDIA, Hugging Face blog post