OpenVLHarness gives multimodal models tools and memory, lifting scores 9.7-12.6 points
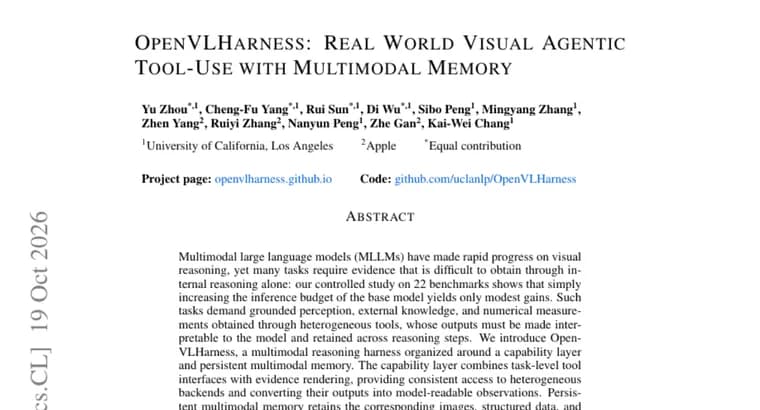
The paper starts from a problem with visual reasoning. Multimodal large language models have progressed quickly, but many tasks need evidence that is hard to get through internal reasoning alone. The authors ran a controlled study on 22 benchmarks and found that simply increasing the inference budget of the base model gives only modest gains. They do not state how large those gains are. Such tasks, the paper says, call for grounded perception, external knowledge and numerical measurements obtained through heterogeneous tools, and the tool outputs must be made interpretable to the model and kept across reasoning steps.
Their answer is OpenVLHarness, a multimodal reasoning harness built around two pieces: a capability layer and persistent multimodal memory. The capability layer pairs task-level tool interfaces with evidence rendering. It gives the model consistent access to different tool backends and converts their outputs into observations the model can read. Persistent multimodal memory keeps the relevant images, structured data and web references as addressable artifacts for the length of each query. On top of these sits a coding interface, which runs programs the model generates over the stored data, so a single computation can combine results from several tools. Together, the authors say, these mechanisms support an iterative loop of acquiring, inspecting and composing multimodal evidence.
The results come from 22 benchmarks and eight open and proprietary backbones. OpenVLHarness improves average scores by 9.7-12.6 points over matched no-tool baselines. Named examples are +11.2 with Qwen3-VL-8B, +9.7 with Kimi K3 and +9.9 with GPT-6 Astra.
A second comparison concerns cost. With GPT-6 Luna at medium reasoning effort, OpenVLHarness outperforms the base model, Codex and Visual Sketchpad, each run at maximum effort, by 7.7-8.5 points. It does so while using at most 37% of their model-token cost. In other words, the authors claim that tools plus memory at moderate effort beat the same model, or other agent setups, at full effort, at a fraction of the tokens.
Key facts
- OpenVLHarness is a multimodal reasoning harness built on a capability layer (task-level tool interfaces plus evidence rendering) and persistent multimodal memory, with a coding interface that runs generated programs over stored data.
- Evaluated on 22 benchmarks with eight open and proprietary backbones, it raises average scores by 9.7-12.6 points over matched no-tool baselines.
- Named gains over the no-tool baseline: +11.2 with Qwen3-VL-8B, +9.7 with Kimi K3, +9.9 with GPT-6 Astra.
- With GPT-6 Luna at medium reasoning effort, it beats the base model, Codex and Visual Sketchpad at maximum effort by 7.7-8.5 points, at most 37% of their model-token cost.
- The authors' controlled study on 22 benchmarks found that simply increasing the base model's inference budget yields only modest gains.
Why it matters
The paper's motivating claim is that for many visual reasoning tasks, thinking longer is not enough because the needed evidence is hard to get through internal reasoning alone. The authors' controlled study on 22 benchmarks found only modest gains from a larger inference budget. OpenVLHarness is their alternative: give the model tools, keep what the tools return in memory, and let it compute over that data. The headline result is that this beats maximum-effort baselines at medium effort for a fraction of the token cost.
Who it affects
Researchers and engineers building tool-using systems on top of multimodal models are the obvious audience. The paper evaluates eight open and proprietary backbones, so the claim is not tied to one vendor. It covers small open models such as Qwen3-VL-8B as well as proprietary ones such as GPT-6 Astra and GPT-6 Luna, and it compares against Codex and Visual Sketchpad.
How to use it
The abstract describes the design: tools exposed through task-level interfaces, outputs rendered into model-readable observations, images, structured data and web references stored as addressable artifacts, and generated programs executed over that stored data. No code, model or dataset release, license or repository is mentioned in the abstract. Anyone wanting to apply the idea would need the full paper for details on tools and setup.
How solid is it
This is a paper abstract with results reported by the authors themselves; the retelling rests on that text alone. The scope is wide, with 22 benchmarks and eight backbones, and the gains are measured against matched no-tool baselines. But the abstract gives only point gains, not absolute baseline or final scores. It does not list the 22 benchmarks or most of the eight backbones. The 9.7-12.6 range is over matched no-tool baselines, while the 7.7-8.5 margin is a separate comparison, for GPT-6 Luna only, against maximum-effort baselines. The 37% token-cost figure is an upper bound for that same comparison.
Risks and caveats
The 37% figure is stated as 'at most' and applies only to the GPT-6 Luna comparison, so it should not be read as a general saving. The size of the 'modest gains' from a larger inference budget is not given, which makes the contrast with the harness harder to judge. The abstract does not say which tools or backends are used. Gains are reported as average score differences in points, so they say little about how results vary between individual benchmarks.
“many tasks require evidence that is difficult to obtain through internal reasoning alone”
— OpenVLHarness paper abstract