ParetoRSI-Gym benchmark tests AI agents improving LLMs across five domains
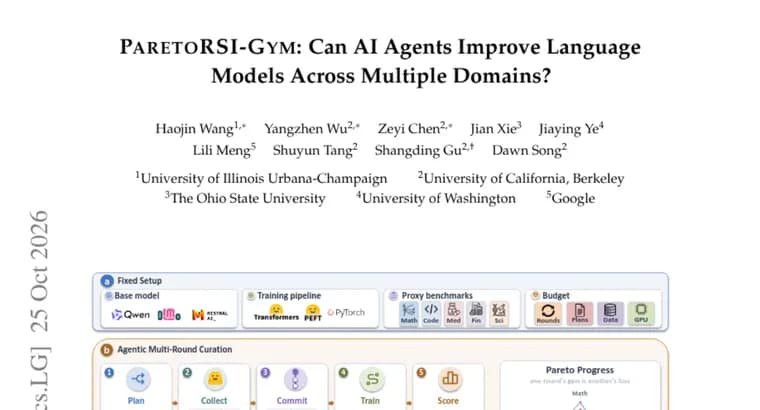
A preprint on Hugging Face Papers proposes ParetoRSI-Gym, a benchmark for agentic recursive self-improvement (RSI). The authors define RSI as an agentic system designing, training and evaluating its own successor. Data-driven post-training is a central part of that loop, they say, but existing evaluations measure it on a single benchmark, where an agent picks from a static pool of data or distills a stronger model to push one score up in one run. Real post-training is multi-domain, and a gain in one domain has to be weighed against a regression in another.
In ParetoRSI-Gym an agent searches for data, curates it, trains a model, reads back per-domain results and repeats. Everything except the data is held fixed: the initial LLM, the five domains (math, code, finance, medicine, science), the toolset and the SFT pipeline. Generalization benchmarks in each domain are meant to separate real capability gains from overfitting to the scores the agent optimizes against.
The experiments span three agent systems, three base models, five rounds and multiple seeds. The strongest system, Claude Code with Opus-5, raised the generalization scores of its proxy-best checkpoint by 9.2% relative to the starting model, or +2.3 absolute points. That figure is averaged with equal weight over the three base models and five domains. The largest single-domain result was a relative gain of up to 63%, for medicine on Ministral-3-3B.
Further analysis, according to the authors, shows that the harness matters as much as the model it drives, and that each agent keeps a unique data selection strategy. They describe the work as a step towards evaluating RSI systems in real-world machine learning engineering.
Key facts
- ParetoRSI-Gym has an agent search for data, curate it, train, read per-domain results and repeat, with the initial LLM, the toolset and the SFT pipeline held fixed.
- It covers five domains: math, code, finance, medicine and science, each with generalization benchmarks meant to separate capability gains from overfitting.
- The strongest of three agent systems, Claude Code with Opus-5, raised generalization scores by 9.2% relative (+2.3 absolute points), averaged over three base models and five domains.
- The largest single-domain relative gain was up to 63%, for medicine on Ministral-3-3B.
- The authors report that the harness matters as much as the model it drives, and that each agent keeps a unique data selection strategy.
Why it matters
The authors argue that current tests of data-driven post-training use a single benchmark, so an agent can look good by picking from a static pool or distilling a stronger model to lift one score. ParetoRSI-Gym instead asks an agent to work across five domains, where a gain in one has to be weighed against a loss in another. Separate generalization benchmarks in each domain are meant to tell real capability gains from overfitting to the scores the agent optimizes against. The authors present it as a step towards evaluating RSI systems in real-world machine learning engineering.
Who it affects
The setup is aimed at researchers who study agentic recursive self-improvement and at teams building agent harnesses for post-training work. The finding that the harness matters as much as the model it drives bears on anyone choosing between agent systems. The tested systems include Claude Code with Opus-5, and one base model named is Ministral-3-3B.
How to use it
The abstract describes the benchmark loop: the agent searches for data, curates it, trains, reads back per-domain results and repeats. The initial LLM, the five domains, the toolset and the SFT pipeline stay fixed, so differences between runs come from the data the agent chooses. Teams comparing agent systems on post-training could use the same structure. No release date, code or dataset link is stated in the abstract.
How solid is it
This is a preprint, and the account here rests on its abstract. The 9.2% relative gain (+2.3 absolute points) is for the strongest system, averaged with equal weight over three base models and five domains, across five rounds and multiple seeds. The scores of the other two agent systems are not given, nor are the names of the other two agent systems or the other two base models. The abstract does not state which benchmarks are used for the generalization or proxy scores. No absolute score for the starting models or the medicine result on Ministral-3-3B is given, only the 63% relative gain.
Risks and caveats
The 63% figure is a single-domain maximum, while the headline average is 9.2% relative, so the two should not be read as the same kind of result. The abstract names no authors or institutions. It is not stated that any agent actually improved itself; the setup evaluates agents improving a fixed base LLM through data and SFT. Without the benchmark names and the other systems' scores, the comparison between agents cannot be checked from the abstract alone.
“We see our work as a step towards evaluation of RSI systems in real-world machine learning engineering.”
— The paper's authors, in the abstract