Posterior Matching Distillation claims best 4-step FID on SDXL and FLUX.2 [klein]
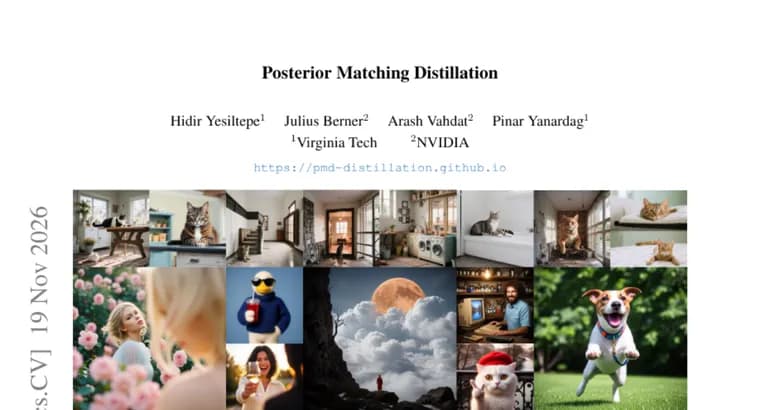
Diffusion distillation speeds up image and video generation by compressing a pretrained teacher model's iterative sampling process into a few network evaluations. One family of approaches, distribution-based methods, trains the student so that its output distribution matches the teacher's. According to the paper's abstract, that matching is often driven by reverse-KL objectives, which have a mode-seeking bias: they favor the teacher's dominant modes at the expense of diversity across samples.
The paper introduces Posterior Matching Distillation (PMD), described as a new member of the distribution-based distillation family. It combines mode-covering posterior sampling with any-step generation. The authors state that at zero population loss, PMD recovers the teacher's full posterior of clean images at each trained noise level. Its stochastic student supports any-step sampling budgets within the trained timestep grid without further training.
The mechanism works like this. To learn the posteriors, PMD matches exponentially reweighted averages of student samples, conditioned on a fixed noisy state, to the corresponding teacher posterior means. Under Gaussian corruption, the exponentially tilted posterior mean is a single teacher evaluation at a shifted input, so the target is cheap to compute. The authors prove that matching tilted means over an open neighborhood uniquely identifies the full posterior. PMD therefore supervises the entire conditional distribution through a family of mean constraints, without any auxiliary student-score network.
On results, the abstract says experiments on SDXL and FLUX.2 [klein] 4B show that PMD achieves the best FID among 4-step methods on both models. It also reports competitive or leading performance across prompt-alignment and perceptual-quality metrics. The text gives no FID values and does not name the competing 4-step methods.
Key facts
- PMD is a distribution-based diffusion distillation method that combines mode-covering posterior sampling with any-step generation.
- The authors argue that reverse-KL objectives, common in distribution matching, have a mode-seeking bias that favors dominant teacher modes and reduces sample diversity.
- PMD matches exponentially reweighted averages of student samples to teacher posterior means, and needs no auxiliary student-score network.
- The authors prove that matching tilted means over an open neighborhood uniquely identifies the full posterior.
- On SDXL and FLUX.2 [klein] 4B, PMD reports the best FID among 4-step methods on both models, with competitive or leading prompt-alignment and perceptual-quality results.
Why it matters
Distillation is how large diffusion models are made fast enough to use, by cutting sampling to a handful of network evaluations. The known weak spot the paper targets is diversity: reverse-KL matching tends to favor the teacher's dominant modes. PMD is pitched as a way to keep the full range of the teacher's outputs while still sampling in few steps. It does this with mean constraints rather than an extra student-score network.
Who it affects
Mainly researchers and engineers working on diffusion distillation and few-step image generation. The reported experiments use SDXL and FLUX.2 [klein] 4B as teachers, so people who build on or compress those models are the closest audience.
How to use it
The abstract describes a training method, not a product. Its practical selling point is that the stochastic student supports any-step sampling budgets within the trained timestep grid without further training, so one trained student can be run at different step counts inside that grid. No code release, training cost or inference speed figures are mentioned in the text.
How solid is it
The claims come from the paper's own abstract, and the best-FID result is limited to 4-step methods on SDXL and FLUX.2 [klein] 4B. Prompt-alignment and perceptual-quality results are described only as competitive or leading, not best across the board. The abstract gives no FID values and does not name the competing methods, so the size of the margin cannot be judged from it. The paper also states a theoretical result: the authors prove that matching tilted means over an open neighborhood uniquely identifies the full posterior. The full-posterior recovery holds at zero population loss, an idealised condition.
Risks and caveats
FID is a single distributional metric, and the claim covers only 4-step methods, not other step counts. Recovery of the teacher's full posterior is stated for zero population loss, which a trained student will not reach exactly. The student also samples only within the trained timestep grid. Independent replication and comparisons beyond the two named models are not part of what the abstract reports.
“PMD thus supervises the entire conditional distribution through a family of mean constraints, without any auxiliary student-score network.”
— Paper abstract, Posterior Matching Distillation