Tavus says its Griffin video avatar passed as human for 48% of testers
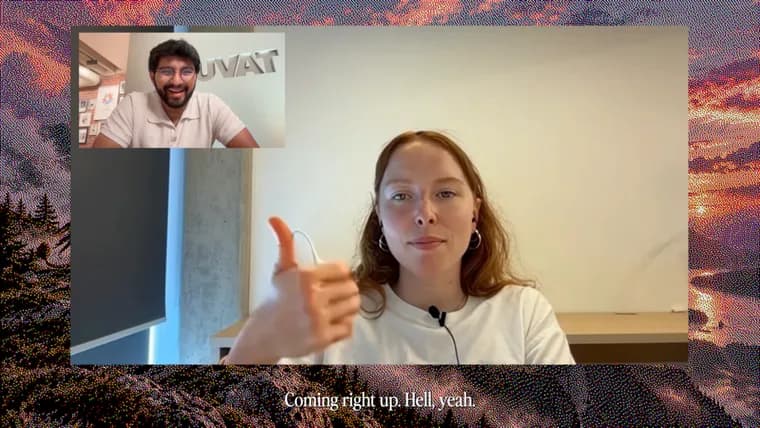
Tavus, a San Francisco AI startup, has introduced Griffin, which the company calls the first "Human Interaction Model" (HIM). Tavus describes this as a class of model designed to understand and carry on face-to-face conversations in real time. Griffin processes speech, facial expressions, tone of voice, gestures, and pauses while both receiving and generating video.
The headline result comes from a Tavus study: 48 percent of participants believed Griffin was a real person after a one-minute video call. Previous systems maxed out at two percent on the same kind of test.
Tavus also points to a second measurement, which it describes as an independent Nvidia test of how human an AI feels in direct audio-video conversation. Griffin scored 3.83 points. Actual humans scored 3.92, and the previous best AI model hit 2.80.
Availability is limited. A preview called Griffin-Lite is open to "select testers as a research preview," and a more capable version is coming once "safety concerns are addressed." Tavus lists tutoring, practicing difficult conversations, and camera-based tech support as potential use cases.
Tavus was founded in 2020 and has raised about $64 million. It started out building personalized AI videos for sales and marketing, then expanded into live video conversations with digital personas. Further details on Griffin are in the Tavus research report.
Key facts
- In a Tavus study, 48 percent of participants believed Griffin was a real person after a one-minute video call; previous systems maxed out at two percent.
- In what Tavus describes as an independent Nvidia test, Griffin scored 3.83 points, against 3.92 for actual humans and 2.80 for the previous best AI model.
- Griffin is billed as the first "Human Interaction Model": it processes speech, facial expressions, tone of voice, gestures and pauses while receiving and generating video.
- Only a preview, Griffin-Lite, is available, to select testers; a more capable version is planned once safety concerns are addressed.
- Tavus, founded in 2020 in San Francisco, has raised about $64 million.
Why it matters
The reported jump is large: 48 percent of participants took Griffin for a real person after a one-minute video call, where previous systems maxed out at two percent. On the Nvidia-described test, Griffin's 3.83 sits close to the 3.92 scored by actual humans and well above the 2.80 of the previous best AI model. If the figures hold up, real-time video avatars would be much harder to tell apart from people in a short face-to-face call. Tavus also frames Griffin as a new model class, a Human Interaction Model, rather than a video generator: it takes in speech, expressions, tone, gestures and pauses while producing video of its own.
Who it affects
Tavus names three potential uses: tutoring, practicing difficult conversations, and camera-based tech support. Those point to learners, people rehearsing hard talks and customer-support users. Anyone who joins video calls is also affected in a broader sense, since the headline result is that nearly half of participants in the study could not tell Griffin from a person. For Tavus itself, Griffin extends a path from personalized AI videos for sales and marketing to live conversations with digital personas.
How to use it
Access is narrow for now. Griffin-Lite, a preview, is available to select testers as a research preview. A more capable version is to follow once safety concerns are addressed, and no release date is given for it. No pricing or general availability is given for Griffin or Griffin-Lite. Further technical detail is in the Tavus research report.
How solid is it
The headline figures come from Tavus. The 48 percent result is from a Tavus study, and the Nvidia test is described only as "what Tavus describes as an independent Nvidia test," so the article does not independently confirm Nvidia's role. The number of participants in the Tavus study is not given. The source does not say who the participants were or how the study was run beyond a one-minute video call. It does not say what the Nvidia test scale is or how the scores were measured, and it does not name which previous systems scored two percent or 2.80. The numbers are best read as vendor-reported until the research report or outside testing backs them.
Risks and caveats
The limited rollout is tied to safety: Tavus says a more capable version will come once "safety concerns are addressed," and the source does not specify what those concerns are. The result itself is a short-call result, one minute, so it says little about longer conversations. Humans still edge Griffin on the Nvidia-described test, 3.92 to 3.83. A system that nearly half of a study's participants took for a real person raises an obvious question about how such avatars should be disclosed, though the article does not discuss that.
“Griffin processes speech, facial expressions, tone of voice, gestures, and pauses while both receiving and generating video.”
— The Decoder, describing Griffin