WideSWE benchmark: best coding agent solves 42.50% of multi-repo tasks
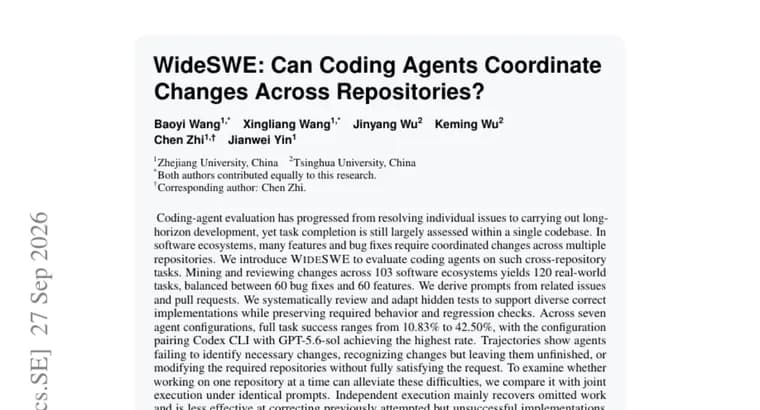
Most coding-agent evaluation still measures task completion inside a single codebase, even though the authors note that in software ecosystems many features and bug fixes require coordinated changes across multiple repositories. WideSWE is their attempt to test agents on exactly that kind of work.
To build it, the authors mined and reviewed changes across 103 software ecosystems, which produced 120 real-world tasks: 60 bug fixes and 60 features. Prompts are derived from related issues and pull requests. The hidden tests were systematically reviewed and adapted so that they accept diverse correct implementations while still preserving the required behavior and regression checks.
The authors evaluated seven agent configurations. Full task success ranged from 10.83% to 42.50%. The top result came from the configuration pairing Codex CLI with GPT-5.6-sol.
Looking at agent trajectories, the authors describe three failure patterns: agents failing to identify the necessary changes, recognizing changes but leaving them unfinished, or modifying the required repositories without fully satisfying the request.
They also asked whether working on one repository at a time could ease these difficulties, and compared that independent execution with joint execution under identical prompts. Independent execution mainly recovers omitted work and is less effective at correcting implementations that were attempted but unsuccessful. Joint execution can use information from related repositories to guide implementation and verification. The code is available on GitHub under the ZJU-ACES-ISE organisation.
Key facts
- WideSWE contains 120 real-world tasks, 60 bug fixes and 60 features, mined and reviewed across 103 software ecosystems.
- Across seven agent configurations, full task success ranges from 10.83% to 42.50%; Codex CLI with GPT-5.6-sol scores highest.
- Observed failures: missing necessary changes, leaving recognized changes unfinished, or editing the right repositories without fully meeting the request.
- Independent, one-repository-at-a-time execution mainly recovers omitted work but is less effective at fixing unsuccessful attempts; joint execution can use information from related repositories.
- Hidden tests were reviewed and adapted to accept diverse correct implementations while keeping required behavior and regression checks.
Why it matters
The authors argue that coding-agent evaluation has moved from resolving individual issues to long-horizon development, yet success is still mostly judged within one codebase. Real features and bug fixes in software ecosystems often span several repositories. WideSWE targets that gap, and its headline result is sobering: even the best of the seven configurations, Codex CLI with GPT-5.6-sol, fully completes 42.50% of tasks.
Who it affects
Teams building or evaluating coding agents get a benchmark for cross-repository work. Developers who maintain code spread over related repositories are the ones whose everyday tasks the benchmark is meant to reflect.
How to use it
The authors released the code at https://github.com/ZJU-ACES-ISE/WideSWE. The task set can be used to test an agent on changes that touch multiple repositories. The independent versus joint comparison suggests running an agent across related repositories together rather than one at a time, since joint execution can use information from related repositories to guide implementation and verification.
How solid is it
The description reads as an abstract-level summary of the paper. The benchmark is built from real issues and pull requests, and the hidden tests were systematically reviewed and adapted to accept diverse correct implementations. The source does not list the other six agent configurations or their individual success rates, and no numbers are given for the independent versus joint execution comparison, so those findings are stated only qualitatively.
Risks and caveats
With 120 tasks, the benchmark is small, and the 10.83% to 42.50% range covers only seven configurations. The source does not say which configuration scored 10.83%, and it gives no split of success rates between bug fixes and features. The claim that joint execution helps is worded as a capability (it can use information from related repositories), not as a measured gain.
“Independent execution mainly recovers omitted work and is less effective at correcting previously attempted but unsuccessful implementations.”
— WideSWE authors