Code-Only-as-Policy (COAP) paper drives robots with code, no VLM or VLA at test time
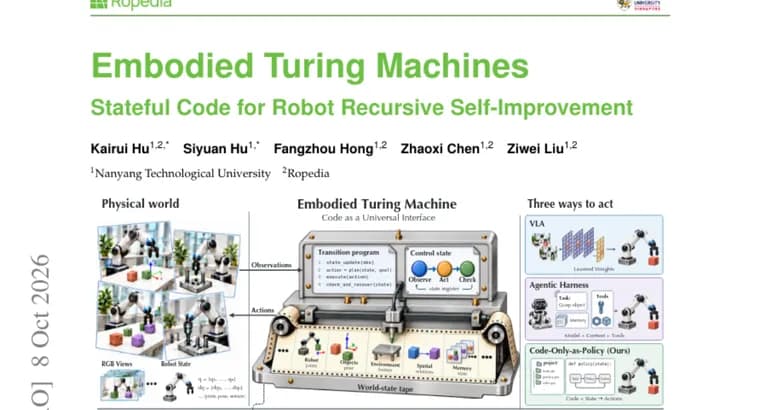
Most robot policies keep a model in the control loop. A vision-language-action model (VLA) maps observations to actions, and an Agent Harness, such as Agent-as-Policy or Harness VLA, queries a vision-language model (VLM) for decision making at run time. The paper, titled Embodied Turing Machines, proposes a different view: the embodied world is an Embodied Turing Machine, whose tape is the robot and environment state and whose rules are the policy.
From that view the authors draw a conditional claim: if the state can be represented accurately, decision making can be written entirely in code. They call the result Code-Only-as-Policy (COAP). In COAP, code measures and tracks the robot, environment and task state from camera images and proprioception, and makes every decision from it. The same code applies across episodes, and different tasks share one library, with no VLM or VLA in the loop.
Compared with VLAs and Agent Harnesses, the authors analyze three advantages. Explicit State: the state can be stored in code. Execution: code makes decision making controllable, recovers from failures flexibly, and runs fast and cheaply online. Extensibility: new tasks reuse, inherit, or extend the shared library, so capabilities can accumulate over tasks.
The authors say these advantages make COAP a suitable medium for recursive self-improvement (RSI). Coding agents develop the library in a closed loop, and each change is explicit and controllable. On RoboDojo's 42 bimanual tasks, the resulting library reaches a success rate of 70.24% without a model at test time.
The authors state the limit of the approach plainly: the upper bound of COAP lies in how accurately the state is represented for decision making and how robust the code logic is. They propose COAP as a new paradigm for embodied tasks, and add that because it applies across episodes, it can also serve as an efficient data engine for VLAs and Agent Harnesses.
Key facts
- COAP (Code-Only-as-Policy) writes robot decision making entirely in code that tracks robot, environment and task state from camera images and proprioception, with no VLM or VLA in the loop at test time.
- On RoboDojo's 42 bimanual tasks, the resulting code library reaches a 70.24% success rate without a model at test time.
- The authors analyze three advantages over VLAs and Agent Harnesses: Explicit State, Execution, and Extensibility.
- Coding agents develop the library in a closed loop, which the authors present as recursive self-improvement with each change explicit and controllable.
- By the authors' own account, COAP's upper bound depends on how accurately the state is represented and how robust the code logic is.
Why it matters
Most current robot policies depend on a model at run time: a VLA maps observations to actions, or an Agent Harness queries a VLM for each decision. This paper argues the model can be taken out of the loop when the robot, environment and task state can be tracked accurately in code. The authors present COAP as a new paradigm for embodied tasks and report a 70.24% success rate on RoboDojo's 42 bimanual tasks without a model at test time.
Who it affects
Mainly robotics and embodied-AI researchers who build or evaluate VLAs and Agent Harnesses. The authors also say COAP can serve as an efficient data engine for those systems, since the same code applies across episodes.
How to use it
The abstract describes the method rather than a recipe. Code measures and tracks the robot, environment and task state from camera images and proprioception, and makes every decision from that state. Different tasks share one library, and new tasks reuse, inherit, or extend it. Coding agents develop the library in a closed loop, with each change explicit and controllable.
How solid is it
This is a paper abstract, and the 70.24% figure is the authors' own result on RoboDojo's 42 bimanual tasks. The abstract names no authors or institutions. No baseline success rates for VLAs or Agent Harnesses on RoboDojo are given, so the 70.24% has no stated comparison. It does not say whether the evaluation was in simulation or on physical robots, and it does not report results of the recursive self-improvement loop itself, such as number of iterations or gains per iteration.
Risks and caveats
The authors say the upper bound of COAP lies in how accurately the state is represented for decision making and how robust the code logic is. The approach also rests on a condition: decision making can be written in code only if the state can be represented accurately. The claims that code runs fast and cheaply online come with no figures for speed, latency or cost. The abstract also does not say which coding agents or underlying models were used to develop the library, or how many episodes or trials per task were run.
“the embodied world is an Embodied Turing Machine, whose tape is the robot and environment state and rules are the policy”
— From the paper's abstract