DecisionRank trains a 1.7B reranker that beats its 27B teacher on TREC DL
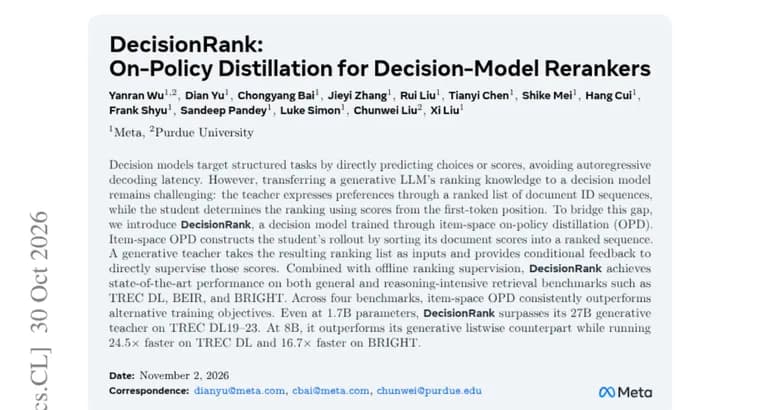
The paper tackles a mismatch in how rerankers are built. Decision models predict choices or scores directly, which avoids the latency of autoregressive decoding. But moving ranking knowledge from a generative LLM into such a model is hard. The teacher expresses its preferences as a ranked list of document ID sequences, while the student decides the ranking from scores at the first-token position.
To bridge that gap, the authors introduce DecisionRank, a decision model trained through item-space on-policy distillation (OPD). The method works in two steps. First, the student's rollout is built by sorting its own document scores into a ranked sequence. Second, a generative teacher takes that ranking list as input and gives conditional feedback, which directly supervises the student's scores. Training combines this with offline ranking supervision.
The reported results: DecisionRank reaches state-of-the-art performance on both general and reasoning-intensive retrieval benchmarks, such as TREC DL, BEIR and BRIGHT. Across four benchmarks, item-space OPD consistently outperforms alternative training objectives. Even at 1.7B parameters, DecisionRank surpasses its 27B generative teacher on TREC DL19-23. At 8B, it outperforms its generative listwise counterpart while running 24.5 times faster on TREC DL and 16.7 times faster on BRIGHT.
The source is the paper's abstract. It gives qualitative outperformance and speed factors, not metric values, and it does not name the teacher or the base models.
Key facts
- DecisionRank is a decision model, one that predicts scores directly rather than generating text, trained through item-space on-policy distillation (OPD) from a generative LLM teacher.
- In item-space OPD the student's rollout is its document scores sorted into a ranked sequence; the teacher reads that ranking and gives conditional feedback that supervises the scores.
- The authors report state-of-the-art results on TREC DL, BEIR and BRIGHT when OPD is combined with offline ranking supervision.
- At 1.7B parameters, DecisionRank surpasses its 27B generative teacher on TREC DL19-23.
- At 8B, it outperforms its generative listwise counterpart while running 24.5 times faster on TREC DL and 16.7 times faster on BRIGHT.
Why it matters
Generative LLM rerankers produce a ranked list of document IDs token by token, and autoregressive decoding adds latency. Decision models avoid that by predicting scores directly. The hard part, as the authors describe it, is that teacher and student express ranking differently: the teacher gives a ranked list of document ID sequences, the student scores from the first-token position. DecisionRank is their answer, and the reported result is a small student that matches or beats a much larger teacher on one benchmark family while running much faster than its generative counterpart.
Who it affects
The work is aimed at people building retrieval and reranking pipelines, especially those who want listwise ranking quality without the decoding cost of a generative reranker. It is also relevant to researchers working on distillation, since it applies on-policy distillation to a ranking task where the student's output is a score rather than generated text.
How to use it
The abstract describes a training recipe, not a product. The recipe: sort the student's document scores into a ranked sequence, pass that ranking to a generative teacher, and use the teacher's conditional feedback to supervise the scores, alongside offline ranking supervision. No code or model release is mentioned in the source, so a team wanting to try it would have to wait for more material or reimplement the method.
How solid is it
All claims come from the authors' own abstract, and the source text is that abstract alone. The benchmarks named are standard ones: TREC DL, BEIR and BRIGHT. The claim that item-space OPD beats alternative training objectives is stated for four benchmarks. The source gives no metric values such as nDCG@10, so the size of the state-of-the-art margin is not stated. The speed factors (24.5 times and 16.7 times) come without any statement of whether they are mean, median or maximum, or of the hardware used.
Risks and caveats
The 1.7B model's win over the 27B teacher is stated only for TREC DL19-23; the abstract does not say the same holds on BEIR or BRIGHT. The abstract does not name the 27B teacher or the base models behind the 1.7B and 8B students, which makes the comparison hard to place. The speed comparison is against a generative listwise counterpart at 8B, and its measurement conditions are not given. Independent replication is not mentioned.