EgoX pretrains one robot policy on human, robot and simulated demos
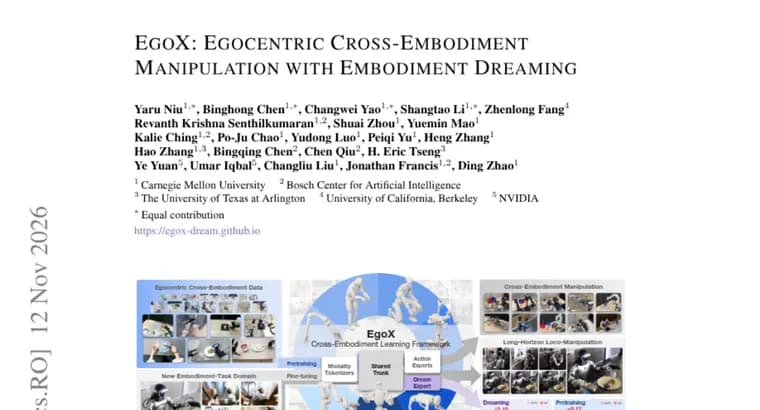
The paper starts from a premise: generalist manipulation policies can benefit from the complementary experience of humans, real robots and simulated agents. The obstacle is that differences in morphology, sensing and control interfaces make it hard to learn effectively from all of those demonstrations combined.
The proposed answer is EgoX, an egocentric cross-embodiment learning framework. It organizes heterogeneous demonstrations through semantically corresponding observation and action modalities. EgoX pretrains a model called the Modularized Cross-Embodiment Transformer with Embodiment Dreaming (MXT+) on this mixture, then fine-tunes it on demonstrations from the target embodiment.
The architecture is modular. Within each embodiment, MXT+ assigns a dedicated tokenizer to each observation modality and a dedicated expert to each action modality. A Transformer trunk is shared across all embodiments. On top of that sits the embodiment-dreaming objective, which is used only during training. It predicts latent representations of future visual and proprioceptive states, which encourages the shared trunk to model each embodiment's dynamics.
The evaluation covers 13 task-embodiment pairs, spanning five tasks and six robot embodiments: five physical robots and one simulated humanoid. Cross-embodiment pretraining raises MXT+'s average normalized task progress from 0.63 to 0.80 over training from scratch. The gains are particularly pronounced under out-of-distribution conditions, where average task progress increases from 0.53 to 0.77.
Ablations demonstrate the benefits of broader pretraining mixtures, modular interfaces and embodiment dreaming. Dreaming also produces more similar latent geometry across embodiments. The paper points to a project page at egox-dream.github.io.
Key facts
- EgoX pretrains MXT+ (Modularized Cross-Embodiment Transformer with Embodiment Dreaming) on mixed human, real-robot and simulated-agent demonstrations, then fine-tunes it on the target embodiment.
- Each embodiment gets a dedicated tokenizer per observation modality and a dedicated expert per action modality, with one Transformer trunk shared across embodiments.
- Average normalized task progress rises from 0.63 to 0.80 versus training from scratch, across 13 task-embodiment pairs (five tasks, six embodiments: five physical robots and one simulated humanoid).
- Under out-of-distribution conditions, average task progress goes from 0.53 to 0.77.
- The embodiment-dreaming objective is training-only and predicts latent representations of future visual and proprioceptive states.
Why it matters
Robot learning has a data problem: demonstrations come from humans, physical robots and simulators, and each source differs in body shape, sensors and control interface. The paper argues these sources are complementary, but that the differences make combined learning difficult. EgoX is an attempt to make one shared model useful across all of them, using per-modality tokenizers and experts around a common trunk, plus a training-only objective that predicts future latent states.
Who it affects
The work is aimed at researchers building generalist manipulation policies that must work across different robot bodies. The evaluation spans five physical robots and one simulated humanoid, so the setting is multi-embodiment robotics rather than a single arm or platform.
How to use it
The abstract names a project page, egox-dream.github.io. The abstract does not state whether code or models are released. The recipe it describes is: pretrain MXT+ on a mixture of human, real-robot and simulated demonstrations, then fine-tune on demonstrations from the target embodiment.
How solid is it
The headline result is measured: across 13 task-embodiment pairs, average normalized task progress goes from 0.63 to 0.80 with cross-embodiment pretraining, and from 0.53 to 0.77 under out-of-distribution conditions. These are absolute scores, not percentages. Ablations are reported to support broader pretraining mixtures, modular interfaces and embodiment dreaming. This is a preprint summary based on the abstract, so the underlying experiments are not visible here.
Risks and caveats
Results are reported for MXT+ only; no comparison with other published methods is stated. The abstract does not name the five tasks or the specific robot models. It does not give the amount of human, real-robot or simulated demonstration data used in pretraining. It does not say how normalized task progress is computed or its scale beyond the 0.63 and 0.80 values. Individual ablation results are not quantified.
“Generalist manipulation policies can benefit from the complementary experience of humans, real robots, and simulated agents.”
— EgoX paper abstract