FDE-Gym benchmark: best of 13 AI agent setups resolves only 14 of 95 delivery tasks
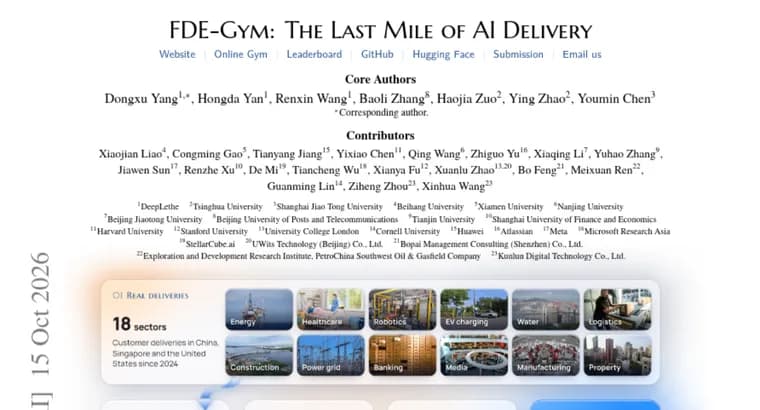
A new paper introduces FDE-Gym, a benchmark built to test whether AI agents can do the job of a forward-deployed engineer (FDE). The authors argue that existing agent benchmarks typically evaluate agents on well-specified tasks defined by issue reports, specifications, or task tickets. Real customer delivery is different: FDEs must clarify ambiguous requirements, work in live systems, and uncover unstated constraints.
FDE-Gym contains 95 end-to-end delivery tasks drawn from 20 customer scenarios across 18 sectors. Each task was adapted by industry experts from real-world delivery projects. Agents work in simulated customer environments with scripted stakeholders and modifiable customer systems. They talk to the stakeholders and operate on production-like systems to deliver a working solution.
Scoring is tied to the customer's own success metric. A delivery is rated by how much it improves that metric, normalized between 0 (the unchanged system) and 1 (the reference solution). Penalties apply for stakeholder interactions: messages, trial runs, and waiting time. The paper also describes an online platform where humans can practice FDE skills under the same grading criteria.
The authors evaluated 13 model configurations from seven providers. In the realistic setting, where unstated constraints must be discovered, the best configuration reaches a mean FDE-Gym score of 0.56. It resolves only 14 of the 95 tasks, where resolved means a score of at least 0.8 with no incident.
The authors identify discovering unstated constraints as the primary bottleneck: performance drops sharply when models must uncover them without explicit guidance. But finding information is not the whole story. On the 23 tasks where the best configuration obtains every key fact from stakeholders, it reaches a normalized business uplift of 0.8 or above on only 10. The authors conclude that the results reveal a substantial gap between solving well-specified tasks and delivering effective AI systems for real customers.
Key facts
- FDE-Gym has 95 end-to-end delivery tasks from 20 customer scenarios across 18 sectors, each adapted by industry experts from real delivery projects.
- Across 13 model configurations from seven providers, the best one gets a mean score of 0.56 (0 is the unchanged system, 1 is the reference solution) in the realistic setting.
- That configuration resolves only 14 of 95 tasks, with resolved meaning a score of at least 0.8 and no incident.
- Discovering unstated constraints is named as the primary bottleneck: performance drops sharply without explicit guidance.
- Even on the 23 tasks where the best configuration gets every key fact from stakeholders, it reaches a business uplift of 0.8 or above on only 10.
Why it matters
Most agent benchmarks hand the agent a clear ticket or specification. FDE-Gym instead models the messier work of putting AI into a customer's live system: ambiguous requirements, stakeholders who must be questioned, and constraints nobody states. The best result, 14 of 95 tasks resolved, points to a large distance between benchmark success on well-specified tasks and delivering systems that work for real customers. The 10-of-23 result adds a second finding: knowing all the key facts is not enough to deliver the outcome.
Who it affects
Teams building or buying AI agents for customer deployments, and the forward-deployed engineers who do that work today. Benchmark builders are also affected, since the paper argues that ticket-style evaluation misses what delivery requires. The tasks span 18 sectors.
How to use it
The paper describes an online platform where humans can practice FDE skills under the same grading criteria as the agents. It does not say whether the benchmark, code, or platform are publicly released or give a link. For a reader, the practical use is as a yardstick: scores are normalized from 0 (unchanged system) to 1 (reference solution), with penalties for messages, trial runs, and waiting time.
How solid is it
The numbers come from the authors' own abstract on Hugging Face Papers: 13 configurations from seven providers, 95 tasks, a best mean score of 0.56 and 14 tasks resolved. The tasks were adapted by industry experts from real delivery projects, but the environments and stakeholders are simulated and scripted. The abstract does not name the authors or their institutions, and it does not name the best-performing model or configuration, nor the seven providers. No human baseline scores are given for the online practice platform.
Risks and caveats
The headline figures apply to the realistic setting, where unstated constraints must be discovered. The abstract gives no scores for the non-best configurations and no score for the setting where constraints are explicitly guided, so the size of the drop cannot be read from it. The 14-of-95 figure depends on the authors' definition of resolved (at least 0.8, no incident). Scores are tied to a normalized business metric against a reference solution, so they are specific to this benchmark's design.
“These results reveal a substantial gap between solving well-specified tasks and delivering effective AI systems for real customers.”
— FDE-Gym paper abstract