Gamer agent framework learns 2D and 3D games from keyboard and mouse data
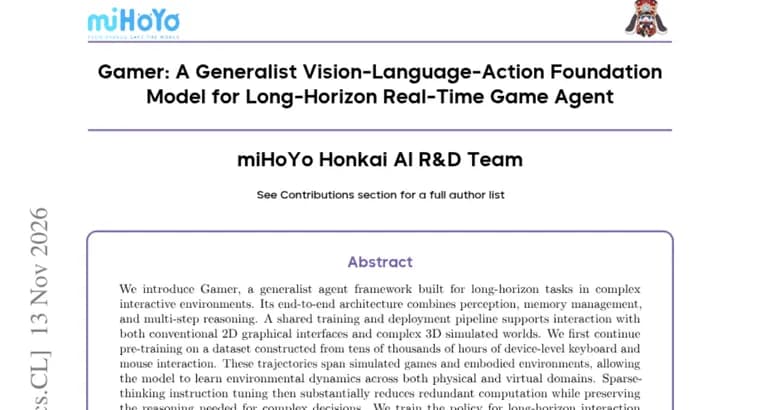
The paper introduces Gamer, a generalist agent framework built for long-horizon tasks in complex interactive environments. Its end-to-end architecture combines perception, memory management and multi-step reasoning. One training and deployment pipeline covers both conventional 2D graphical interfaces and complex 3D simulated worlds.
Training runs in stages. First, the model continues pre-training on a dataset built from tens of thousands of hours of device-level keyboard and mouse interaction. These trajectories span simulated games and embodied environments, so the model can learn how environments behave in both physical and virtual domains. Next comes sparse-thinking instruction tuning, which the authors say substantially reduces redundant computation while keeping the reasoning needed for complex decisions.
The policy is then trained for long-horizon interaction with a multi-turn reinforcement learning method the authors describe as stable. It is designed to handle three problems: finite context windows, accumulated rollout errors and sparse rewards.
For real-time play, the authors describe a cloud-edge inference engine. It serves numerous simulated game environments concurrently, supports unbounded-context execution and keeps online inference latency low.
On results, the authors report that across multiple challenging 3D open-world games Gamer shows solid generalization and operational efficiency comparable to skilled players. On a range of conventional 2D game benchmarks it achieves competitive results. They conclude that even repetitive keyboard and mouse trajectories can support substantial gains from scaling data and learning algorithms, and that training on them helps Gamer learn complex skills more steadily in environments with both physical and digital properties. They present the approach as a path toward generalist agents that interact across digital and physical worlds.
Key facts
- Gamer is a generalist vision-language-action agent framework for long-horizon tasks, combining perception, memory management and multi-step reasoning end to end.
- It continues pre-training on tens of thousands of hours of device-level keyboard and mouse interaction from simulated games and embodied environments.
- Training adds sparse-thinking instruction tuning and a multi-turn reinforcement learning method aimed at finite context windows, accumulated rollout errors and sparse rewards.
- A cloud-edge inference engine serves many simulated game environments at once, supports unbounded-context execution and keeps online latency low.
- The authors report operational efficiency comparable to skilled players in multiple 3D open-world games and competitive results on 2D game benchmarks.
Why it matters
The paper argues that raw keyboard and mouse logs, even repetitive ones, can be scaled into a general-purpose agent that works across 2D interfaces and 3D worlds. If that holds, a single pipeline could cover both digital and physical-style environments. The authors frame the work as a path toward generalist agents that interact across digital and physical worlds.
Who it affects
Researchers building game-playing and interface-control agents are the closest audience, especially those working on long-horizon reinforcement learning and real-time inference. Teams that need agents to handle both graphical interfaces and simulated 3D worlds may also find the shared pipeline relevant.
How to use it
The abstract describes a recipe rather than a product: continued pre-training on keyboard and mouse trajectories, then sparse-thinking instruction tuning, then multi-turn reinforcement learning, served through a cloud-edge inference engine. No release of code, weights or data is mentioned.
How solid is it
This is a preprint abstract, and the claims are the authors' own. The 3D result is described only as 'comparable to skilled players'. No benchmark names, scores, success rates or latency figures are given. The names of the 3D open-world games and 2D benchmarks are not given either, and no comparison against named baselines or other models is given.
Risks and caveats
Without numbers, baselines or named games, the headline claims cannot be checked from the abstract. No model size, parameter count or base model is stated, and the dataset is sized only as 'tens of thousands of hours'. The source does not say whether any evaluation was done on real physical robots or hardware, so the physical-world framing refers to embodied environments in the training data.
“These results suggest that even repetitive keyboard and mouse trajectories can support substantial gains from scaling data and learning algorithms.”
— Gamer paper abstract