Google Research's Diffusion Controller steers image models with a small add-on network
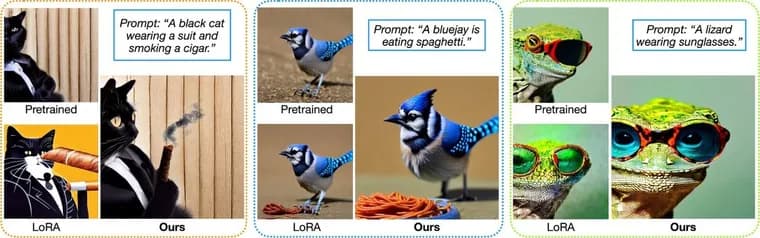
On September 29, 2026, Google Research software engineers Chih-wei Hsu and Moonkyung Ryu introduced Diffusion Controller, a framework for steering text-to-image diffusion models toward what the user actually asked for.
The problem they start from: models such as Nano Banana, Stable Diffusion and Flux can produce photorealistic images from text, but meeting precise intent is a delicate balancing act. Their example is the prompt "a lizard wearing sunglasses". The model may produce a realistic lizard with no sunglasses. Forcing the sunglasses in may distort the lizard's face and ruin the image.
The authors say existing control methods are disconnected. On one side are inference-time techniques such as classifier-free diffusion guidance, which adjust the prompt's influence on the fly. On the other are heavy fine-tuning approaches: parameter-efficient adapters like LoRA, reward-weighted regressions, or policy gradients. Because these have been treated as separate fixes, the authors say the field has lacked one principled mathematical language to unify, analyze and optimize control of generative models, and engineers end up guessing when trading prompt alignment against image quality.
Diffusion Controller reframes the whole denoising process (noise gradually refined into a clear picture) as a smooth, continuous control problem. The base pre-trained model stays completely frozen. The authors compare it to a motorcycle whose engine is left alone while a lightweight steering damper is attached. The damper network observes the image as it is being cleared of static and injects small corrections to the generation trajectory. It recalibrates the model's default behavior, giving more weight to directions that maximize a user-defined target, such as an artistic style or contextual alignment. A penalty guardrail keeps the result close to the base model, so in the lizard example the sunglasses appear without the scales and proportions being distorted.
To make the control formulation practical, the authors derived two efficient fine-tuning methods that rely entirely on a final reward score. They say they implemented four network structures under the framework, though the post does not describe them. The pitch for closed models: normally changing a model's behavior needs white-box access to internal weights, but the best image models are often corporate secrets (black or gray boxes). The steering damper is meant to let engineers control and customize even tightly locked closed-source models without touching the underlying code.
Evaluation used a Stable Diffusion v1.4 backbone across three fine-tuning regimes: supervised fine-tuning (SFT), reward-weighted loss (RWL) and PPO. Performance was measured with the Human Preference Score (HPS-v2). The authors report that the framework works in both fully accessible white-box settings and restrictive gray-box settings, consistently beating its corresponding baselines with a better quality-efficiency trade-off. The fully unlocked version, fine-tuned with white-box access, achieved a 90% win rate over the baseline model. In the SFT and RWL tracks, the gray-box steering damper outperformed LoRA, described as the state-of-the-art parameter-efficient white-box approach, in win rates, while manipulating significantly fewer internal model layers. In human evaluation panels, Diffusion Controller recorded the best subjective quality and prompt-matching results across complex, multi-attribute prompts.
At runtime, a single inference-time guidance strength parameter lets users dial the intensity of the control constraints up or down, adjusting prompt alignment without breaking baseline image stability or causing the distortions the authors associate with older guidance methods.
Stated next steps are personalization tools, safety mechanisms to help mitigate harmful content generation, and adapting the steering damper to next-generation video models. The authors thank co-authors and collaborators from Google Research, Google DeepMind and academia.
Key facts
- Diffusion Controller is a lightweight "steering damper" network that attaches to a frozen base text-to-image model and is meant to work even with access-restricted, closed-source models.
- It treats denoising as a continuous control problem, unifying inference-time guidance and fine-tuning methods (LoRA, reward-weighted regression, policy gradients) under one framework.
- Tested on a Stable Diffusion v1.4 backbone across SFT, RWL and PPO, scored with HPS-v2; the fully unlocked white-box version reached a 90% win rate over the baseline model.
- In the SFT and RWL tracks, the gray-box version beat LoRA in win rates while manipulating significantly fewer internal model layers.
- A single inference-time guidance strength parameter lets users raise or lower the control intensity at runtime.
Why it matters
Steering image models toward a precise prompt without wrecking image quality is a familiar trade-off: add the sunglasses and the lizard's face warps. The authors say guidance and fine-tuning methods have been treated as unrelated fixes, and Diffusion Controller offers one control-theory framing for both. The practical hook is access. If a small network can steer a frozen model from the outside, teams could tune models they cannot open up, which the authors call a massive real-world business problem.
Who it affects
Mainly researchers and engineers who build on or fine-tune text-to-image models. The post is aimed at people who work with models where weights are restricted, since those users can normally only prompt or apply guidance. The authors also point to future work on personalization tools and video models.
How to use it
The post is a research announcement. It describes no release and no product integration or availability plans at Google. It also names no code or model release. What it does describe for practitioners: a steering damper network trained against a final reward score using one of two derived fine-tuning methods, with the base model left frozen, and a single guidance strength parameter at inference time to dial the control up or down.
How solid is it
The claims are the authors' own, in a Google Research blog post by two software engineers. The evaluation is on a Stable Diffusion v1.4 backbone with three fine-tuning regimes (SFT, RWL, PPO), scored with HPS-v2, plus human evaluation panels. The 90% win rate is tied only to "the baseline model"; the exact comparison is not specified. No numerical HPS-v2 scores, gray-box win rates or LoRA comparison figures are given, and the industry standard that was outperformed is not named. The four network structures and the two fine-tuning methods are announced but not described.
Risks and caveats
No closed-source model is reported as actually tested; the experiments are stated only on Stable Diffusion v1.4, so the claim that it works on closed models is not shown by results in the post. No compute cost, parameter counts or number of layers are given, so the efficiency claims cannot be checked from the text. The authors list safety mechanisms to help mitigate harmful content generation as a future step, which means they are not part of the current work.