GTAGym turns GTA V into an agent benchmark and RL environment
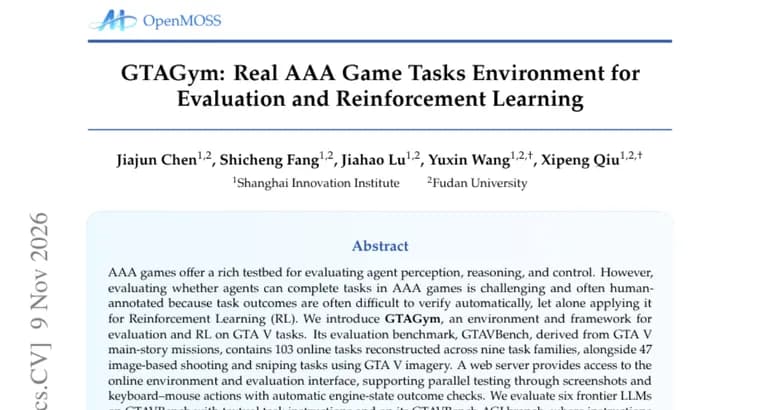
A paper introduces GTAGym, an environment and framework for evaluating agents, and for running reinforcement learning (RL), on tasks in GTA V. The authors start from a problem: AAA games are a rich testbed for agent perception, reasoning and control, but checking whether an agent actually finished a task is hard to do automatically, so evaluation is often annotated by humans. That also makes RL on such games difficult.
The evaluation benchmark, GTAVBench, is derived from GTA V main-story missions. It contains 103 online tasks reconstructed across nine task families, plus 47 image-based shooting and sniping tasks that use GTA V imagery. A web server gives access to the online environment and the evaluation interface. It supports parallel testing: agents see screenshots and act through keyboard and mouse, and outcomes are checked automatically against the state of the game engine.
The authors evaluate six frontier LLMs in two settings. In the first, GTAVBench gives the model textual task instructions. In the second, the GTAVBench-AGI branch, instructions appear only in the first screenshot, and a harness automatically compresses the interaction history. The best configuration reaches 70.9% overall accuracy on GTAVBench-AGI. Aerial navigation, evasion and interception remain difficult for the evaluated models.
GTAGym also includes a scalable generator for RL. It samples task parameters within user-specified ranges and option sets under fixed templates, producing batches of 3D and image-based shooting environments with automatic reward and termination signals. As a demonstration, the authors trained Qwen3.8-27B with LoRA RL on generated on-foot navigation tasks. This improves in-domain performance and transfers to out-of-domain task categories, and to native GTA V tasks, where the result goes from 15% to 23%.
Key facts
- GTAGym is an environment and framework for evaluating agents and running RL on GTA V tasks, with automatic checks of outcomes through engine state instead of human annotation.
- GTAVBench, derived from GTA V main-story missions, has 103 online tasks across nine task families, plus 47 image-based shooting and sniping tasks.
- Six frontier LLMs were tested; the best configuration reached 70.9% overall accuracy on GTAVBench-AGI, where instructions appear only in the first screenshot.
- Aerial navigation, evasion and interception remain difficult for the evaluated models.
- LoRA RL of Qwen3.8-27B on generated on-foot navigation tasks transfers to native GTA V tasks, moving the result from 15% to 23%.
Why it matters
Checking whether an agent finished a task in a big commercial game is hard to automate, which is why such evaluation has often relied on human annotation and has been hard to use for RL. GTAGym addresses this by checking outcomes against the game engine's state and by supplying automatic reward and termination signals for generated tasks. That puts evaluation and RL training for an AAA game in one framework.
Who it affects
Researchers building and testing agents that must perceive a screen and act through keyboard and mouse are the direct audience, as are teams that want to train such agents with reinforcement learning. The benchmark also gives people comparing frontier LLMs a set of game-based tasks, including a variant where instructions are shown only in the first screenshot.
How to use it
The paper describes a web server that exposes the online environment and an evaluation interface, so agents can be tested in parallel by sending screenshots and keyboard-mouse actions. For training, a generator samples task parameters within ranges and option sets you specify, under fixed templates, and builds batches of 3D and image-based shooting environments with automatic rewards. The authors' own example is LoRA RL on generated on-foot navigation tasks. The source gives no release, code, dataset or licence details.
How solid is it
This is a paper abstract, and the results are the authors' own. The numbers are specific: 103 online tasks in nine families, 47 image-based tasks, six LLMs, 70.9% for the best configuration on GTAVBench-AGI, and 15% to 23% on native GTA V tasks after RL. The source does not name the six models, does not say which configuration scored 70.9%, and does not give per-model or per-family results.
Risks and caveats
The 70.9% is the best result, not an average across models. The source does not name the metric behind the 15% to 23% improvement, or say whether it is absolute points or relative, and it does not state the baseline explicitly. No human-performance baseline is given. The source does not mention the game's publisher or any permission from it. The authors themselves note that aerial navigation, evasion and interception remain difficult, so the high headline score does not cover every task type.