Infrathon benchmark tests whether AI agents can keep improving infrastructure over 24-hour runs
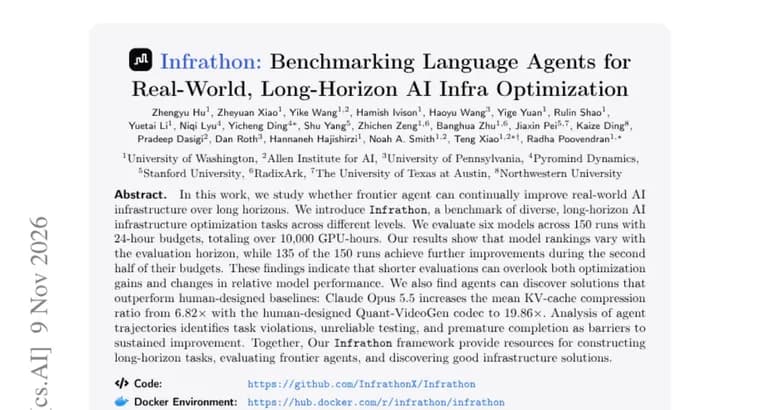
A paper on Hugging Face Papers asks whether frontier agents can continually improve real-world AI infrastructure over long horizons. To find out, it introduces Infrathon, a benchmark of diverse, long-horizon AI infrastructure optimization tasks across different levels.
The evaluation is large. Six models were run 150 times in total, each run with a 24-hour budget, adding up to over 10,000 GPU-hours.
The first finding is that model rankings vary with the evaluation horizon. In other words, the order of the models depends on how long the agent is given to work. The second is that 135 of the 150 runs, or 90%, achieved further improvements during the second half of their budgets. From this the authors conclude that shorter evaluations can overlook both optimization gains and changes in relative model performance.
The headline example involves KV-cache compression. The authors report that Claude Opus 5.5 raised the mean KV-cache compression ratio from 6.82% with the human-designed Quant-VideoGen codec to 19.86%, roughly 2.9 times the baseline figure. They take this as evidence that agents can discover solutions that outperform human-designed baselines.
The paper also looks at why agents stall. Analysis of agent trajectories identifies task violations, unreliable testing and premature completion as barriers to sustained improvement. The authors present the Infrathon framework as a set of resources for constructing long-horizon tasks, evaluating frontier agents and discovering good infrastructure solutions.
Key facts
- Infrathon is a benchmark of diverse, long-horizon AI infrastructure optimization tasks across different levels.
- Six models were evaluated across 150 runs with 24-hour budgets, totaling over 10,000 GPU-hours.
- Model rankings vary with the evaluation horizon, and 135 of the 150 runs kept improving during the second half of their budgets.
- Claude Opus 5.5 raised the mean KV-cache compression ratio from 6.82% (human-designed Quant-VideoGen codec) to 19.86%.
- Task violations, unreliable testing and premature completion are named as barriers to sustained improvement.
Why it matters
Most agent evaluations are short. This work argues that a short test can miss two things: gains an agent keeps making late in a run, and changes in which model comes out ahead. In the authors' runs, 135 of 150 were still improving in the second half of their 24-hour budgets, and the model rankings moved with the horizon. The KV-cache result adds a concrete case of an agent beating a human-designed baseline on a real infrastructure task.
Who it affects
Teams that build or compare coding and optimization agents are the most direct audience, since the findings bear on how long an evaluation should run before a model is judged. Engineers who work on AI infrastructure, such as KV-cache compression, are the other group: the paper studies agents working on exactly that kind of task.
How to use it
The authors describe the Infrathon framework as providing resources for constructing long-horizon tasks, evaluating frontier agents and discovering good infrastructure solutions. No publication date, code or dataset release, or availability of the benchmark is stated. The practical lesson from the abstract is to give agents longer budgets when comparing them, and to watch for the failure modes it lists: task violations, unreliable testing and premature completion.
How solid is it
This is a preprint, summarized here from its abstract. The scale is substantial: 150 runs, 24-hour budgets and over 10,000 GPU-hours. The abstract names no authors or institutions. It does not list which six models were evaluated, other than Claude Opus 5.5 in the KV-cache example, and it does not give the final model ranking. It also does not say whether the Claude Opus 5.5 result comes from a single run or is averaged over several runs, or on which task level.
Risks and caveats
The KV-cache figures are given as a mean compression ratio in percent, and the abstract does not define the metric. It gives no size for the improvements in the 135 runs, only that further improvements occurred. The conclusions are the authors' own reading of their results. The trajectory analysis points to task violations, unreliable testing and premature completion as barriers, so long runs do not improve automatically.
“shorter evaluations can overlook both optimization gains and changes in relative model performance”
— Infrathon paper abstract