LeWM JEPA world model: 600 experiments lift long-horizon success from 22% to 85%
The post opens with a debate over what a world model should be. Generative world models predict the future by generating it, usually in pixels. Many scientists, including Yann LeCun, argue that this is wasted effort, because most pixels do not matter for deciding what to do and many cannot be predicted at all. The proposed alternative is JEPA, the joint-embedding predictive architecture, which has three parts. An encoder turns each frame into a learned embedding, a compact vector describing the scene. A predictor takes that embedding plus an action and predicts the embedding of the next frame. A planner tries hundreds of action sequences inside the predictor and picks the one whose predicted end state lands closest to the goal embedding. The whole loop runs in embedding space.
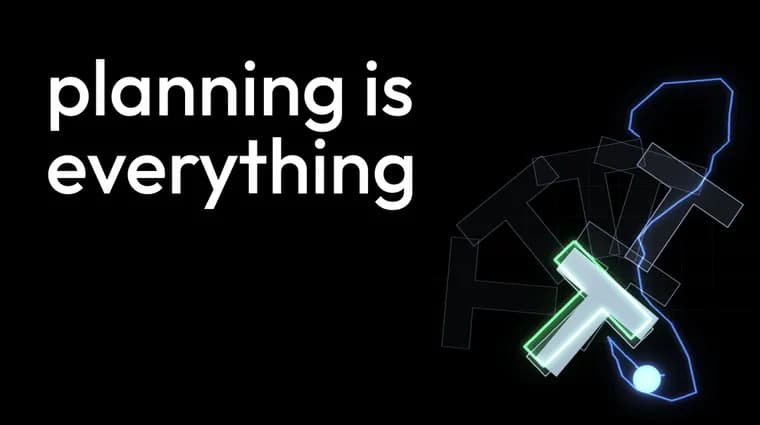
This year a team including LeCun released LeWM, a JEPA world model whose main benchmark is Push-T, a simulation where a robot pushes a gray T-shaped block across a table until it sits in the green target position shown in a goal image. The author says they spent the last few months running 600 experiments on it.
First test: how much are LeWM's predictions holding it back? The author swapped the predictor for the simulator's perfect physics, changing nothing else, and gave both versions long-horizon tasks with the goal 75 steps away, plus the same subgoals: frames from an expert demonstration, one every 25 steps. Vanilla LeWM succeeded 78% of the time; the true-physics version, 77%. The author concludes that along the kinds of paths it was trained on, LeWM's predictions are already as good as perfect physics for planning, so further gains must come from how the trained model is used.
Without retraining the model once, the author says they found four new planning methods. The first two together took LeWM's long-horizon success rate from 22% to 85%, about the same as a planner handed ideal expert subgoals. The other two extend LeWM to harder goals; one of them, a single change to how the goal is scored, raised success by 60 points, three times as much as perfect physics did. The visible text describes only the first two methods.
Method 1 is to plan through subgoals 25 steps apart. Used exactly as published, LeWM succeeds on 22% of long-horizon tasks (goal 75 steps away). With the goal 25 steps away it succeeds 89.7% of the time, within a point of the exact-physics version at 90.5%. So the model is accurate over 25 steps and struggles over 75. The usual explanation is that small prediction errors compound over a long plan, which would call for a better model. The author tested that on the same 250 long-horizon tasks: exact physics added 20 points, while splitting the task into 25-step segments added nearly 60. LeWM's useful planning horizon is about 25 steps, so the way to go further is to chain segments of that length. This is hierarchical planning, where a high level picks subgoals and a low level reaches them. The author calls it widely considered one of the main open problems for world models, and says that on Push-T it is worth three times as much as perfect physics. Extra search does not substitute: running the planner four times and keeping the lowest-cost plan took four times the compute and added less than one point, because the four runs almost always succeeded or failed together.
The catch is that these subgoals came from an expert demonstration, which a deployed robot will not have. Method 2 removes that dependence with a latent memory graph. LeWM was trained on expert demonstrations, and its encoder can embed every frame of them, giving about 460,000 embedded states, which the author connected into a graph. Each state links to the states that follow it in its own demonstration and to close states, in embedding space, from other demonstrations. To solve a long-horizon task, the planner searches the graph for a path from the current state to the goal and uses the states along that path as subgoals.
This works only if embedding distance means something physical. The author checked: given one subgoal reachable within 25 steps and one that is not, LeWM's embedding distance ranks the reachable one as closer 87% of the time. So the embedding space doubles as a map of what the robot can reach.
The first version of the graph had a flaw. A jump between nearby states in two different demonstrations cost the same as a real step, so the search strung jumps together into paths the block could never follow; 318 of 1,015 plans tried to use six or more jumps. The fix was a cost on every jump between demonstrations. Using nothing but LeWM's own embeddings of past demonstrations, success on the same 250 long-horizon tasks went from 62% to 85%, the same score as the planner using expert subgoals. The visible text ends there, on the author's question, "Can't get much better than that, right?"
Key facts
- The author ran 600 experiments on LeWM, a JEPA world model released this year by a team including Yann LeCun, whose main benchmark is Push-T.
- Replacing LeWM's predictor with the simulator's exact physics changed little when both got expert subgoals every 25 steps: 78% for vanilla LeWM versus 77% for true physics.
- Used as published, LeWM succeeds on 22% of long-horizon tasks (goal 75 steps away); with the goal 25 steps away it reaches 89.7%, against 90.5% for exact physics.
- Two of the four planning methods, subgoals 25 steps apart and a latent memory graph with a cost on every jump, together took long-horizon success from 22% to 85% without retraining.
- On 250 long-horizon tasks, exact physics added 20 points and 25-step segmenting added nearly 60; adding a jump cost to the graph moved success from 62% to 85%.
Why it matters
JEPA world models are pitched as an alternative to generative ones that predict pixels, an approach LeCun and others call wasted effort. This post puts numbers on one JEPA model, LeWM. The author finds its predictions already match perfect physics for planning along trained paths, so the bottleneck is how the model is used. Hierarchical planning is described as widely considered one of the main open problems for world models, and the author reports that on Push-T it is worth three times as much as perfect physics.
Who it affects
Researchers and engineers working on world models and robot planning, especially anyone using or evaluating LeWM or comparing JEPA with generative world models. The graph method matters for deployment in particular, because the author notes a deployed robot will not have expert subgoals.
How to use it
The post describes methods rather than a product. Plan through subgoals 25 steps apart, since LeWM's useful horizon is about 25 steps. To get subgoals without an expert, embed every frame of the training demonstrations (about 460,000 states), link each state to its successors and to nearby states from other demonstrations, search that graph for a path to the goal, and charge a cost on every jump between demonstrations. None of this requires retraining the model. The author reports that extra search does not help: four planner runs cost four times the compute for less than one point.
How solid is it
The numbers are the author's own, from experiments on one benchmark, Push-T. The visible text mentions no code, paper link or peer review; the references [1], [2], [3] appear only as markers. The 22% to 85% result concerns Push-T only, and nothing is said about other benchmarks or real robots. The 78% versus 77% comparison uses expert subgoals every 25 steps, so it is a different setting from the 22% baseline, which has no subgoals. The visible text is cut off after method 2, so the other two methods, including the 60-point goal-scoring change, are not described.
Risks and caveats
The headline gains come from a simulated pushing task, and the source gives no evidence on how they carry over to other tasks or physical robots. The author's claim that LeWM's predictions equal perfect physics is limited to the kinds of paths it was trained on. The graph is built from expert demonstrations the model was trained on, so the method relies on that data. LeCun is not said to have taken part in or endorsed these experiments; he is named only as a critic of pixel-generating world models and as part of the team that released LeWM.
“So the embedding space doubles as a map of what the robot can reach.”
— From the post on haddyalchaer.com