Linum releases experimental P-JiT text-to-image model, $21K run
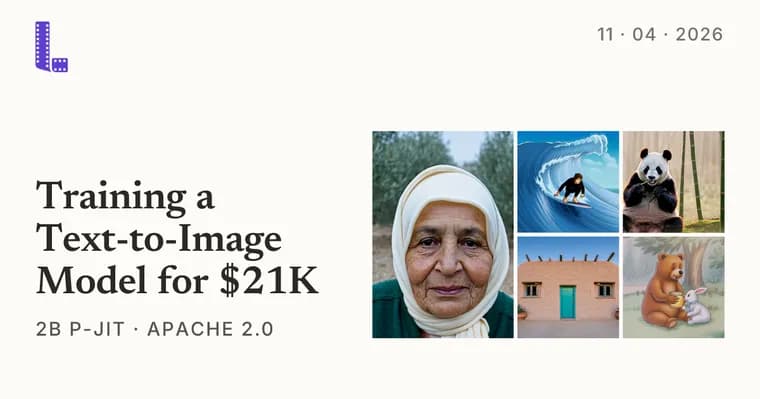
Linum, which describes itself as a 2-person research lab training generative video models entirely from scratch, has published an experimental text-to-image model called Pyramid-JiT (P-JiT). The Show HN title lists the weights as Apache 2.0 and puts the cost at about $20K; the post itself says the training run cost $21K. The lab calls the run a proof-of-concept on the way to its next video model. It says it was surprised by how good the results looked for the model's size, so it decided to share the model as an experimental release.
The motivation comes from video. Linum says video models today are too slow, too expensive and lack proper controls, which makes them poor tools for storytelling. When it set out to build Linum v3 earlier this year, the main goal was to cut the cost of inference. Its reasoning: attention is O(n²), so compressing the input more aggressively shrinks the context window and cuts the cost of both training and inference. Compression is usually handled by a separate model such as a Variational Autoencoder, but the authors say VAEs seem to hit an empirical ceiling on compression, and a VAE that reconstructs better can produce worse generations downstream. So they drop the VAE and let the diffusion model learn a latent space built for its own use.
The result of their earlier work is P-JiT, a pixel-space model that converges in 11× fewer samples than Linum v2 with 4× more aggressive token reduction: a 512² image uses the same number of tokens that a 256² image used before. Two ideas drive it. First, a noise schedule for pixel-space models that helps them learn fine-grained detail. Second, readouts along the trunk of the DiT. The authors point to adjacent work (REPA, RAE-v2, Self-Flow) showing weak gradients in the early blocks of a DiT. Because every block in a pixel-space model is effectively predicting a version of the final image, low-resolution predictions can add gradient signal earlier in the network and speed up convergence.
This release is a pressure test: train the architecture for about 600M samples instead of the 50 to 100M of the initial experiments.
Architecture and training. Text and image each pass through two single-modality refiner DiT blocks, then merge into one stream of 22 identical DiT blocks. Text comes from a frozen Qwen3.5-4B model, read at layers 7, 15 and 27 (its three full-attention layers). The image is split into 32×32 patches and compressed into a 1024-dimensional space. At block 5 sits a 2-layer PixelREPA readout that aligns the latent space to DINOv3-L. Two linear readout heads after blocks 10 and 16 predict the clean image at a quarter and half resolution. The total loss combines MSE at the readouts, PixelREPA cosine distance, MSE at the final output head, and perceptual losses (LPIPS and P-DINO) on the full-resolution image. Each block is conditioned on the timestep through a low-rank AdaLN following Z-Image: a single down-projection to 256 dimensions, then a per-block up-projection to a scale and a gate, zero-initialized so every block starts as the identity.
The noise schedule follows a curriculum: concentrated at high noise for the first 80M samples so the model learns basic structure, then widened for the rest of training to learn fine detail. EMA starts at 100M samples. For the move to 1024², the team starts a fresh optimizer from the 512² EMA weights, doubles the noise scale from 2 to 4 to account for the redundancy of information, uses RoPE interpolation for the resolution transition, and starts the 1024² EMA 2M samples in. The authors note that the higher noise level and the need to reproduce fine detail at high resolution give a higher overall loss even as image quality improves rapidly.
Post-training used a variant of Finite Difference Flow Optimization (FDFO) with JEV-Image and human-in-the-loop judges. The authors say post-training for diffusion is a very young discipline. DPO tends to overfit to specific aesthetic choices, Flow-GRPO only came out last fall, and they consider this June's FDFO the best articulation of diffusion post-training so far, in their opinion. They put the difficulty down to the lack of strong likelihood estimates in diffusion models, unlike auto-regressive LLMs, and promise a fuller write-up of their post-training stack in the coming weeks.
Limitations. The model was not trained on images of rendered text (infographics, PDFs, book pages, slides), so it cannot write text or generate posters; that data was filtered out because the authors do not see it as useful for their goal of animation tools. It is a small model, and it struggles with full-body figures, many entities (for example 6 cars or crowds), multi-person interactions and world knowledge, though it can occasionally get these right. The post shows a failure example of deformed legs on starting blocks. The authors say a larger model (for example 7B parameters) and further post-training would likely mitigate these issues.
Authorship note. The authors say they wrote all the words on the page and used Claude Opus 5.5 to help build the image gallery and diagrams. The Huggingface model card and Github repo were written automatically by Claude Opus 5.5, which was pointed at the internal experiment repo to extract and clean up the necessary code.
Key facts
- Linum, a 2-person lab, released Pyramid-JiT (P-JiT), an experimental text-to-image model with a 2B-parameter DiT and a 4B text encoder (frozen Qwen3.5-4B), from a $21K training run.
- P-JiT works in pixel space with no VAE; Linum says it converges in 11× fewer samples than Linum v2 with 4× more aggressive token reduction, so a 512² image costs the tokens a 256² image used to.
- The run lasted about 600M samples, against 50 to 100M in the initial experiments, with a noise-schedule curriculum, readouts along the trunk and a move from 512² to 1024².
- Post-training used a variant of Finite Difference Flow Optimization (FDFO) with JEV-Image and human-in-the-loop judges.
- The model cannot write text or make posters, and struggles with full bodies, crowds, multi-person interactions and world knowledge; the authors say a larger model, for example 7B, would likely help.
Why it matters
The release shows what a very small team can train from scratch on a modest budget: a $21K run, a 2B-parameter DiT, and no VAE. Linum's bet is that dropping the separate compression model lets the diffusion model learn its own latent space and compress harder, which matters most for video, where attention cost grows with the square of the context length. The 4× more aggressive token reduction (a 512² image in the tokens that used to cover 256²) is that bet in practice. The authors present the model as a proof-of-concept on the way to their next video model, not as a finished product.
Who it affects
Researchers and engineers working on diffusion architectures, pixel-space generation and diffusion post-training are the main audience, since the post details the readouts, the noise-schedule curriculum and the FDFO-based post-training. Small labs weighing the cost of training an image or video model from scratch also get a concrete data point. Linum's stated long-term target is creative tools for animation.
How to use it
Linum says it released the model as an experimental release, with a Huggingface model card and a Github repo; the Show HN title lists the weights as Apache 2.0. The post describes the stack in enough detail to follow the recipe: a frozen Qwen3.5-4B text model read at layers 7, 15 and 27, 22 merged DiT blocks, PixelREPA alignment to DINOv3-L, and a 512² to 1024² schedule. Since the model was not trained on rendered text, it is not suited to posters, infographics or anything that needs legible lettering.
How solid is it
This is a first-party write-up by the lab that trained the model, and the claims are self-reported. The post shows an image gallery with prompts and candid failure examples, but it gives no quantitative image-quality benchmark scores (FID, GenEval and the like) and no comparisons with other text-to-image models. The 11× and 4× figures are relative to Linum's own earlier Linum v2 model. No hardware or training time is given. The authors call FDFO the best articulation of diffusion post-training in their own opinion.
Risks and caveats
The authors state the limits plainly: no text rendering, and weak results on full-body figures, many entities such as 6 cars or crowds, multi-person interactions and world knowledge, with correct outputs only on occasion. They expect a larger model and more post-training would likely mitigate these issues, which is an expectation and not a result. The model card and code repo were written automatically by Claude Opus 5.5 from an internal experiment repo. The license appears only in the Show HN title, not in the post text, and the cost is given as about $20K in the title and $21K in the post.
“this $21K training run is a proof-of-concept along the way to our next video model”
— Linum, in its field notes post