MJev-Spatial answers spatial questions by classification, not text generation
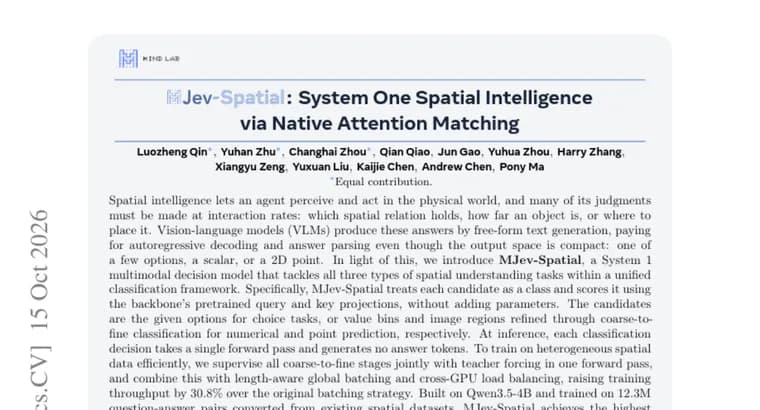
Spatial intelligence, the paper says, lets an agent perceive and act in the physical world, and many of its judgments have to be made at interaction rates: which spatial relation holds, how far an object is, or where to place it. The authors argue that vision-language models (VLMs) handle these questions by free-form text generation. That means paying for autoregressive decoding and answer parsing even though the output space is compact: one of a few options, a scalar, or a 2D point.
Their response is MJev-Spatial, which they call a System 1 multimodal decision model. It covers all three task types (choice, numerical and point prediction) in one classification framework. Each candidate is treated as a class and scored with the backbone's pretrained query and key projections, without adding parameters. For choice tasks the candidates are the given options. For numerical tasks they are value bins, and for point prediction they are image regions, in both cases refined through coarse-to-fine classification. At inference, each classification decision takes a single forward pass and generates no answer tokens.
Training on mixed spatial data is handled with a joint scheme: all coarse-to-fine stages are supervised together with teacher forcing in one forward pass. Combined with length-aware global batching and cross-GPU load balancing, this raises training throughput by 30.8% over the original batching strategy.
The model is built on Qwen3.5-4B and trained on 12.3M question-answer pairs converted from existing spatial datasets. The reported results: the highest overall score (65.64%) among eight tested models, first place on seven of twelve benchmarks, and better results than its unmodified autoregressive base model on all twelve. It runs 2.5 times faster than the fastest autoregressive baseline and 5.6 times faster than the base model.
Key facts
- MJev-Spatial recasts spatial choice, numerical and point-prediction tasks as classification, scoring candidates with the backbone's pretrained query and key projections and adding no parameters.
- Each decision takes a single forward pass and produces no answer tokens; numerical and point answers are refined coarse-to-fine over value bins and image regions.
- Built on Qwen3.5-4B and trained on 12.3M question-answer pairs converted from existing spatial datasets; joint teacher-forced training with length-aware batching raised training throughput by 30.8%.
- Reported results: 65.64% overall, the highest of eight tested models; first on seven of twelve benchmarks; better than its autoregressive base model on all twelve.
- Speed: 2.5 times faster than the fastest autoregressive baseline and 5.6 times faster than the base model.
Why it matters
Many spatial judgments, such as a relation between objects, a distance or a placement point, have a small, well-defined answer space, yet VLMs generate them as free text and then parse it. The paper's argument is that this costs time that interaction-rate use cannot spare. MJev-Spatial swaps generation for classification over the backbone's own query and key projections, so a decision takes one forward pass. The reported payoff is a model 2.5 times faster than the fastest autoregressive baseline and 5.6 times faster than its own base model, with a higher overall score than the other seven models tested.
Who it affects
The framing is aimed at systems that need spatial answers at interaction rates, since the paper describes spatial intelligence as letting an agent perceive and act in the physical world. That points to researchers working on spatial reasoning in VLMs and on fast, compact-output decision models. The paper names no lab or institution in its abstract.
How to use it
There is nothing to run yet from the material at hand: no statement about code or model release, licence, or availability. The idea itself is portable in outline. Treat candidate answers as classes, score them with the backbone's existing query and key projections, and for numbers and points refine the answer coarse-to-fine over value bins or image regions. Training supervises all coarse-to-fine stages jointly with teacher forcing in one forward pass.
How solid is it
This is a preprint reporting the authors' own results, and the source is an abstract. The eight tested models, the twelve benchmarks and the autoregressive baselines are not named, so the comparisons cannot be checked from this text. The 65.64% is described only as an overall score; the metric and its aggregation are not specified, and the score of the base model or other models is not stated, so the size of the margin is unknown. No absolute latency or hardware is given for the 2.5 times and 5.6 times speed figures.
Risks and caveats
The speed claims are ratios with no stated hardware or absolute latency. It is not stated whether the 30.8% training throughput gain comes from batching alone or from the joint teacher-forcing training as well. The training data was converted from existing spatial datasets into 12.3M question-answer pairs, and the abstract does not say how that conversion affects the benchmark comparisons. The approach is built for tasks with a compact answer space (options, scalars, 2D points), which is how the paper defines its scope.
“At inference, each classification decision takes a single forward pass and generates no answer tokens.”
— MJev-Spatial paper abstract