Paper finds multimodal models don't need a pretrained vision encoder
How multimodal language models should encode visual input is still debated. Most models use a pretrained vision encoder. Some recent recipes train the encoder from scratch together with the language model, and others remove it entirely.
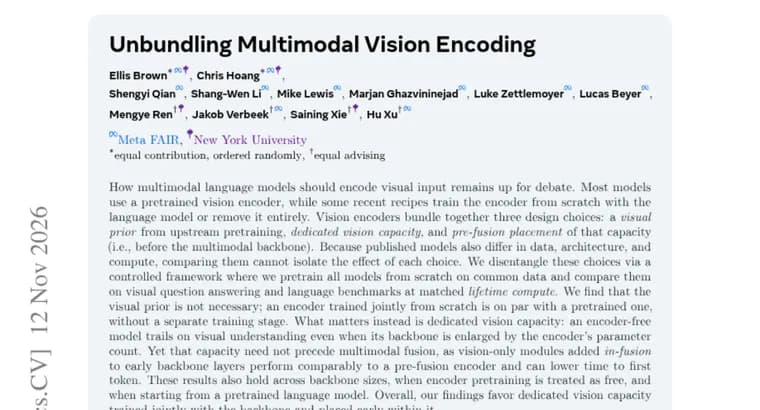
The paper, "Unbundling Multimodal Vision Encoding" (listed on Hugging Face Papers), argues that a vision encoder bundles three separate design choices: a visual prior from upstream pretraining, dedicated vision capacity, and pre-fusion placement of that capacity, meaning it sits before the multimodal backbone. Published models also differ in data, architecture and compute, so comparing them cannot isolate the effect of each choice.
To separate the three, the authors build a controlled framework. All models are pretrained from scratch on common data and compared on visual question answering and language benchmarks at matched lifetime compute.
They report three findings. First, the visual prior is not necessary: an encoder trained jointly from scratch is on par with a pretrained one, and it needs no separate training stage. Second, what matters instead is dedicated vision capacity. An encoder-free model trails on visual understanding even when its backbone is enlarged by the encoder's parameter count. Third, that capacity need not come before multimodal fusion. Vision-only modules added in-fusion to early backbone layers perform comparably to a pre-fusion encoder and can lower time to first token.
The authors say these results also hold across backbone sizes, when encoder pretraining is treated as free, and when starting from a pretrained language model. Their overall conclusion is that the findings favor dedicated vision capacity trained jointly with the backbone and placed early within it.
Key facts
- The paper splits a vision encoder into three bundled design choices: a visual prior from upstream pretraining, dedicated vision capacity, and pre-fusion placement.
- All models are pretrained from scratch on common data and compared on visual question answering and language benchmarks at matched lifetime compute.
- An encoder trained jointly from scratch is on par with a pretrained one, so the visual prior is not necessary and no separate training stage is needed.
- An encoder-free model trails on visual understanding even when its backbone is enlarged by the encoder's parameter count, so dedicated vision capacity matters.
- Vision-only modules added in-fusion to early backbone layers perform comparably to a pre-fusion encoder and can lower time to first token.
Why it matters
Designs for feeding images into language models are tangled together: a pretrained encoder brings a visual prior, extra vision parameters and a fixed position ahead of the backbone all at once. Because published models differ in data, architecture and compute, it has been hard to say which of these actually helps. This paper isolates each choice under matched conditions. Its answer is that the pretrained prior is not what carries the benefit, while dedicated vision capacity is.
Who it affects
The findings bear most directly on researchers and engineers who design or train multimodal language models and have to choose between a pretrained encoder, an encoder trained jointly from scratch, or no encoder at all. They also touch anyone who cares about time to first token in such models.
How to use it
Read it as design guidance rather than a ready-made tool. According to the authors, a team can train the vision encoder jointly with the backbone instead of adding a separate pretraining stage, keep dedicated vision capacity rather than dropping the encoder, and consider vision-only modules in early backbone layers in place of a pre-fusion encoder. No code, weights or dataset release is mentioned.
How solid is it
The setup is a strength: every model is pretrained from scratch on the same data and compared at matched lifetime compute, which removes the data, architecture and compute differences that muddy comparisons of published models. The authors also report that the results hold across backbone sizes, when encoder pretraining is treated as free, and when starting from a pretrained language model. The text available here is the abstract. No model names, parameter counts, backbone sizes, benchmark names or scores are given, and the size of the time-to-first-token reduction is not stated.
Risks and caveats
The claims are the authors' own, and the abstract gives no numbers to judge how large the gaps are. "On par" and "comparably" are qualitative, and the lower time to first token is stated as something the modules "can" do, not something they always do. The conclusion rests on models pretrained from scratch under matched compute, and the abstract does not say how far it carries to other training regimes beyond the three robustness checks it lists.
“Overall, our findings favor dedicated vision capacity trained jointly with the backbone and placed early within it.”
— Abstract of "Unbundling Multimodal Vision Encoding"