REA runtime hits 95.9% on LIBERO-Pro without policies waiting on the brain
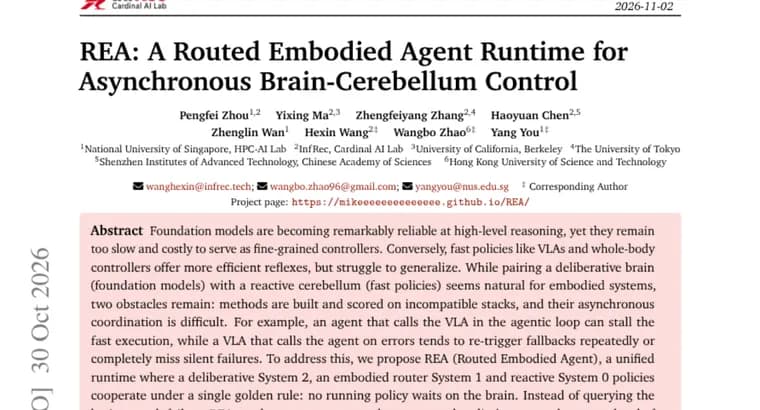
The paper starts from a split in embodied AI. Foundation models are becoming reliable at high-level reasoning, but they remain too slow and costly to act as fine-grained controllers. Fast policies such as VLAs (vision-language-action models) and whole-body controllers give more efficient reflexes, but struggle to generalize. Pairing a deliberative "brain" (foundation models) with a reactive "cerebellum" (fast policies) looks natural, yet two obstacles remain: methods are built and scored on incompatible stacks, and their asynchronous coordination is difficult.
The authors give two examples of how coordination goes wrong. An agent that calls the VLA inside the agentic loop can stall fast execution. A VLA that calls the agent on errors tends to re-trigger fallbacks repeatedly, or to miss silent failures completely.
Their answer is REA (Routed Embodied Agent), a unified runtime with three layers: a deliberative System 2, an embodied router System 1, and reactive System 0 policies. They cooperate under one golden rule: no running policy waits on the brain. Rather than querying the brain at each failure, REA uses three mechanisms. A route memory stores each policy's measured success ahead of time. A boundary-triggered judge gate consults the brain on policy execution. A shared-budget escalation ladder handles bounded recovery.
On LIBERO-Pro, evaluated on 3,000 test episodes across 60 tasks, REA reaches 95.9% success. That beats the best single-agent baseline in its own policy pool, which scores 94.7%. REA also reduces control steps by 25% and control time by 17%; the source does not say what these reductions are measured against.
In a separate 100-episode RoboTwin 2.0 study, REA achieves 84% success with VLA policies and 86% with VLA+code, compared with 80% for the strongest single VLA baseline, MEDex. The authors say this shows learned and programmatic policies operating within the same runtime. They add that REA transfers to BEHAVIOR-1K and a real Unitree G1 humanoid, achieving the highest observed success among the compared methods.
Key facts
- REA (Routed Embodied Agent) joins a deliberative System 2, an embodied router System 1 and reactive System 0 policies under one rule: no running policy waits on the brain.
- Instead of querying the brain at each failure, it uses a route memory of each policy's measured success, a boundary-triggered judge gate, and a shared-budget escalation ladder for bounded recovery.
- On LIBERO-Pro (3,000 test episodes, 60 tasks) REA reaches 95.9% success versus 94.7% for the best single-agent baseline in its own policy pool, with 25% fewer control steps and 17% less control time.
- On a separate 100-episode RoboTwin 2.0 study, REA scores 84% with VLA policies and 86% with VLA+code, against 80% for the strongest single VLA baseline, MEDex.
- The authors also report transfer to BEHAVIOR-1K and a real Unitree G1 humanoid, with the highest observed success among compared methods.
Why it matters
Robot systems want the broad reasoning of foundation models and the speed of small reactive policies, but combining them is awkward. The authors argue that today's pairings either stall fast execution while waiting on an agent, or call the agent only after errors and then loop on fallbacks or miss silent failures. REA is a proposed runtime that tries to remove that waiting by design, and it is also meant to put learned and programmatic policies on one stack.
Who it affects
Mainly researchers and engineers building embodied agents that combine a planning model with fast control policies, including VLAs and whole-body controllers. The evaluations cover simulated benchmarks (LIBERO-Pro, RoboTwin 2.0, BEHAVIOR-1K) and a real Unitree G1 humanoid.
How to use it
The source is a paper abstract describing the architecture, not a product. The practical idea it offers is the structure: keep a store of each policy's measured success ahead of time, consult the brain only at execution boundaries through a judge gate, and cap recovery with a shared budget. No code release, dataset release or latency figures in absolute units are mentioned.
How solid is it
The headline numbers are specific: 95.9% against 94.7% on 3,000 LIBERO-Pro episodes, and 84% and 86% against 80% on 100 RoboTwin 2.0 episodes. They are the authors' own reported results. The 95.9% vs 94.7% comparison gives no confidence intervals or significance test. The source does not say whether the 84% / 86% RoboTwin 2.0 figures are averages over tasks or how many tasks were used.
Risks and caveats
The 25% and 17% reductions in control steps and time have no stated baseline. No success numbers are given for BEHAVIOR-1K or the Unitree G1 humanoid, nor the number of real-robot trials, so the transfer claim cannot be checked from the source. The source also does not say which foundation model serves as the brain. The LIBERO-Pro gain over the best single-agent baseline in REA's own pool is 1.2 percentage points.
“no running policy waits on the brain”
— From the paper's abstract, describing REA's single golden rule