SolarRenderer turns game-engine structure into video in four steps
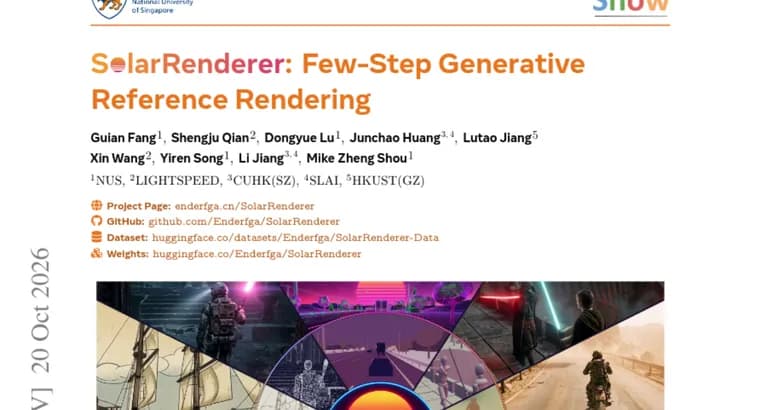
A paper on Hugging Face Papers introduces SolarRenderer, a structure-conditioned video renderer. The starting problem: game engines and coding agents can specify the layout, motion and camera of a scene, but turning that coarse structure into realistic video needs a renderer that follows the structure and fills in the appearance it leaves open. The authors say existing renderers are tied to the representation of one engine, need tens of denoising steps or a costly distillation of their own, and learn from conditions that are not aligned with their target videos.
SolarRenderer adapts a frozen MiniMax-H3 33B backbone with two lightweight LoRAs. Structural videos enter the backbone's native reference pathway at the positions of the frames they describe. They carry no type identifier and are described only in plain text, so a single control LoRA can follow arbitrary structural representations.
For speed, the method starts from a pretrained four-step LoRA and applies structure-guided distribution matching. The result renders in four steps, which the paper puts at 12.3 times faster than 50-step sampling, while preserving the learned control. A block-causal variant extends the same design to streaming and renders 768p video in real time.
To train the model, the authors built a frame-aligned corpus of 136K clips drawn from game engines, simulators and YouTube videos. They evaluated on an in-distribution test set and on a generalization benchmark of 16 structural representations. They report that SolarRenderer achieves state-of-the-art results across both, and that it generalizes to 11 unseen representations, including pose skeletons, drawings and point clouds.
Key facts
- SolarRenderer adapts a frozen MiniMax-H3 33B backbone with two lightweight LoRAs; a single control LoRA is meant to follow arbitrary structural representations.
- Structure-guided distribution matching, starting from a pretrained four-step LoRA, renders in four steps, 12.3 times faster than 50-step sampling.
- A block-causal streaming variant renders 768p video in real time.
- Training uses a frame-aligned corpus of 136K clips from game engines, simulators and YouTube videos.
- The authors report state-of-the-art results on an in-distribution test set and a 16-representation generalization benchmark, and generalization to 11 unseen representations, including pose skeletons, drawings and point clouds.
Why it matters
Game engines and coding agents can describe what a scene should contain, but not how it should look. A renderer that turns such coarse structure into realistic video is the missing step, and the paper's authors argue that current options are tied to one engine's representation, slow because they need tens of denoising steps or their own costly distillation, and trained on conditions not aligned with the target videos. SolarRenderer targets all three at once: one control LoRA for many structure types, four-step rendering, and a frame-aligned training corpus.
Who it affects
The work is aimed at people who produce structured scene descriptions and want realistic video from them: users of game engines and simulators, and developers of coding agents that specify layout, motion and camera. Teams working on streaming or real-time video generation are also in scope, given the block-causal variant that renders 768p video in real time.
How to use it
The abstract describes a method rather than a product. In practice it means feeding structural videos, such as those from a game engine, into the backbone's native reference pathway with a plain-text description and no type identifier, using the control LoRA on the frozen MiniMax-H3 33B backbone. The abstract does not say whether weights, code or data are released.
How solid is it
This is a preprint abstract, and the headline results are the authors' own claims. The state-of-the-art claim covers an in-distribution test set and a 16-representation generalization benchmark, but no benchmark scores, metric names or baselines are given. The abstract does not say whether the 12.3x figure refers to latency or throughput, or on what hardware. The hardware and frame rate behind real-time 768p rendering are not stated either.
Risks and caveats
The 12.3x speedup is measured against 50-step sampling, so it describes the gain over that setting, not over other fast renderers. The abstract does not give the share of the 136K clips coming from each source (game engines, simulators, YouTube). Generalization to 11 unseen representations is reported by the authors; the abstract names only pose skeletons, drawings and point clouds as examples. The abstract names no authors or institutions.