SWE-Game benchmark: coding agents score under 60/100 on building Godot games
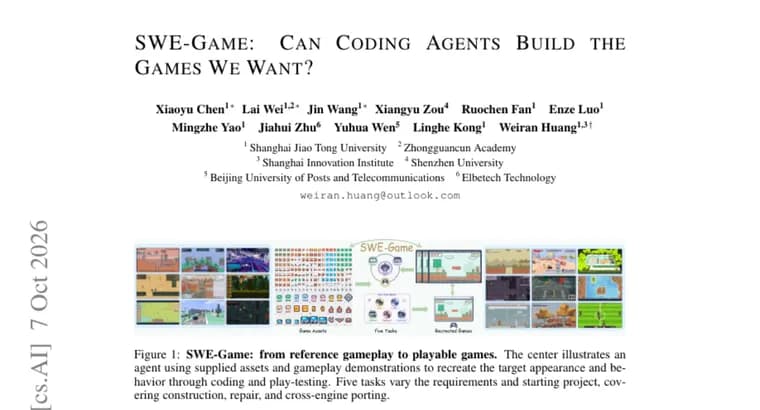
SWE-Game is a benchmark that tests how well coding agents work on whole games rather than isolated code snippets. It contains 247 tasks grounded in 41 executable reference games built in the Godot engine. The games span 13 gameplay categories, in both 2D and 3D.
There are five task types: development from a brief, implementation from a game design document, skeleton completion, repair of 83 injected-fault cases, and porting from Godot to Unity. Reference materials specify the intended gameplay. A shared instrumentation interface lets evaluator-owned drivers and probes execute actions in, and observe, games that the agents implemented independently.
Scoring combines three kinds of evidence: engine-state checks, certified reference-input replay, and agent-authored feature demonstrations. Together they assess mechanic correctness, demonstrated playability, and, after repairs, behavioral restoration and preservation. Presentation is judged separately, using game-specific vision-language rubrics.
Across six models, Opus5 achieves the highest overall score in all five task types. Even so, the best overall scores remain below 60 out of 100 across the three construction tasks, with Brief-to-Game reaching 50.38. An analysis of reviewed submissions identifies requirement omissions and gameplay logic errors as the predominant implementation problems.
The paper also checks the evaluation itself. On human-labeled behaviors from 100 agent-built games, the executable checks reach 92.59% balanced accuracy, against 78.41% for a video-based VLM judge. Rubric-based visual scores reach a Spearman correlation of 0.829 with human ratings of 200 gameplay clips. The authors conclude that the results characterize current agent capabilities across game-development activities and support combining runtime evidence with visual assessment.
Key facts
- SWE-Game has 247 tasks built on 41 executable reference Godot games across 13 gameplay categories, in 2D and 3D.
- Five task types: development from a brief, implementation from a game design document, skeleton completion, repair of 83 injected-fault cases, and Godot-to-Unity porting.
- Across six models, Opus5 has the highest overall score in all five task types, but best overall scores stay below 60 out of 100 on the three construction tasks; Brief-to-Game reaches 50.38.
- Requirement omissions and gameplay logic errors are the predominant implementation problems in reviewed submissions.
- Executable checks reach 92.59% balanced accuracy on human-labeled behaviors from 100 agent-built games, versus 78.41% for a video-based VLM judge.
Why it matters
Most coding benchmarks test small, self-contained fixes. A game is a harder target: it has to run, respond to input, follow a design and look right. SWE-Game scores agents on that whole job, from building a game out of a brief to repairing injected faults and porting from Godot to Unity. The headline result is that even the top model leaves a lot on the table: best overall scores stay below 60 out of 100 on the three construction tasks, and Brief-to-Game reaches 50.38. The benchmark also makes a methodological point: running the game and checking its state (92.59% balanced accuracy) agrees with human labels more closely than a video-based VLM judge (78.41%).
Who it affects
Researchers and teams building or buying coding agents get a task set that measures end-to-end game construction, not only code generation. Game developers who hope to hand briefs or design documents to an agent get a rough picture of where current models fall short: omitted requirements and faulty gameplay logic. Authors of other agent benchmarks may borrow the pairing of runtime evidence with visual assessment that the paper supports.
How to use it
The abstract describes the method rather than a ready workflow. For evaluators, the design is the takeaway: reference materials define intended gameplay, evaluator-owned drivers and probes act on independently built games through a shared instrumentation interface, and presentation is scored apart with game-specific vision-language rubrics. For anyone using agents on game projects, the error analysis suggests checking a result against the original requirements list and playing through the gameplay logic. The source gives no code or dataset link.
How solid is it
The evidence is a paper abstract, so every figure is the authors' own report. The evaluation is executable and was checked against people: balanced accuracy of 92.59% on human-labeled behaviors from 100 agent-built games, and a Spearman correlation of 0.829 between rubric-based visual scores and human ratings of 200 gameplay clips. The benchmark is sizable but bounded: 247 tasks on 41 games, six models. The abstract does not list the six models other than Opus5.
Risks and caveats
Only Opus5 is named, and no scores are given for the other five models. Scores are given only for Brief-to-Game (50.38); figures for repair, porting and skeleton completion are not stated. The abstract does not say that 50.38 is Opus5's score, only that Opus5 tops every task type. The abstract also does not say which model sits behind the video-based VLM judge, so the 92.59% versus 78.41% comparison cannot be tied to a particular judge. The tasks are built on Godot games (plus porting to Unity), so results may not carry over to other engines or genres.
“Best overall scores remain below 60 out of 100 across the three construction tasks, with Brief-to-Game reaching 50.38.”
— SWE-Game paper abstract