Anthropic's Fable 5.2 tops Remote Labor Index, completing 41.3% of freelance jobs
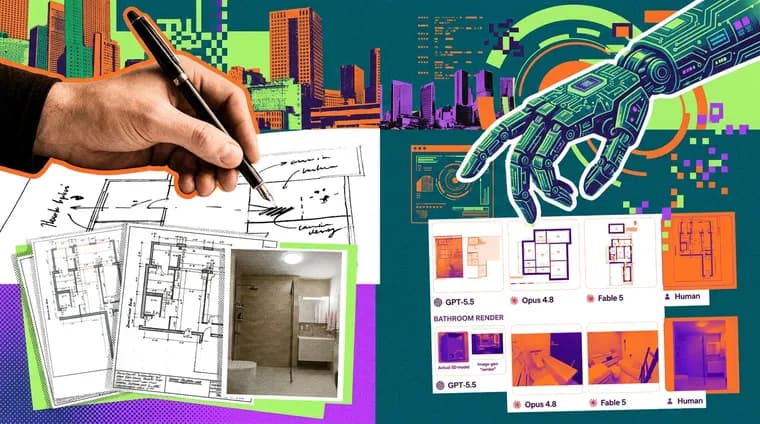
The Decoder reports that Anthropic's new model Fable 5.2 has taken the lead on the Remote Labor Index (RLI), a benchmark from Scale Labs and the Center for AI Safety (CAIS). The test measures how often AI agents complete real freelance jobs well enough for a paying client to accept the work. Fable 5.2 scores 41.3 percent.
The article frames this as a fast catch-up on practical work. When the benchmark launched about a year ago, the top system at the time, Manus, managed just 2.5 percent of tasks, so Fable 5.2 now completes more than 16 times as many professional jobs. The jump is also large against recent measurements. In July, Fable 5, an older model from the same family, led at about 16 percent, which was itself a big step: the best agents had more than quadrupled the share of jobs completed at professional quality within eight months. Four months later, Fable 5.2 reaches roughly two and a half times Fable 5's July score. Its direct predecessor, Fable 5.1, sits just under 18 percent, and Fable 5.2 completes more than twice as many jobs.
The rest of the current leaderboard is far behind. Anthropic's Opus 5.5 is next at 21.25 percent, then OpenAI's GPT 6 Astra at 20.83 percent, so Fable 5.2 works almost twice as successfully as the next-best systems on the market. Google's strongest model in the test, Gemini Argon 4, is fifth at 17.08 percent. Older models such as GPT-5.2 or Gemini 3 Pro sit below three percent.
Scale Labs said on X that Fable 5.2 makes its biggest gains in editing audio and music, designing architecture and interior spaces, and creating 3D models. The agent also handles long, complex projects that previously top-ranked models regularly failed. Nearly 50 of its successful completions were jobs no AI agent in the test had solved before. Scale Labs also says the AI can still barely handle other tasks, especially industrial product design and animations. When agents fail, they typically deliver amateur-quality work, incomplete results, broken files, or contradictory designs, according to the researchers.
The RLI differs from conventional tests that often check isolated skills; its research paper covers complete work assignments. The dataset has 240 completed projects from 358 verified professionals on Upwork, worth about $144,000 in total. A single project costs an average of $632.60 and takes a human freelancer an average of just under 29 hours. Tasks range from video editing to CAD design, game development, and data analysis. Agents work in a virtual workspace with professional software such as Blender, GIMP, or Audacity, plus specialized AI tools for image, audio, and video generation.
Grading is done by hand. Trained human experts open the submitted files in the relevant professional software and compare the AI's output directly with the work the human freelancer delivered. CAIS's attempts to automate this review with another AI have so far failed: AI reviewers can barely operate the professional software themselves, so they are fooled by submissions that look polished but are technically flawed, and they rate models far too generously.
Key facts
- Fable 5.2 leads the Remote Labor Index with 41.3 percent of real freelance jobs completed at a quality a paying client would accept.
- The top system at the benchmark's launch about a year ago, Manus, managed 2.5 percent; Fable 5.2 completes more than 16 times as many jobs.
- Next on the leaderboard are Anthropic's Opus 5.5 (21.25 percent) and OpenAI's GPT 6 Astra (20.83 percent); Google's Gemini Argon 4 is fifth at 17.08 percent.
- Fable 5.2 is roughly two and a half times Fable 5's July score of about 16 percent, and more than twice Fable 5.1's just under 18 percent.
- The dataset is 240 Upwork projects from 358 professionals, worth about $144,000, graded manually by trained human experts.
Why it matters
The RLI tests whole freelance assignments rather than isolated skills, so its numbers are closer to a measure of paid work than most benchmarks. The trend is steep: 2.5 percent for the leader a year ago, about 16 percent in July, 41.3 percent now. Fable 5.2 also solved jobs that no agent in the test had solved before (nearly 50 of its successful completions).
Who it affects
Freelancers and clients in the kinds of work the dataset covers, from video editing and CAD design to game development and data analysis, are the most direct audience. Scale Labs says the biggest gains are in audio and music editing, architecture and interior design, and 3D modelling. Competing labs are also affected: the next-best systems, Opus 5.5 and GPT 6 Astra, score about half of Fable 5.2.
How to use it
Read the result as a comparison of agents on one benchmark. The source does not say whether Fable 5.2 is publicly available or what it costs. For judging your own use case, note the strong and weak areas: audio, architecture and 3D work improved most, while industrial product design and animations are still barely handled.
How solid is it
The scores come from the RLI leaderboard of Scale Labs and CAIS, as reported by The Decoder; the strengths and weaknesses are attributed to Scale Labs, which said them on X. Anthropic makes no statement in the source. Grading is done by trained human experts who open the files in professional software and compare them with the freelancer's delivered work, which is a careful method, though the 41.3 percent is a share of only 240 projects.
Risks and caveats
Even at the top, Fable 5.2 fails on the majority of jobs: when agents fail, they typically deliver amateur-quality work, incomplete results, broken files, or contradictory designs, according to the researchers. The benchmark depends on slow manual review because AI graders are fooled by polished but flawed output and rate models too generously. The source does not give the absolute count of jobs completed, a release date for Fable 5.2, or the compute and cost of the runs.
“The test measures how often AI agents complete real freelance jobs well enough for a paying client to accept the work.”
— The Decoder