Context management pays off most as coding-agent budgets shrink, study finds
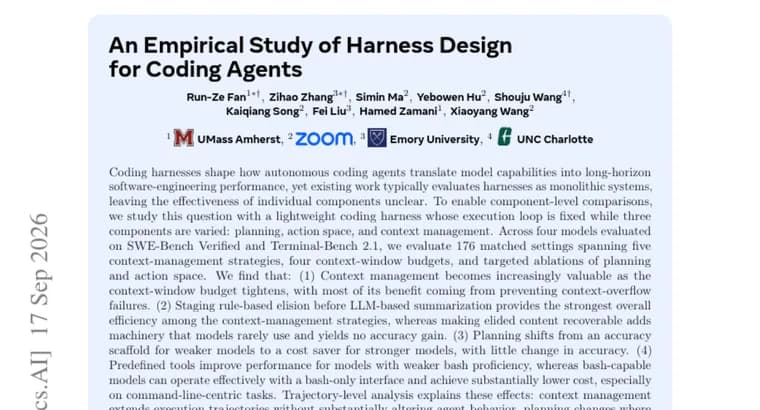
A new empirical study isolates the individual components of a coding-agent harness instead of judging harnesses as one monolithic system. Using a lightweight harness with a fixed execution loop, the researchers varied three components one at a time: context management, planning, and the action space (the set of tools the agent can call). Across four models tested on SWE-Bench Verified and Terminal-Bench 2.1, they ran 176 matched settings, covering five different context-management strategies, four context-window budgets, and targeted ablations that turned planning and the action space on and off.
The first finding is that context management becomes more valuable as the context-window budget gets smaller. Most of that value does not come from making the agent smarter within the window; it comes from stopping the agent from failing outright when it runs out of context.
Among the context-management strategies, staging rule-based elision (trimming content by fixed rules) before handing the rest to LLM-based summarization gave the strongest overall efficiency. Adding a mechanism to make elided content recoverable later added extra machinery that the models rarely used in practice, and it produced no accuracy gain.
Planning behaved differently depending on model strength. For weaker models, having a planning step acted as a scaffold that helped them get tasks right at all. For stronger models, planning barely moved accuracy but still lowered cost, so its role shifts from accuracy aid to a cost-saving step as the underlying model gets more capable.
The action space produced a similar split. Models with weaker bash proficiency did better when given predefined, structured tools. Models that were already competent with a plain bash interface performed just as well with bash alone, at substantially lower cost, and the gap was largest on tasks centered on command-line work.
A trajectory-level analysis was used to explain why these effects appear. Context management mainly extends how long an agent's trajectory runs without changing what the agent actually does at each step. Planning instead changes where a trajectory stops. The action space changes the granularity at which the agent writes code, from broad tool calls to fine-grained shell commands. The paper's own framing is that these results argue for harness design choices that are matched to both the model's strength and the available budget, rather than a single fixed harness applied everywhere.
Key facts
- 176 matched settings were evaluated across four models on SWE-Bench Verified and Terminal-Bench 2.1, spanning five context-management strategies and four context-window budgets
- Context management provides its biggest benefit as the context-window budget tightens, largely by preventing context-overflow failures rather than by improving in-window reasoning
- Staging rule-based elision before LLM-based summarization is the strongest context-management strategy for efficiency; making elided content recoverable adds machinery the models rarely use, with no accuracy gain
- Planning acts as an accuracy scaffold for weaker models but mainly cuts cost for stronger models, with little change in their accuracy
- Predefined tools help models with weaker bash proficiency, while bash-capable models match that performance with a bash-only interface at substantially lower cost, especially on command-line-centric tasks
Why it matters
Coding-agent harnesses are normally evaluated as whole systems, so it is hard to tell which piece, the context handling, the planning step, or the tool interface, is actually responsible for a given result. This study breaks the harness apart and tests each component on its own across 176 matched configurations, turning what is usually a black-box comparison into evidence about which specific design choice earns its cost under which conditions.
Who it affects
The direct audience is teams that build or tune coding-agent harnesses and researchers evaluating agent frameworks, since the study offers a modular way to test future harness components against the same four models and two benchmarks. It also matters to anyone weighing agent running costs, since several of the findings are about cost rather than accuracy.
How to use it
The practical guidance splits by model strength and budget. When the context window is tight, invest in context management, since that is where it earns most of its value. Staging rule-based elision ahead of LLM-based summarization outperformed the alternative strategies on efficiency, while a recoverability mechanism for elided content added cost without adding accuracy. For weaker models, keep a planning step and give the agent predefined tools rather than a bare bash interface. For stronger, bash-capable models, a planning step and a bash-only interface both cut cost with little accuracy trade-off, particularly on command-line-heavy tasks.
How solid is it
The study is a single empirical paper built on a fairly broad experimental grid: 176 matched settings across four models, two established benchmarks (SWE-Bench Verified and Terminal-Bench 2.1), and a trajectory-level analysis offered as an explanation for the measured effects, not just a correlation. The abstract, however, does not name the four models, the institutions involved, or give any specific accuracy or cost figures for the four findings, so the size of each effect cannot be checked or compared from the source alone.
Risks and caveats
Because the study covers four models, two benchmarks, and a specific harness design, the findings may not transfer cleanly to other models, other benchmarks, or harnesses built differently from the one used here. The abstract states conclusions in relative terms only, without publishing the underlying accuracy or cost numbers, so readers cannot independently judge how large the reported gains and savings actually are.