Factorized Vector Quantization: discrete visual tokens match continuous ones, authors say
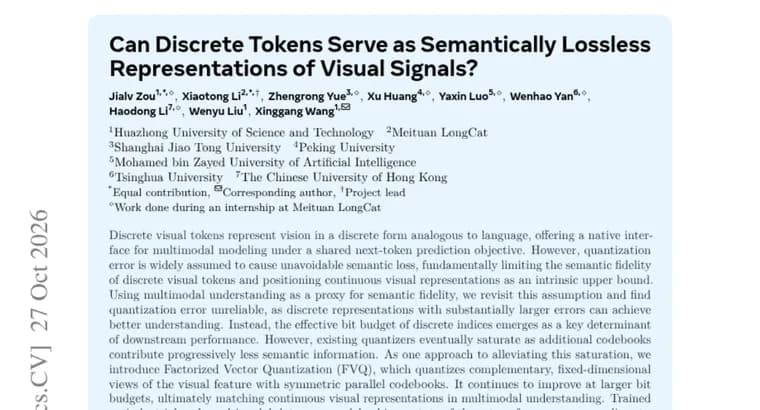
A paper listed on Hugging Face Papers takes on a common assumption in multimodal modelling. Discrete visual tokens express images in a form analogous to language, which gives a native interface for modelling text and vision under one shared next-token prediction objective. But quantization error is widely assumed to cause unavoidable semantic loss, so continuous visual representations are treated as an intrinsic upper bound on what discrete tokens can do.
The authors revisit that assumption, using multimodal understanding as a proxy for semantic fidelity. They find quantization error unreliable: discrete representations with substantially larger errors can achieve better understanding. What matters more, they say, is the effective bit budget of discrete indices, which emerges as a key determinant of downstream performance.
There is a catch. Existing quantizers eventually saturate, because each additional codebook contributes progressively less semantic information. As one approach to alleviating this, the authors introduce Factorized Vector Quantization (FVQ). It quantizes complementary, fixed-dimensional views of the visual feature with symmetric parallel codebooks. According to the authors, FVQ keeps improving at larger bit budgets and ultimately matches continuous visual representations in multimodal understanding.
The model was trained on industrial-scale multimodal data. The authors report state-of-the-art performance among discrete-representation models, outperforming UniAR and Emu3-Chat by 22.8% and 59.2% respectively on a nine-metric average. To their knowledge, it is also the first discrete-representation model competitive with strong continuous-representation models such as Qwen3-VL, including on fine-grained OCR tasks. They add that they identify the key principles and a practical recipe behind this competitiveness. Their conclusion is that the results support the potential of discrete visual representations to underpin large-scale native multimodal foundation models. Code and models are available at https://github.com/hustvl/FVQ.
Key facts
- The authors find quantization error an unreliable predictor of semantic loss: discrete representations with substantially larger errors can achieve better multimodal understanding.
- The effective bit budget of discrete indices emerges as a key determinant of downstream performance, while existing quantizers saturate as extra codebooks add less semantic information.
- Factorized Vector Quantization (FVQ) quantizes complementary, fixed-dimensional views of the visual feature with symmetric parallel codebooks, and the authors say it ultimately matches continuous representations in multimodal understanding.
- The authors' model outperforms UniAR and Emu3-Chat by 22.8% and 59.2% on a nine-metric average, and they call it the first discrete-representation model competitive with Qwen3-VL, including on fine-grained OCR.
- Code and models are published at github.com/hustvl/FVQ.
Why it matters
Discrete visual tokens fit the same next-token objective that language models use, which makes them an attractive base for native multimodal models. The standing objection is that quantization loses meaning, so continuous features are seen as the ceiling. This paper argues that the objection is badly measured: quantization error does not predict how well a model understands images, while the effective bit budget of the discrete indices does. If that holds up, the gap between discrete and continuous representations is a matter of design rather than a fixed limit.
Who it affects
Researchers building multimodal foundation models, especially those weighing discrete visual tokens against continuous features for understanding tasks. The comparison models named in the paper are UniAR and Emu3-Chat (discrete) and Qwen3-VL (continuous). The paper is about multimodal understanding, so its claims are not about image generation quality.
How to use it
Code and models are available at https://github.com/hustvl/FVQ. The authors say they also identify key principles and a practical recipe for reaching this competitiveness, so the repository and the full paper are the place to look for training details. The abstract gives no licence or pricing information.
How solid is it
These are the authors' own results, reported in an abstract. The 22.8% and 59.2% margins over UniAR and Emu3-Chat come without a statement of whether they are relative gains or percentage points, and the nine metrics are not listed. No numbers are given for the Qwen3-VL comparison; the wording is only "competitive", while "matching continuous representations" is stated for multimodal understanding. The first-of-its-kind claim is hedged by the authors with "to our knowledge".
Risks and caveats
FVQ is presented as one approach to the saturation problem, not the only one. The closing statement is about potential: the results support the possibility that discrete visual representations can underpin large-scale native multimodal foundation models, not a demonstrated outcome. The abstract gives no bit-budget values, codebook counts, model sizes or training dataset, so the scale of the effect cannot be judged from it.
“the effective bit budget of discrete indices emerges as a key determinant of downstream performance”
— Paper abstract, Hugging Face Papers