LatentGRM judges in latent space, cutting inference time 6.1 to 7.0x
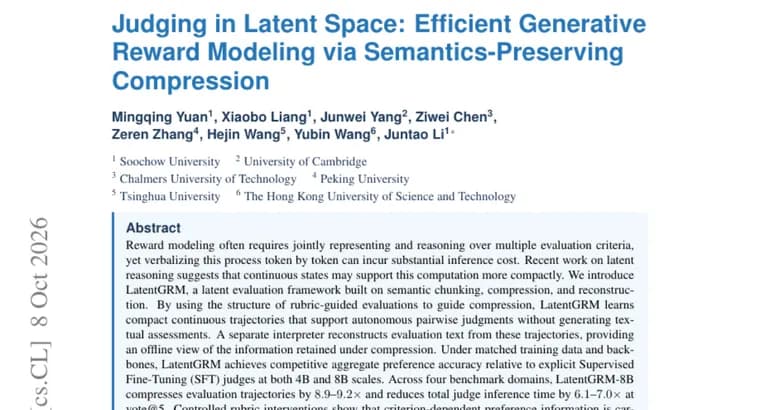
A new paper introduces LatentGRM, a latent evaluation framework for generative reward modeling. The starting problem is cost. Reward modeling often has to represent and reason over several evaluation criteria at once, and spelling that reasoning out token by token can make inference expensive. The authors point to recent work on latent reasoning, which suggests that continuous states may carry this kind of computation more compactly.
LatentGRM is built on three steps: semantic chunking, compression and reconstruction. It uses the structure of rubric-guided evaluations to steer the compression. The result is a set of compact continuous trajectories that let the judge make pairwise preference judgments on its own, without generating any textual assessment. A separate interpreter can reconstruct evaluation text from those trajectories, which gives an offline view of what information survives the compression.
On accuracy, the paper reports that under matched training data and backbones, LatentGRM reaches competitive aggregate preference accuracy relative to explicit Supervised Fine-Tuning (SFT) judges, at both 4B and 8B scales. The wording is "competitive", not better, and no absolute accuracy figures are given.
On cost, the figures are for LatentGRM-8B across four benchmark domains. It compresses evaluation trajectories by 8.9 to 9.2x and reduces total judge inference time by 6.1 to 7.0x at vote@5. Both are ranges across the four domains, not single numbers.
The authors also run controlled rubric interventions, which they say show that criterion-dependent preference information is carried through the latent sequence. Their overall conclusion is that continuous latent evaluation can substantially reduce inference cost while preserving competitive judgment quality.
Key facts
- LatentGRM is a latent evaluation framework that compresses rubric-guided evaluation reasoning into compact continuous trajectories, so the judge makes pairwise preference calls without writing out a textual assessment.
- Under matched training data and backbones, it reaches competitive aggregate preference accuracy relative to explicit SFT judges at both 4B and 8B scales.
- LatentGRM-8B compresses evaluation trajectories by 8.9 to 9.2x across four benchmark domains.
- LatentGRM-8B reduces total judge inference time by 6.1 to 7.0x at vote@5.
- A separate interpreter reconstructs evaluation text from the trajectories, giving an offline view of what the compression retains.
Why it matters
Generative reward models and LLM judges usually write out their reasoning before giving a verdict, and that text is a large part of the inference bill. LatentGRM tries to move the multi-criteria reasoning into continuous states and drop the written assessment. If the reported results hold, the judge step becomes several times cheaper at 8B and vote@5, with accuracy the authors call competitive with explicit SFT judges.
Who it affects
Teams that train or run generative reward models and LLM judges, where each preference judgment means generating rubric-based reasoning, and where voting over several samples multiplies the cost. The paper is a research result; it does not describe any product or deployment.
How to use it
There is nothing to apply directly yet. No code, model or dataset release is mentioned. The practical takeaway is the design: guide compression with the structure of rubric-based evaluations, train the judge to emit compact continuous trajectories, and keep a separate interpreter to reconstruct text when you want to inspect what was retained.
How solid is it
The claims come from the paper's own abstract, and the numbers are specific: 8.9 to 9.2x trajectory compression and 6.1 to 7.0x lower total judge inference time for LatentGRM-8B at vote@5, across four benchmark domains. Accuracy is described only as competitive with explicit SFT judges under matched training data and backbones, with no absolute figures given. The abstract names no authors or institutions. The authors also report controlled rubric interventions as evidence that criterion-dependent preference information is carried through the latent sequence.
Risks and caveats
The compression and speed figures are stated for the 8B model only, not the 4B one. The four benchmark domains, the backbones and the SFT baselines are not named, so the comparison cannot be judged from the abstract alone. The interpreter gives only an offline view of the retained information, and the judge itself no longer produces a readable assessment. "Competitive" accuracy means the latent judge is not reported as better than explicit SFT judges.
“Controlled rubric interventions show that criterion-dependent preference information is carried through the latent sequence.”
— LatentGRM paper abstract