LoopCD lifts looped Transformer accuracy with no extra training
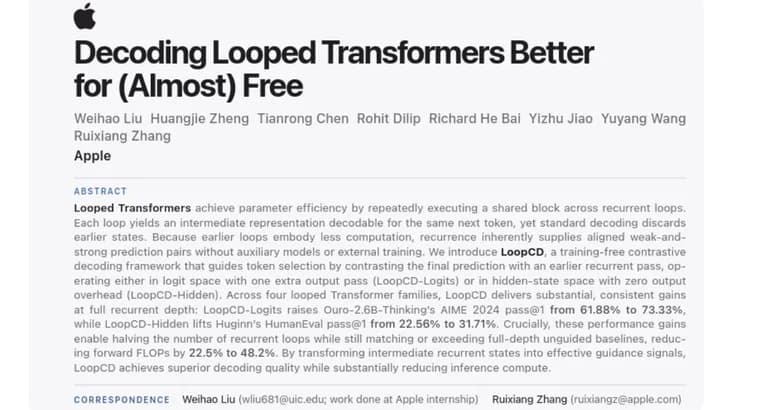
Looped Transformers save parameters by running one shared block repeatedly across recurrent loops. Each loop produces an intermediate representation that could be decoded into the same next token, but standard decoding throws those earlier states away. The paper's starting observation is that earlier loops embody less computation than later ones, so a looped model already contains pairs of weaker and stronger predictions for the same token, aligned with each other, without any auxiliary model or external training.
On that basis the authors introduce LoopCD, a training-free contrastive decoding framework. It guides token selection by contrasting the final prediction with the prediction from an earlier recurrent pass. There are two variants. LoopCD-Logits works in logit space and needs one extra output pass. LoopCD-Hidden works in hidden-state space and adds zero output overhead.
The reported results cover four looped Transformer families. At full recurrent depth, LoopCD-Logits raises Ouro-2.6B-Thinking's AIME 2024 pass@1 from 61.88% to 73.33%, a gain of about 11.5 percentage points. LoopCD-Hidden lifts Huginn's HumanEval pass@1 from 22.56% to 31.71%, a gain of about 9.2 percentage points. The authors describe the gains as substantial and consistent across the four families.
The second claim is about compute. Because the guided decoding is stronger, the authors say the number of recurrent loops can be halved while still matching or exceeding full-depth baselines that use no guidance. They report that this reduces forward FLOPs by 22.5% to 48.2%. Their summary: by turning intermediate recurrent states into guidance signals, LoopCD gives better decoding quality while substantially cutting inference compute.
Key facts
- LoopCD is a training-free contrastive decoding framework for looped Transformers: it contrasts the final prediction with the prediction from an earlier recurrent pass.
- Two variants: LoopCD-Logits (logit space, one extra output pass) and LoopCD-Hidden (hidden-state space, zero output overhead).
- At full recurrent depth, LoopCD-Logits raises Ouro-2.6B-Thinking's AIME 2024 pass@1 from 61.88% to 73.33%; LoopCD-Hidden lifts Huginn's HumanEval pass@1 from 22.56% to 31.71%.
- Halving the number of recurrent loops still matches or exceeds full-depth unguided baselines, with forward FLOPs reduced by 22.5% to 48.2%.
- Results are reported across four looped Transformer families.
Why it matters
Looped Transformers reuse one block many times to save parameters, but their intermediate states have normally gone unused at decoding time. LoopCD treats those states as a free signal: an earlier loop acts as the weaker prediction and the final loop as the stronger one, which is the pairing contrastive decoding needs. The authors say this needs no auxiliary model and no external training. If the reported numbers hold, the same model gets both better output and a cheaper inference path, since fewer loops can be run.
Who it affects
The work targets people who build or run looped Transformer models. The paper names Ouro-2.6B-Thinking and Huginn as tested models, within a set of four families. Researchers studying recurrent depth and inference-time compute are the clearest audience.
How to use it
The method operates at decoding time, so it is applied to an existing looped model rather than trained into it. The choice is between LoopCD-Logits, which costs one extra output pass, and LoopCD-Hidden, which adds no output overhead. The reported way to save compute is to run half the recurrent loops with guidance on. No code release, license or availability is mentioned in the source.
How solid is it
The source is the paper's abstract, and every figure here is the authors' own report. The headline numbers are two single data points: AIME 2024 pass@1 for Ouro-2.6B-Thinking (61.88% to 73.33%) and HumanEval pass@1 for Huginn (22.56% to 31.71%). The source does not say whether those figures are averaged over runs or what sampling settings were used. It also does not say which model or benchmark the 22.5% and 48.2% FLOPs endpoints belong to. Results for the remaining families and for other benchmarks are not reported in the abstract.
Risks and caveats
The compute saving is stated in forward FLOPs only; the abstract gives no latency or wall-clock figures. The names of the four looped Transformer families are not listed, beyond the two mentioned. The abstract names no authors or institutions and gives no date. The claim that halving loops matches or exceeds full-depth unguided baselines is the authors' statement, and the abstract does not show on which models and tasks it holds.
“By transforming intermediate recurrent states into effective guidance signals, LoopCD achieves superior decoding quality while substantially reducing inference compute.”
— From the paper's abstract