VisSearch-Bench: best of 16 multimodal models fully solves 26.47% of tasks
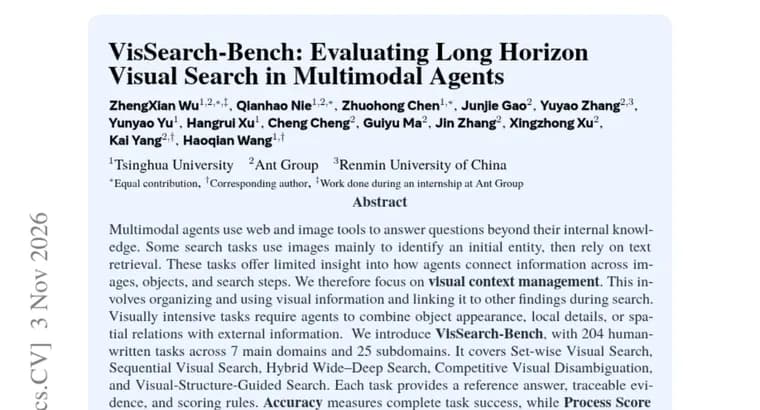
A new paper introduces VisSearch-Bench, a benchmark for multimodal agents that answer questions using web and image tools. The authors say some search tasks use images mainly to identify an initial entity and then rely on text retrieval. That gives limited insight into how agents connect information across images, objects and search steps. So the benchmark focuses on what the authors call visual context management: organizing and using visual information and linking it to other findings during search. Visually intensive tasks, they write, require agents to combine object appearance, local details or spatial relations with external information.
VisSearch-Bench has 204 human-written tasks across 7 main domains and 25 subdomains. It covers five task types: Set-wise Visual Search, Sequential Visual Search, Hybrid Wide-Deep Search, Competitive Visual Disambiguation, and Visual-Structure-Guided Search. Each task comes with a reference answer, traceable evidence and scoring rules.
Two metrics are used. Accuracy measures complete task success. Process Score measures the correctness and completeness of individual results and subquestion answers.
The authors evaluated 16 multimodal models. The best system fully solves only 26.47% of tasks, even with search tools. They say the results highlight the challenge of linking visual evidence with search results to produce complete answers.
Key facts
- VisSearch-Bench has 204 human-written tasks across 7 main domains and 25 subdomains.
- It covers five task types: Set-wise Visual Search, Sequential Visual Search, Hybrid Wide-Deep Search, Competitive Visual Disambiguation, and Visual-Structure-Guided Search.
- Each task provides a reference answer, traceable evidence and scoring rules.
- Accuracy measures complete task success; Process Score measures the correctness and completeness of individual results and subquestion answers.
- Across 16 multimodal models, the best system fully solves only 26.47% of tasks, even with search tools.
Why it matters
The authors argue that some search tasks use an image mainly to identify a starting entity, after which the agent leans on text retrieval. Such tasks reveal little about whether an agent can carry visual information through a long search and tie it to other findings. VisSearch-Bench is built to test exactly that. The headline result is stark: the best of 16 models fully solves 26.47% of the 204 tasks, even with search tools.
Who it affects
Researchers and developers building multimodal agents that combine web search with image tools are the natural audience, since the benchmark targets how such agents connect visual evidence with search results. The paper's own framing is about agents that answer questions beyond their internal knowledge.
How to use it
The benchmark supplies 204 tasks, each with a reference answer, traceable evidence and scoring rules, plus two metrics: Accuracy for complete task success and Process Score for the correctness and completeness of individual results and subquestion answers. Teams can use these to check an agent on set-wise, sequential, hybrid wide-deep, competitive disambiguation and visual-structure-guided search.
How solid is it
The text is a paper abstract. It states the benchmark size (204 tasks, 7 main domains, 25 subdomains) and one headline result: 26.47% full success for the best of 16 models. The 26.47% figure is an absolute share of tasks fully solved, not a gain over a baseline. The abstract does not name the models or say which one is the best system, and gives no Process Score figures.
Risks and caveats
Only the headline Accuracy-type figure is available here. The abstract gives no breakdown by task type or domain, no results for runs without search tools, and no Process Score numbers, so it is hard to say where models fail most. The conclusion about the difficulty of linking visual evidence with search results is the authors' own reading of their results.