WeVisOne-VL unifies object and pixel perception in one open vision-language model
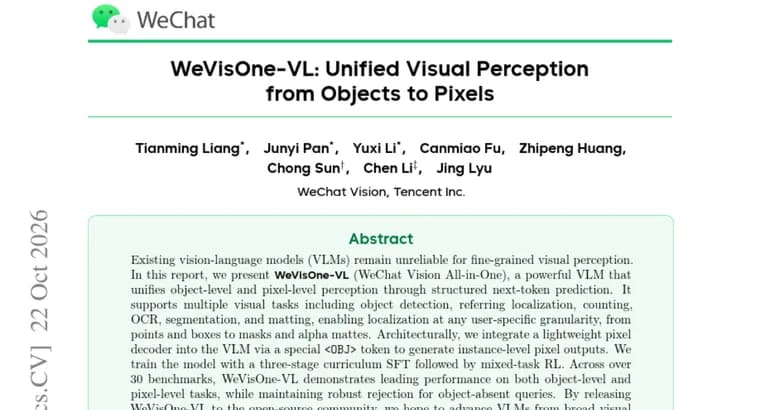
A report on Hugging Face Papers introduces WeVisOne-VL, short for WeChat Vision All-in-One. The authors start from a complaint: existing vision-language models (VLMs) remain unreliable for fine-grained visual perception. Their answer is a single model that unifies object-level and pixel-level perception through structured next-token prediction.
The model covers a wide set of visual tasks: object detection, referring localization, counting, OCR, segmentation and matting. It can localize at whatever granularity the user asks for, from points and boxes to masks and alpha mattes.
On the architecture side, the authors integrate a lightweight pixel decoder into the VLM through a special
Across over 30 benchmarks, the authors say WeVisOne-VL shows leading performance on both object-level and pixel-level tasks, while keeping robust rejection for object-absent queries, meaning it can decline to localize something that is not in the image. They are releasing the model to the open-source community, in the hope of moving VLMs from broad visual understanding toward perception systems reliable enough for real-world deployment.
The source text is the report's abstract. It gives no benchmark names, scores, parameter count, base model, license or repository link.
Key facts
- WeVisOne-VL (WeChat Vision All-in-One) is a VLM that unifies object-level and pixel-level perception through structured next-token prediction.
- It supports object detection, referring localization, counting, OCR, segmentation and matting, with outputs from points and boxes to masks and alpha mattes.
- A lightweight pixel decoder is attached to the VLM via a special
token to produce instance-level pixel outputs. - Training uses a three-stage curriculum SFT followed by mixed-task RL.
- The authors report leading performance across over 30 benchmarks, plus robust rejection for object-absent queries, and release the model as open source.
Why it matters
The authors' starting point is that existing VLMs remain unreliable for fine-grained visual perception. This report claims one VLM can cover detection, counting, OCR, segmentation and matting, at the granularity the user picks. The authors frame the open release as a step from broad visual understanding toward perception reliable enough for real-world deployment.
Who it affects
Researchers and developers building vision-language systems that need precise localization, such as boxes, masks or alpha mattes, will find the most relevant material here. The model is released to the open-source community, so it is aimed at that audience.
How to use it
The model supports tasks including object detection, referring localization, counting, OCR, segmentation and matting. Users can request localization at the granularity they need, from points and boxes to masks and alpha mattes. The abstract does not give a license, repository link or release date, so check the paper page for those details.
How solid is it
The claims are the authors' own, drawn from the report's abstract. They say the model leads on both object-level and pixel-level tasks across over 30 benchmarks, but the abstract names no benchmarks, scores or baselines, so the size of the lead cannot be judged from this text. The same goes for the three SFT stages and the RL setup, which are mentioned but not described.
Risks and caveats
'Leading performance' is not quantified in the source. Model size, base VLM, license and repository are not stated. The model is said to reject object-absent queries robustly, but no figures back that up here. Independent evaluation would be needed to confirm the reported results.