WorldDraft benchmark tests whether video models can render code-built 4D worlds
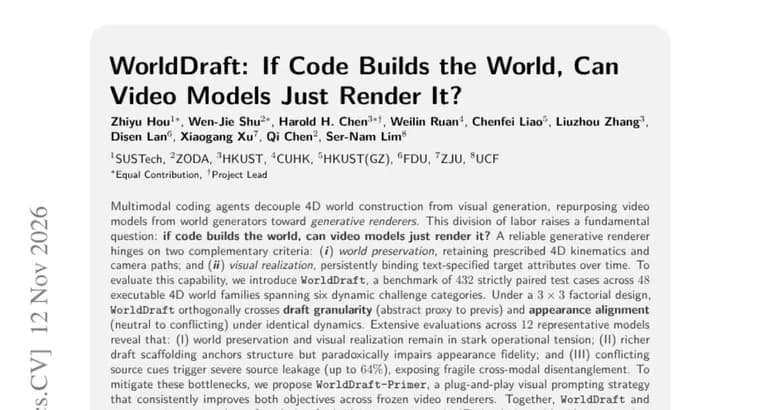
The paper starts from a division of labor that multimodal coding agents are creating. The agent builds a 4D world in code, meaning objects with prescribed motion and a camera path, and a video model handles the visual generation. That shifts video models from being world generators toward being generative renderers. The authors ask the obvious question: if code builds the world, can video models just render it?
They say a reliable generative renderer has to meet two criteria. The first is world preservation: keeping the prescribed 4D kinematics and camera paths intact. The second is visual realization: persistently binding text-specified target attributes, such as the requested appearance, over time.
To test this they introduce WorldDraft, a benchmark of 432 strictly paired test cases across 48 executable 4D world families. The families span six dynamic challenge categories. The design is a 3 times 3 factorial: it crosses draft granularity (from an abstract proxy up to previs) with appearance alignment (from neutral to conflicting), while keeping the dynamics identical across conditions.
The team evaluated 12 representative models and reports three findings. First, world preservation and visual realization stay in stark operational tension: doing well on one tends to come at the expense of the other. Second, richer draft scaffolding anchors structure but, paradoxically, impairs appearance fidelity. Third, conflicting source cues trigger severe source leakage, up to 64%, which the authors read as exposing fragile cross-modal disentanglement.
To mitigate these weaknesses, they propose WorldDraft-Primer, a plug-and-play visual prompting strategy. According to the abstract it consistently improves both objectives across frozen video renderers. The authors conclude that WorldDraft and WorldDraft-Primer lay a foundation for bridging programmatic 4D simulation with video generation, advancing physically grounded generative rendering.
Key facts
- WorldDraft is a benchmark of 432 strictly paired test cases across 48 executable 4D world families and six dynamic challenge categories.
- It uses a 3 times 3 factorial design crossing draft granularity (abstract proxy to previs) with appearance alignment (neutral to conflicting) under identical dynamics.
- Across 12 representative models, keeping the world's motion and applying the requested appearance stay in stark tension, and richer drafts anchor structure but impair appearance fidelity.
- Conflicting source cues cause severe source leakage, up to 64%.
- WorldDraft-Primer, a plug-and-play visual prompting strategy, consistently improves both objectives across frozen video renderers.
Why it matters
Coding agents can now build a scene with exact motion and camera paths, which leaves the visual generation to a video model. That only works if the video model respects what the code specified and also applies the look the user asked for. WorldDraft is an attempt to measure exactly that, and the early answer is not flattering: across 12 models the two goals pull against each other. Giving the model a richer draft to follow helps it keep the structure but hurts how well it matches the requested appearance.
Who it affects
Researchers building or evaluating video generation models, and teams working on pipelines where a coding agent constructs a 4D world and a video model renders it. The benchmark also speaks to anyone interested in linking programmatic 4D simulation with video generation.
How to use it
The practical piece is WorldDraft-Primer, described as a plug-and-play visual prompting strategy that works on frozen video renderers, so it does not require retraining the model. The benchmark's design, with drafts ranging from abstract proxies to previs and appearance targets from neutral to conflicting, also gives a template for stress-testing a renderer. No release, code, dataset availability or license is mentioned.
How solid is it
This is a preprint abstract, and the claims are the authors' own. The numbers are concrete about the benchmark's size: 432 paired cases, 48 world families, six challenge categories, 12 models. The results are stated only in broad terms. No authors or institutions are named. No model names are given for the 12 evaluated models, and there is no ranking or per-model results. The abstract does not say which model or condition produced the 64% source leakage, nor how leakage is measured. No magnitude is given for the improvement from WorldDraft-Primer beyond 'consistently improves both objectives'.
Risks and caveats
The 64% figure is an upper bound, so it should not be read as typical behavior. Without model names or per-model results, it is unclear which renderers struggle most. The claim that Primer helps is stated without a size of the gain. Findings from a 432-case benchmark of 48 world families may not carry over to every kind of code-built world.
“if code builds the world, can video models just render it?”
— WorldDraft paper abstract