Microsoft open-sources RetroChimera for synthesis prediction
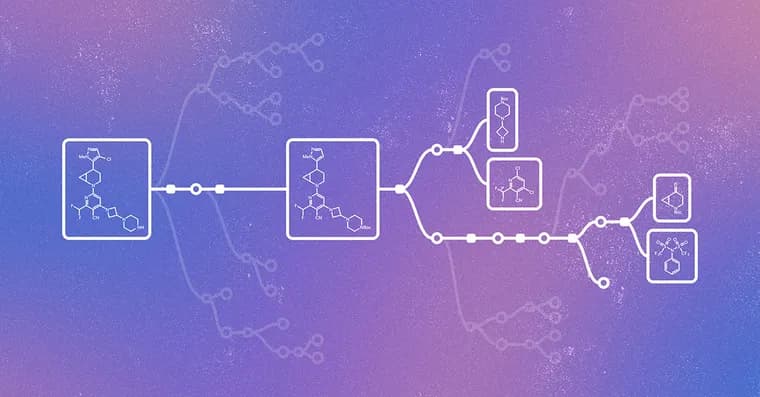
Microsoft Research has published a paper in the journal Nature describing RetroChimera, a new model for retrosynthesis prediction: given a target molecule, it proposes a sequence of chemical reactions that could build it from simpler, purchasable precursors. Planning these routes by hand is slow and expensive, and it has become a bottleneck in drug and materials discovery even as computational methods make it cheap to generate large numbers of candidate molecules. RetroChimera works by combining two sub-models with different strengths. R-SMILES 2 is a Transformer-based de-novo model that predicts precursor molecules directly from the target, which gives it flexibility to learn reaction patterns from data but also makes its unconstrained output prone to hallucination. NeuralLoc is a graph neural network model that instead selects reaction templates from a library and predicts where to apply them to the target molecule's graph; its predictions stay grounded in patterns seen during training, but it struggles with reactions the template library does not cover. According to Microsoft, R-SMILES 2 tends to do well on reactions involving large structural changes, while NeuralLoc excels at rare, low-precedence reactions and more localized changes. RetroChimera merges the two by having each sub-model cast a learned, rank-dependent vote on every predicted set of reactants, adding the votes together when both models propose the same reaction; this lets the combined system approximate whichever sub-model performs better for a given reaction class. Microsoft reports that in blind tests, PhD-level chemists preferred RetroChimera's individual reaction predictions over both preceding models and reactions recorded in the literature. In a separate blind test on disconnecting complex molecules, chemists preferred RetroChimera's suggestions over those from its own constituent sub-models, over more established retrosynthesis approaches, and even over the reactions recorded in the test set itself. The paper's authors say the model could help researchers evaluate more, and more structurally complex, candidate molecules in drug discovery and materials design, and that pairing it with laboratory automation could push toward closed-loop, self-improving synthesis systems. RetroChimera's implementation and trained weights are released on GitHub under the MIT license, and the model is also accessible through Microsoft Foundry; instructions for obtaining the model checkpoint are in the GitHub repository. The source material gives no individual author names or institutional affiliations, no publication date, no quantitative accuracy or benchmark figures, no dataset sizes, and no count of how many chemists took part in the blind tests.
Key facts
- RetroChimera, described in a paper published in Nature, combines two sub-models: R-SMILES 2, a Transformer-based de-novo model, and NeuralLoc, a graph neural network that works from reaction templates.
- The two sub-models are combined through a learned ensembling strategy: each casts a rank-dependent vote on predicted reactant sets, and votes are added when both models agree on a reaction.
- In blind tests, PhD-level chemists preferred RetroChimera's individual reaction predictions over preceding models and over reactions recorded in the literature.
- In a separate blind test on complex-molecule disconnections, chemists preferred RetroChimera's suggestions over its own sub-models, over established approaches, and over the test set itself.
- RetroChimera's implementation and weights are open-sourced on GitHub under the MIT license and are also accessible through Microsoft Foundry.
Why it matters
Retrosynthesis, working backward from a target molecule to a buildable sequence of simpler precursors, is described by Microsoft as still largely manual, time-consuming and a significant driver of drug development costs. That is a growing bottleneck: computational chemistry can now propose huge numbers of candidate molecules, but finding a practical way to actually make each one remains the hard part. RetroChimera targets that gap directly, automatically proposing synthesis routes instead of leaving the search to specialist chemists.
Who it affects
The intended users are chemists and researchers in drug discovery, materials science and sustainable agriculture who currently plan synthesis routes largely by hand. Microsoft frames the tool as a way to let them assess more candidate molecules, and more structurally complex ones, within the same design-make-test cycle.
How to use it
RetroChimera's implementation and trained weights are open-sourced on GitHub under the MIT license, and the model is also accessible via Microsoft Foundry. Instructions for obtaining the model checkpoint are provided in the GitHub repository. The source gives no pricing or compute-requirement details.
How solid is it
The method is described in a peer-reviewed paper in Nature, with what Microsoft calls extensive validation, including tests of the model's ability to recall rare reaction types and its ability to transfer to proprietary datasets via zero-shot use and fine-tuning. The headline evidence comes from two separate blind tests in which PhD-level or expert chemists preferred RetroChimera's suggestions over preceding models, literature reactions, its own two sub-models, established approaches, and even the test set itself. No participant counts, accuracy figures or benchmark percentages accompany these claims in the source material, so the scale behind them cannot be quantified here.
Risks and caveats
The de-novo sub-model, R-SMILES 2, is explicitly described as prone to hallucination because of its unconstrained generation, a weakness the ensemble is designed to offset rather than eliminate. The template-based sub-model, NeuralLoc, is in turn more constrained and struggles with reactions its template library does not cover. The source does not name the researchers or their institutions, gives no publication date, and states no dataset sizes or benchmark numbers, so independent verification of the reported gains is not possible from this material alone.
“In blind tests, PhD-level chemists prefer RetroChimera's individual reaction predictions over preceding models and recorded literature reactions.”
— Microsoft Research, blog post announcing RetroChimera