MintAct unifies UI agents across mobile, desktop and web
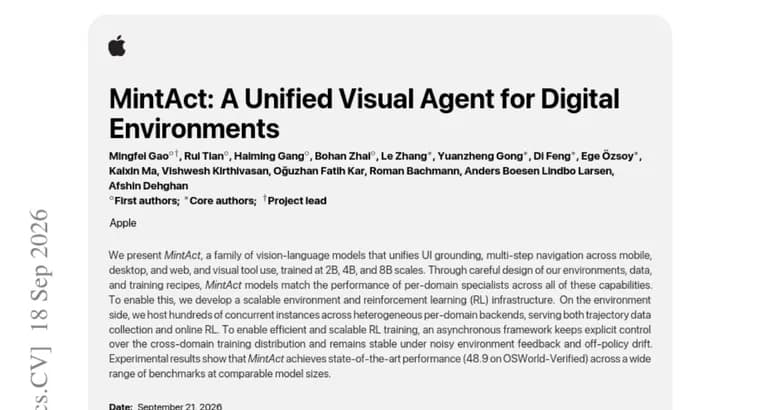
Researchers present MintAct, a family of vision-language models trained at three parameter scales, 2B, 4B, and 8B, built to unify three capabilities that UI agents usually handle with separate specialist systems: UI grounding, multi-step navigation across mobile, desktop, and web, and visual tool use. According to the authors, MintAct models match the performance of per-domain specialist models across all of these capabilities despite being a single unified system rather than several narrow ones.
To train models that generalize across such different environments, the authors built a scalable environment and reinforcement learning infrastructure. On the environment side, they host hundreds of concurrent instances spread across heterogeneous per-domain backends, serving both trajectory data collection and online RL. On the training side, an asynchronous framework keeps explicit control over how training data is distributed across domains; the authors report it stays stable under noisy environment feedback and off-policy drift, both common failure modes when reinforcement learning runs across many different environments at once.
The authors report that MintAct achieves state-of-the-art performance across a wide range of benchmarks at comparable model sizes, citing a score of 48.9 on OSWorld-Verified as the headline result. The text does not name individual authors or institutions, does not give a release date, license terms, or code and model availability, and does not identify which per-domain specialist models MintAct is compared against. No benchmark results beyond the OSWorld-Verified figure appear in the text, despite the claim of state-of-the-art performance across "a wide range of benchmarks," and no training data size, compute budget, or hardware details are disclosed.
Key facts
- MintAct is a family of vision-language models trained at 2B, 4B, and 8B parameter scales, unifying UI grounding, multi-step navigation, and visual tool use in one system.
- The authors report MintAct matches the performance of per-domain specialist models across all of these capabilities.
- A scalable environment hosts hundreds of concurrent instances across heterogeneous per-domain backends for trajectory data collection and online RL.
- An asynchronous RL training framework keeps explicit control over the cross-domain training distribution and stays stable under noisy environment feedback and off-policy drift.
- MintAct scores 48.9 on OSWorld-Verified, described as state-of-the-art, though no other benchmark numbers are given in the text.
Why it matters
Most UI agents today are built as specialists: one model for mobile apps, another for desktop software, another for the browser, each trained and evaluated on its own. MintAct's claim is that a single family of models, trained at three sizes, can match those specialists across UI grounding, navigation, and tool use at once, rather than trading generality for performance. If that holds up, it points toward agent systems that do not need a different model per platform.
Who it affects
The paper speaks to teams building or evaluating computer-use and UI-automation agents, and to researchers working on reinforcement learning infrastructure for environments that are heterogeneous and run at scale. It describes no product release, so end users of any specific tool are not directly affected yet.
How to use it
The text gives no release date, license terms, or code and model availability, so there is nothing to install or call today. It does not mention pricing or access tiers.
How solid is it
The central number is a score of 48.9 on OSWorld-Verified, which the authors describe as state-of-the-art. The text asserts state-of-the-art performance "across a wide range of benchmarks," but only this single figure is given, and the per-domain specialist models MintAct is compared against are not named. The training infrastructure claims, hundreds of concurrent environment instances and an asynchronous cross-domain RL framework, are described but not quantified with step counts, wall-clock time, or hardware used.
Risks and caveats
The text does not name individual authors or institutions, so there is no way to check the team's track record or funding source from the material alone. Without the comparison specialists named or additional benchmark numbers shown, the claim of state-of-the-art performance across a wide range of benchmarks rests on a single reported score and the authors' own framing.