Multi-Branch Transformer runs parallel blocks for faster decoding
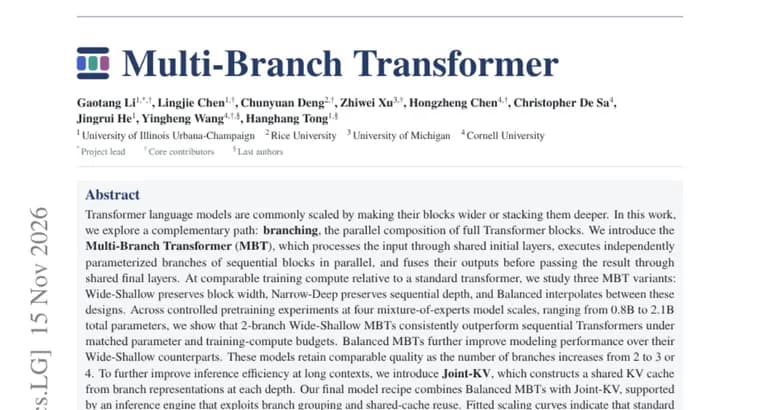
Language models are usually scaled by making Transformer blocks wider or stacking them deeper. A paper listed on Hugging Face Papers explores what its authors call a complementary path: branching, the parallel composition of full Transformer blocks.
The Multi-Branch Transformer (MBT) sends the input through shared initial layers, then runs independently parameterized branches of sequential blocks in parallel, and fuses their outputs before shared final layers. At comparable training compute the paper studies three variants. Wide-Shallow preserves block width, Narrow-Deep preserves sequential depth, and Balanced interpolates between the two.
The controlled pretraining experiments use four mixture-of-experts scales, from 0.8B to 2.1B total parameters. In those runs, 2-branch Wide-Shallow MBTs consistently outperform sequential Transformers under matched parameter and training-compute budgets. Balanced MBTs improve further and keep comparable quality as the number of branches grows.
For long contexts the authors add Joint-KV, which builds a shared KV cache from the branch representations at each depth. Their final recipe combines Balanced MBTs with Joint-KV and is supported by an inference engine that exploits branch grouping and shared-cache reuse.
The headline numbers are all stated as maxima. Fitted scaling curves indicate that standard Transformers need up to 1.26x as much training body compute to match the final MBT models' validation loss. The final models reduce full-model KV-cache storage by up to 34% and deliver up to 51.4% higher decoding throughput on a single H200 GPU.
Ablation studies, according to the paper, show that branching yields gains beyond changes in width and depth, enables an effective KV-sharing strategy (Joint-KV), remains robust across fusion functions, and performs best in the middle layers. The authors conclude that branching offers a practical path for scaling language models toward both better modeling quality and faster inference.
Key facts
- MBT runs independently parameterized branches of sequential Transformer blocks in parallel between shared initial and shared final layers, then fuses their outputs.
- In pretraining at four mixture-of-experts scales (0.8B to 2.1B total parameters), 2-branch Wide-Shallow MBTs consistently beat sequential Transformers at matched parameters and training compute.
- Joint-KV builds a shared KV cache from branch representations at each depth; the final models cut full-model KV-cache storage by up to 34%.
- The final models deliver up to 51.4% higher decoding throughput on a single H200 GPU.
- Fitted scaling curves suggest a standard Transformer needs up to 1.26x as much training body compute to match the final MBT models' validation loss.
Why it matters
Making blocks wider or deeper is the usual way to scale a Transformer. This paper argues for a third axis: running full blocks side by side as branches. The pitch is that this improves both modeling quality at matched compute and inference speed, rather than trading one for the other. If the results hold at larger scale, it would be a different way to spend a fixed parameter and compute budget.
Who it affects
Mainly researchers and engineers who design and pretrain language model architectures, and teams that care about decoding throughput and KV-cache memory at long contexts. The experiments are on mixture-of-experts models, so the closest relevance is to people working with models of that kind.
How to use it
This is a research proposal, not a product. The abstract describes the recipe: Balanced MBT variants combined with Joint-KV and an inference engine that exploits branch grouping and shared-cache reuse. No code, model release or open-source availability is mentioned. A practitioner can treat it as an architecture idea to track until an implementation appears.
How solid is it
The evidence comes from controlled pretraining experiments at four scales and from ablation studies, all reported by the authors in the abstract. Fitted scaling curves back the 1.26x compute figure. The 1.26x, 34% and 51.4% figures are all stated as 'up to' maxima, not typical or average values. The text does not say which baseline or context length the 34% KV-cache reduction and 51.4% throughput gain are measured against. No authors or institutions are named in the text.
Risks and caveats
The scale results cover only 0.8B to 2.1B total-parameter mixture-of-experts models; nothing is said about larger models or dense models. Because the speed and memory gains are best-case figures, real-world benefit may be smaller. The gains also depend on the custom inference engine described in the paper. The text names no specific fusion functions, so what the robustness claim covers is unclear from the abstract alone.
“branching offers a practical path for scaling language models toward both better modeling quality and faster inference”
— Abstract of the Multi-Branch Transformer paper