Nvidia pays $20 billion for Groq's talent and IP as AI shifts to inference
Since around 2020, the AI industry's attention has been fixed on training ever bigger models: OpenAI's GPT-3, released that year, correctly answered just 43.9 percent of questions on a popular knowledge-and-reasoning benchmark, and GPT-4o reached 88.7 percent on the same benchmark four years later, a leap the article calls "effectively matching" human-expert scores. By 2026, that emphasis has flipped toward inference, the use of a trained model to actually produce answers. "It's like training is yesterday's news," says Matt Kimball, principal data-center analyst at Moor Insights & Strategy. "All that any chief information officer wants to talk about is inference." Nvidia CEO Jensen Huang, speaking at the company's GTC 2026 conference, called the shift the "inflection point of inference."
Two forces are multiplying inference demand at once. Many of today's models are reasoning models that reprompt themselves through a chain-of-thought process, running inference several times per query instead of once; models set to high reasoning effort can generate up to 20 times as much text as those with low or no effort. Separately, agentic AI now keeps inference running continuously, working autonomously toward a user-defined goal around the clock rather than only answering a single prompt.
That demand has produced some unlikely hardware alliances. OpenAI and Amazon have both deployed chips "the size of a dinner plate" made by Cerebras, even though Amazon already has its own Trainium chips; Amazon Web Services now splits inference workloads between the two, running the more computationally complex portion on Trainium and the more memory-intensive portion on Cerebras's wafer-scale engine. Nvidia bought talent and intellectual property from AI-inference startup Groq in a deal the article calls controversial, worth $20 billion. Anthropic, for its part, pays over $1 billion a month to lease spare compute from SpaceXAI, a rival that trains the Grok family of large language models. Groq, the chip startup, and Grok, the model family, are unrelated companies that the source is careful to distinguish.
The article explains the underlying difference technically. An untrained model is like a jumble of Scrabble tiles that show word fragments, called tokens, rather than single letters: everything needed to write almost anything is present, but arranged randomly. Training organizes that jumble through a guessing game played at huge scale: the model is shown real text with the next token hidden, predicts it, is corrected, and adjusts billions or trillions of parameters through backpropagation, a computationally heavy process, over billions of passages, until the model's creator decides further training isn't worth the cost. Backpropagation then stops, the parameters freeze into a pretrained model, and fine-tuning, a short extra training run on smaller, specialized data, adds final tweaks before deployment.
Inference is the process of using that deployed model, and it brings its own challenge even though it skips backpropagation: the models are "autoregressive," meaning each output depends on the one before it. "So to generate the next token, you have to read all of the weights and all of the [context] from the previous token," explains Sudeep Bhoja, founder and CTO of inference-hardware company d-Matrix, where the context means every prompt, every reply and every uploaded file in the conversation so far. Producing a reply happens in two phases. Prefill is the model reading the prompt: it processes every token at once, computing how each one relates to all the others, an operation called attention and a defining trait of the transformer architecture behind modern LLMs; this produces keys and values that are typically stored in a KV cache, a memory scratchpad that starts small but can swell to dozens of gigabytes over a conversation. Decode comes next: the model generates its reply one token at a time, weighing the newest token against everything already in the KV cache to predict the next one, then adding that token's own key and value back into the cache, and repeating.
Prefill divides up easily and runs in parallel, which is why GPUs, already built for the similarly parallel math of rendering graphics, became AI's dominant accelerator. Decode does not divide the same way: because each token depends on the last, predicting it means reading the model's entire set of parameters, possibly tens to hundreds of gigabytes, from memory at every single step, on top of the KV cache. That data movement frequently demands more bandwidth than inference hardware has on hand, so some of a GPU's compute sits idle while it waits; researchers found that Nvidia H100 GPUs running open-source LLMs sit idle 50 to 80 percent of the time. "With the GPU-based approach, you end up greatly over-provisioning compute and starved on memory," says Shahriar "Sha" Rabii, former head of silicon engineering at Meta and now cofounder of AI startup Majestic Labs. "That's driving the big [memory] scale out."
Two accelerator startups attack that bottleneck from opposite directions. d-Matrix's second-generation chip, Raptor, shortens the physical distance between compute and memory by stacking an AI accelerator directly on a DRAM die, rather than placing high-bandwidth memory (HBM) around a GPU's perimeter the way most current inference deployments do; Bhoja says this cuts the distance data has to travel to "micrometers instead of millimeters." Majestic Labs goes the other way, leaving compute and memory apart but upgrading the memory interface itself: a proprietary copper link and a memory-aggregator chip let it connect to DRAM stacks about a meter away, far past the 2 to 3 millimeters a standard HBM interface can span, according to Rabii. Majestic says that lets it support up to 128 terabytes of DRAM in a single server rack, against about 20 terabytes of HBM3E in Nvidia's GB300 NVL72 rack. Both companies chose ordinary, off-the-shelf DRAM over HBM partly on price: memory analyst Jim Handy says HBM costs two to three times as much as DRAM.
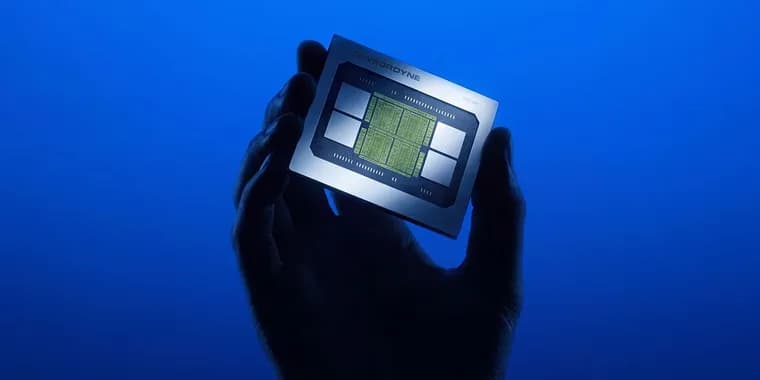
HBM's backers, memory giants including Samsung and SK Hynix, are not standing still either. HBM4, the newest version of the standard, is already in production and will ship in Nvidia's Vera Rubin GPU in the second half of 2026; Hoshik Kim, head of memory-systems research at SK Hynix, says HBM4 "will decisively break the memory bottlenecks constraining AI inference today" by doubling HBM's maximum bandwidth and increasing how much memory fits on each stack. For now, the largest players are hedging across both camps: Nvidia's GPUs and Amazon's Trainium chips remain well suited to prefill, but for decode, both companies are turning to memory-centric designs from smaller players, which in Nvidia's case meant buying Groq's talent and intellectual property at the end of 2025. The article separately captions a chip as "Nvidia's Groq 3 language-processing unit," said to cut data movement by placing on-chip SRAM memory and computational blocks in the order they're needed, but the available text breaks off mid-sentence just before it reaches what Nvidia announced three months later, at its GTC 2026 conference, so that part of the story is not covered here.
Key facts
- OpenAI's GPT-3 (2020) answered just 43.9 percent of questions correctly on an unnamed knowledge-and-reasoning benchmark; GPT-4o reached 88.7 percent on the same benchmark four years later, a score the article calls "effectively matching" human experts.
- Nvidia paid a controversial $20 billion for talent and intellectual property from AI-inference startup Groq, distinct from Grok, the large-language-model family trained by SpaceXAI, the rival Anthropic separately pays over $1 billion a month to lease spare compute from.
- Researchers found Nvidia H100 GPUs running open-source LLMs sit idle 50 to 80 percent of the time, because generating each token during decode requires reading a model's entire parameters, tens to hundreds of gigabytes, from memory at every step.
- Startups d-Matrix and Majestic Labs both replace costly HBM memory with off-the-shelf DRAM, which analyst Jim Handy says costs a third to a half as much; Majestic says its design can support up to 128 terabytes of memory per server rack, against about 20 terabytes of HBM3E in Nvidia's GB300 NVL72 rack.
- HBM makers are responding too: SK Hynix's HBM4, shipping in Nvidia's Vera Rubin GPU in the second half of 2026, will double HBM's maximum memory bandwidth, the company says.
Why it matters
The AI industry's center of gravity is moving from training frontier models to running them at scale, and 2026 is being framed as the year that shift became undeniable. Matt Kimball of Moor Insights & Strategy puts it bluntly: "It's like training is yesterday's news. All that any chief information officer wants to talk about is inference." Nvidia CEO Jensen Huang, at the company's GTC 2026 conference, called it the "inflection point of inference." Two things are multiplying inference demand at once: reasoning models that reprompt themselves through chain-of-thought, with high-reasoning-effort versions generating up to 20 times as much text as those run at low or no effort, and agentic AI systems that run inference continuously, pursuing a goal around the clock instead of answering one prompt at a time. Inference, unlike training, is bottlenecked by memory bandwidth rather than raw compute, which is forcing a redesign of AI hardware from the chip up, not just a change in how existing chips get used.
Who it affects
Chipmakers and cloud providers are the most directly affected. Nvidia, which built its dominance on training-oriented GPUs, bought inference-specific talent and intellectual property from Groq for $20 billion; Amazon is splitting inference workloads between its own Trainium chips and Cerebras's wafer-scale engine even though it already owns Trainium, and OpenAI has likewise deployed Cerebras hardware. Smaller, memory-focused challengers d-Matrix and Majestic Labs stand to gain if their DRAM-based designs catch on with buyers who currently default to GPUs and HBM. Memory suppliers are affected too: Samsung and SK Hynix are defending HBM's position with the newer HBM4 standard, while independent analyst Jim Handy notes the DRAM these challengers use costs a third to a half as much. And AI labs' own compute bills are on the line, illustrated by Anthropic paying over $1 billion a month to SpaceXAI, a rival, just to lease spare compute.
How to use it
There's no single product to buy here, more a map of the tradeoffs facing anyone provisioning inference capacity in 2026. Teams leaning on reasoning models or always-on agents, the workloads the article blames for the current surge, are the ones most likely to run into the bottleneck it describes, since it's decode, not prefill, where GPUs reportedly sit idle 50 to 80 percent of the time. At a high level, the piece lays out two paths: stay with GPUs and HBM and wait for HBM4, which SK Hynix says will double memory bandwidth when it ships in Nvidia's Vera Rubin GPU in the second half of 2026, or look at memory-centric, DRAM-based alternatives such as d-Matrix's Raptor or Majestic Labs' design, which Majestic says can support up to 128 terabytes per server rack against about 20 terabytes of HBM3E on Nvidia's GB300 NVL72 rack. The underlying memory economics favor the challengers on paper: HBM runs two to three times the price of the off-the-shelf DRAM that d-Matrix and Majestic use instead, according to analyst Jim Handy.
How solid is it
This is an IEEE Spectrum feature that draws on named, credentialed sources across competing interests: an independent analyst (Kimball of Moor Insights & Strategy), company executives with something to sell (Nvidia's Huang, d-Matrix's Bhoja, Majestic's Rabii, SK Hynix's Kim), and an independent memory-industry analyst (Handy) whose figures offer some check on the vendor claims. Still, several of the most striking numbers are self-reported by interested parties rather than independently measured: Majestic's 128-terabyte-per-rack figure and its "about a meter" transmission-distance claim are both attributed to the company itself, and the 50-to-80-percent GPU idle figure is credited only to unnamed "researchers." The benchmark behind the 43.9-to-88.7-percent GPT-3-to-GPT-4o comparison is likewise never named, only called "a popular knowledge-and-reasoning benchmark." The material available for this account also cuts off mid-sentence just before describing what Nvidia announced at its GTC 2026 conference, three months after the Groq purchase, so that part could not be verified here.
Risks and caveats
The "controversial" label on Nvidia's $20 billion Groq deal is the article's own framing; treat it as the outlet's characterization rather than an independently established finding. The piece is also careful to separate two similarly named things that are easy to conflate: Groq, the AI-inference chip startup Nvidia bought talent and intellectual property from, and Grok, the large-language-model family trained by SpaceXAI, the company Anthropic separately pays over $1 billion a month to lease spare compute from. Vendor capacity and distance claims, such as Majestic's 128 terabytes per rack and its about-a-meter memory interface, come from Majestic itself, in the company's own words, rather than from an outside measurement. And because the source material breaks off before the GTC 2026 announcement it was building toward, whatever concrete news Nvidia had to share there, plausibly tied to its newly acquired Groq talent and the "Groq 3" chip the piece separately references, is not covered in this account.
“It's like training is yesterday's news”
— Matt Kimball, principal data-center analyst at Moor Insights & Strategy