OpenAI used LLMs to design its Jalapeño AI chip
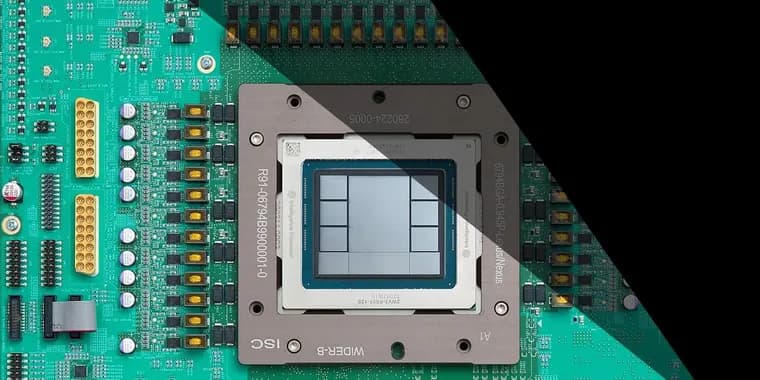
OpenAI fully unveiled Jalapeño, its first AI accelerator chip, on 25 August. The chip delivers up to 13.4 petaflops of 4-bit compute and accesses 232 gigabytes of memory over a 15.4 terabytes-per-second link. OpenAI-cited benchmarks show it can cut end-to-end latency, the time from prompt to last token, by up to 3.6x compared with Nvidia's GB300, the chip OpenAI currently relies on, while using less power. Deployment pods hold 2,048 chips.
IEEE Spectrum's Matthew S. Smith reports on the other half of the story: how the chip was designed. Jalapeño moved from first architecture concept to first silicon in under 20 months, with only nine months separating the first RTL, the register-transfer level code defining the chip's logic, from tapeout, when the finished design goes to manufacturing. The team that designed it averaged fewer than 100 people over the project and still stands at roughly 100 as it works on second and third-generation chips. Richard Ho, OpenAI's vice president of hardware, says the split with Broadcom was straightforward: OpenAI owned end-to-end system design, including the inference accelerator, memory hierarchy and networking, while Broadcom handled "physical design from the gates onward." "The models are giving superpowers to our engineers," Ho says. "Our engineers are still driving the work, they're still the final arbiter of what's going on. But they can do things a lot faster, they can explore a lot more paths."
Outside experts largely credit the pace to the Broadcom partnership rather than to AI alone. Verkor.io co-founder David Chin says "the schedule they gave us is quite credible," but adds that "if you have somebody else start from scratch, it won't be possible." His co-founder Ravi Krishna calls the speed "a relatively impressive result" and expects LLM gains could make it even faster today. Andrew Kahng, a distinguished professor at UC San Diego who has followed chip-design automation since organizing a 2016 IEEE workshop where Ho spoke as a Google engineer, called the pace "likely best in class today."
OpenAI's front-end workflow, the part from concept through RTL and verification, was built around Accelerated Hardware Synthesis (XLS), an open-source high-level synthesis toolchain originally developed at Google, letting engineers write in DSLX (a Rust-inspired domain-specific language) or C++ and have it converted to Verilog. Chris Leary, an OpenAI staff member who started XLS while at Google, says the team leaned on AI here because "the AI was much better at software-looking things," and "XLS in some ways looks like software, so it got that benefit." Ankur Srivastava, director of semiconductor initiatives at the University of Maryland, says chip-design automation is decades old, but LLMs' grasp of language and code suits tasks that are "still in the linguistic domain of the problem." Kahng agrees the XLS-style approach is "a generally useful workflow" that "has legs."
The same logic drove software optimization once first chips arrived from the foundry in May: OpenAI's internal AI models targeted benchmarks such as SemiAnalysis' InferenceX, and on DeepSeek's multi-head latent attention kernel benchmark, performance climbed from 0.31 percent of the theoretical compute-and-memory-bandwidth ceiling to 88.94 percent in roughly 40 hours. Ho says the result is repeatable, shortening the gap between first silicon and production ramp.
The models themselves evolved over the project. Work began with assistance from OpenAI's o3, public since April 2025 but available to the Jalapeño team earlier; by the project's end the team had precursors to GPT-6 Astra, not publicly released until 3 September 2026, which Leary says can work directly in Verilog without XLS's translation step and is close to operating proprietary design tools on its own. Ho also confirmed access to internal LLMs fine-tuned for chip design, not available publicly, though he declined to name them; the goal, he says, is to feed lessons from Jalapeño back into OpenAI's commercial models, and "it's safe to say that Astra and following models will be very good at chip design."
Backend work, routing interconnects, clock and power verification, and handoff to the foundry, mostly went to Broadcom, though OpenAI's own physical design engineers advised on floorplan and routing. At IEEE Hot Chips 2026, Ho and Leary presented an area reduction of 10 percent for the matrix multiplication units from AI-guided physical design optimization, measured against an optimized human baseline. Broadcom used its own internal workflow, with access only to OpenAI's public, commercial models rather than its internal chip-design LLMs. Ravi Krishna says OpenAI's backend approach already looks a bit conservative, an artifact of the project's October 2024 start, since models improved sharply from around April 2026 onward; fellow co-founder Suresh Krishna agrees an agentic loop could now accelerate the backend too.
Ho and Leary say the second-generation chip's workflow will lean on AI more, in verification and physical design, and the team now has tools for automatic waveform manipulation and analysis to trace clock-signal failures during debugging. Still, both are clear that chip design cannot be fully automated. "We're not saying that anyone can come and just build state-of-the-art, frontier AI/ML accelerator chips using just [OpenAI's coding platform] Codex," Ho says. "We are saying some very specific things about how to be better at Codex, and how we are focusing on a small team and fast timelines to reach quality results."
Key facts
- Jalapeño delivers up to 13.4 petaflops of 4-bit compute, 232GB of memory at 15.4TB/s, and up to 3.6x lower end-to-end latency than Nvidia's GB300 while using less power; pods hold 2,048 chips.
- The chip went from architecture concept to first silicon in under 20 months, with just nine months from first RTL to tapeout, built by a team that averaged fewer than 100 people.
- OpenAI owned system design (inference accelerator, memory hierarchy, networking); Broadcom handled physical design from the gates onward and production.
- AI-assisted software optimization raised DeepSeek's multi-head latent attention kernel benchmark from 0.31% to 88.94% of its theoretical ceiling in about 40 hours.
- AI-guided physical design cut matrix multiplication unit area by 10% versus an optimized human baseline, per numbers Ho and Leary presented at IEEE Hot Chips 2026.
Why it matters
Jalapeño is OpenAI's first move into designing its own inference silicon rather than buying it from Nvidia, and the design process is as much the story as the chip. A front-end workflow built around LLMs and an open-source synthesis toolchain took the project from concept to first silicon in under 20 months with a team that averaged fewer than 100 people, and independent chip-design experts call that pace credible and near best in class today. For a company racing to control inference cost and supply, cutting hardware design time is a direct lever on how fast new compute can reach production.
Who it affects
OpenAI's hardware and research teams, who are feeding lessons from Jalapeño into commercial models such as GPT-6 Astra and its successors. Broadcom, OpenAI's manufacturing partner, which handled physical design and production using only OpenAI's public models rather than its internal chip-design LLMs. Nvidia, whose GB300 is the benchmark OpenAI compares Jalapeño against and which OpenAI still relies on today. And the broader chip-design industry, including rivals like agentic chip-design startup Verkor.io, whose co-founders see the same LLM-driven acceleration becoming available to others as the underlying models improve.
How to use it
The workflow itself is the transferable part. OpenAI's front end centered on Accelerated Hardware Synthesis (XLS), an open-source high-level synthesis chain originally built at Google, which lets engineers write in DSLX or C++ and converts that into Verilog; LLMs were pointed at this layer because, in Chris Leary's words, it "looks like software." Later in the project, newer models could work directly in Verilog and approached operating proprietary design tools unassisted. OpenAI also used internal AI models to optimize software for the chip once first silicon arrived, taking one benchmark from 0.31% to 88.94% of its theoretical ceiling in about 40 hours, a result Ho says is repeatable for future chip generations.
How solid is it
The performance and timeline figures come from OpenAI itself, and the article notes plainly that whether Jalapeño's benchmark numbers hold up once it enters widespread service in OpenAI's inference fleet remains to be seen. But the design-speed claims are corroborated by outside chip-design experts: Verkor.io's David Chin and Ravi Krishna and UC San Diego's Andrew Kahng all independently describe the pace as credible, impressive or best in class, while also crediting Broadcom's help as essential rather than treating the result as AI working alone.
Risks and caveats
Several outside voices qualify the achievement rather than simply praise it. Chin says another team starting from scratch would not be able to match the timeline. Ravi Krishna calls OpenAI's backend design approach already a bit conservative, an artifact of the project's October 2024 start before later model generations improved. And Ho and Leary themselves are explicit that chip design cannot be fully automated: they are not claiming anyone could build a frontier AI accelerator chip using just OpenAI's Codex platform, only that a small, fast-moving team using it well can reach quality results faster than before.
“The models are giving superpowers to our engineers. Our engineers are still driving the work, they're still the final arbiter of what's going on. But they can do things a lot faster, they can explore a lot more paths.”
— Richard Ho, vice president of hardware at OpenAI, to IEEE Spectrum