Pelican-Sim 1.0 speeds robot world-model rollouts 5.67x
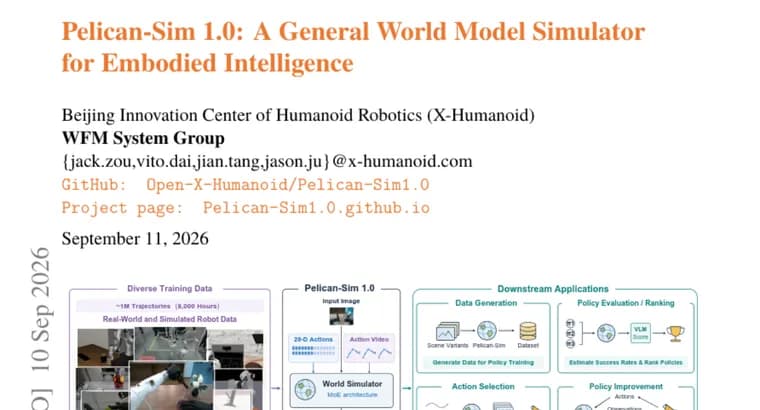
A technical report introduces Pelican-Sim 1.0, described as a general world model simulator for embodied intelligence. Given a visual context and a robot's actions, it predicts future observations, output meant to support downstream learning and decision making for robots rather than to stand as an end product on its own. The authors build the system around four design choices meant to work together: a unified way of representing actions, a way of injecting those actions into the visual generation process, a sparse mixture-of-experts architecture, and a distilled rollout procedure for generating predictions quickly.
The first design choice, unified action representation, encodes robot actions into a single 28-dimensional action value space that the authors say covers most mainstream robot embodiments, so one model stays valid across many different kinds of hardware instead of needing a separate model per robot. The second, action-visual injection, uses URDF-based and camera-rendered videos of the actions themselves to bridge actions and pixels; the authors report this gives markedly better controllability across embodiments, scenes, and tasks, measured as a PSNR gain of 0.904 over alternative fusion baselines. The third, sparse mixture-of-experts layers, adds model capacity to handle heterogeneous robot dynamics and absorb the action information while reducing conflict between modalities, cutting the FVD video-quality score by 6.530 compared with a dense backbone (a lower FVD means better video quality). The fourth, efficient rollout generation, applies causal adaptation and few-step distillation to turn what was a 35-step autoregressive simulator into a four-step one, a 5.67-fold speedup.
Trained on approximately one million real-world and simulated trajectories, Pelican-Sim 1.0 is reported to improve PSNR over the strongest evaluated baselines by 4.636 on the AgiBotWorld Beta benchmark, 2.080 on RoboMIND, and 10.343 on RoboTwin, with its adapted EWMBench DYN score on RoboTwin up 0.426. The text does not name the specific competing models behind these baseline scores, referring to them only as 'alternative fusion baselines,' 'the dense backbone,' and 'the strongest evaluated baselines.'
The paper reports four downstream applications, all tested on the RoboTwin benchmark. Adding 500 of the model's generated trajectories to 50 human demonstrations per task raises a robot policy's success rate from 70% to 93%. Using the model to evaluate policies reaches a Pearson correlation of 0.994 across five checkpoints. Using it for action selection produces a relative success gain of 47.7%, and using it for policy improvement produces a relative success gain of 20.3%. The authors also describe qualitative examples of generalization across shifts in trajectory, scene, object, embodiment, and viewpoint, which they say highlights the model's potential as a general-purpose world model simulator, a claim the text frames as potential rather than as an already proven, fully general capability.
Key facts
- Pelican-Sim 1.0 is a general world model simulator for embodied intelligence: it predicts future robot observations from visual context and actions, using a unified 28-dimensional action space that keeps one model valid across most mainstream robot embodiments.
- Action-visual injection raises PSNR by 0.904 over alternative fusion baselines, and sparse mixture-of-experts layers cut the FVD video-quality score by 6.530 versus a dense backbone.
- Causal adaptation and few-step distillation turn a 35-step autoregressive simulator into a four-step one, a 5.67-fold speedup.
- Trained on about one million real-world and simulated trajectories, the model improves PSNR over the strongest evaluated baselines by 4.636 on AgiBotWorld Beta, 2.080 on RoboMIND, and 10.343 on RoboTwin, with its adapted EWMBench DYN score on RoboTwin up 0.426.
- On RoboTwin, adding 500 of the model's generated trajectories to 50 human demonstrations per task raises a downstream robot policy's success rate from 70% to 93%; using the model for policy evaluation, action selection, and policy improvement reaches a 0.994 Pearson correlation and relative success gains of 47.7% and 20.3%.
Why it matters
Pelican-Sim 1.0 packages four design choices into a single simulator meant to predict what a robot will see next, given its actions: a unified action representation, action-visual injection, sparse mixture-of-experts layers, and a distilled rollout procedure. The unified 28-dimensional action space is what lets one model stay valid across many different kinds of robot hardware instead of needing a model per embodiment, and the distilled rollout compresses a 35-step generation process into four steps, a 5.67-fold speedup, which matters because it makes generating large volumes of synthetic robot experience practical. The paper backs this up with a downstream result: on RoboTwin, adding 500 of the model's generated trajectories to 50 human demonstrations per task raises a robot policy's success rate from 70% to 93%, suggesting the simulator's output can improve how well a robot policy performs, not just how good its predicted video looks.
Who it affects
The paper speaks to robotics and embodied-AI researchers who train policies across different robot hardware and want a single simulator rather than one model per embodiment, and to anyone evaluating world models as a source of synthetic training data or as a tool for policy evaluation and selection. The text does not name the individuals, company, or institution behind the work; the item's crawler-supplied author name is submission metadata, not part of the article itself.
How to use it
The text gives no information about accessing Pelican-Sim 1.0: it does not say whether the model's weights, code, or training data are, or will be, released. What exists publicly for now is the technical report itself, posted as a Hugging Face Papers listing; anyone wanting to run or build on the model would need a separate release announcement, since none is described here.
How solid is it
Every number in the report is self-reported by its authors: the PSNR and FVD gains over baselines, the 5.67-fold rollout speedup, and the four RoboTwin downstream results all come from the paper's own experiments. The baselines being outperformed are not named as specific competing models, only described generically as 'alternative fusion baselines,' 'the dense backbone,' and 'the strongest evaluated baselines,' so the comparisons cannot be checked against named, public systems. All four downstream applications (data augmentation, policy evaluation, action selection, and policy improvement) are reported on the RoboTwin benchmark only; the text does not report a result from physical, real-world robot deployment. The report also gives no training compute, parameter count, or publication date, and does not name individual authors or an institution, leaving little outside basis for judging the work's track record.
Risks and caveats
The paper's own framing of generalization across trajectory, scene, object, embodiment, and viewpoint shifts is qualitative, described as highlighting the model's 'potential' as a general-purpose simulator rather than a proven, fully general capability. Every quantitative downstream gain, including the jump from 70% to 93% policy success, comes from one benchmark suite, RoboTwin, using the authors' own comparisons rather than independent replication. Because the report says nothing about releasing weights, code, or training data, outside groups cannot yet reproduce or stress-test these numbers, and because no physical-robot result is reported, it remains unclear how the simulator's gains carry over outside RoboTwin's benchmark setting.
“Qualitative generalization across trajectory, scene, object, embodiment, and viewpoint shifts highlights its potential as a general-purpose world model simulator.”
— the Pelican-Sim 1.0 paper