Recursive Self-Rewrite trains Qwen-3.8-27B on terminal tasks, lifting Terminal-Bench 2 pass@3 to 74.2%
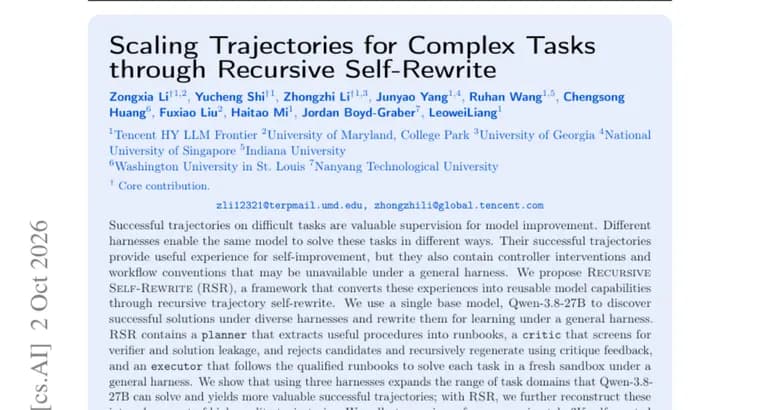
The paper starts from a tension. Successful trajectories on difficult tasks are valuable supervision for improving a model, but the specialized harnesses that produce them add interventions that may not be available when the model is deployed. Training directly on such trajectories therefore risks teaching a model habits it cannot use in a general setting.
The authors propose Recursive Self-Rewrite (RSR). It uses one base model, Qwen-3.8-27B, to discover successful solutions under diverse harnesses and then reconstruct them as training trajectories under a general harness. Three roles carry out the rewrite. A planner extracts procedures into runbooks. A critic screens for verifier and solution leakage and guides recursive revision of the runbooks. An executor follows the qualified runbooks in fresh sandboxes, producing the new trajectories.
The data side is described in numbers. The work covers approximately 3K self-curated terminal tasks. Three harnesses jointly solve 759 of them, which is 34.3% more than the strongest individual harness in the recorded pool. RSR then expands 2,001 successful source trajectories into 11,094 rewritten trajectories, and these are used for supervised finetuning (SFT).
The authors report that training on the rewritten trajectories outperforms both the base model and direct trajectory SFT. Against the base model, pass@3 rises from 57.0% to 74.2% on Terminal-Bench 2, from 1.5% to 9.1% on Terminal-Bench 4, from 39.0% to 63.0% on their self-curated Terminal-Bench Hard, and from 3.0% to 6.0% on their Software Terminal-Bench. Process reward on Long-Horizon Terminal-Bench rises from 0.21 to 0.29.
The authors conclude that diverse harness-assisted experiences can be reconstructed into reusable capabilities for a model operating under a general harness.
Key facts
- RSR uses one base model, Qwen-3.8-27B, to find successful solutions under diverse harnesses and rewrite them as training trajectories under a general harness.
- A planner writes runbooks, a critic screens for verifier and solution leakage and guides recursive revision, and an executor follows qualified runbooks in fresh sandboxes.
- On about 3K self-curated terminal tasks, three harnesses jointly solve 759, 34.3% more than the strongest individual harness in the recorded pool.
- 2,001 successful source trajectories become 11,094 rewritten trajectories for supervised finetuning.
- Versus the base model, pass@3 goes from 57.0% to 74.2% on Terminal-Bench 2 and from 1.5% to 9.1% on Terminal-Bench 4; the authors also report outperforming direct trajectory SFT.
Why it matters
Agents that work in a terminal often look good only under a specialized harness, and the extra interventions in that setup may not exist in production. RSR is an attempt to keep the supervision signal from those hard-won successes while removing the dependence on the harness. The reported gains are large in absolute terms on some benchmarks: 17.2 points of pass@3 on Terminal-Bench 2 (57.0% to 74.2%) and 24.0 points on the authors' Terminal-Bench Hard (39.0% to 63.0%). The authors also say the approach beats direct trajectory SFT, which is the natural simpler alternative.
Who it affects
Mainly researchers and teams training terminal and software-engineering agents, especially those who collect successful runs from specialized harnesses and want to turn them into finetuning data for a model that will run under a general harness. The method is demonstrated on a single 27B-class base model, Qwen-3.8-27B, so its direct relevance is to people working with models of that kind.
How to use it
The source describes the recipe rather than a release. The steps are: run a base model under several harnesses on a pool of terminal tasks and keep the successes; have a planner extract each procedure into a runbook; have a critic screen it for verifier and solution leakage and guide recursive revision; have an executor follow the qualified runbook in a fresh sandbox under a general harness; and use the resulting trajectories for supervised finetuning. In the paper's setup, 2,001 source trajectories yielded 11,094 rewritten ones. No code, model release, dataset release or compute cost is mentioned in the source.
How solid is it
The source is the paper's abstract, and it gives concrete figures for every claim: task counts, trajectory counts and pass@3 before and after. No authors or institutions are named in the source text. Several of the benchmarks that show the biggest gains are the authors' own, labelled self-curated (Terminal-Bench Hard and Software Terminal-Bench). Numbers for direct trajectory SFT are not given, only that RSR outperforms it, and the three harnesses are not named. The results are also reported against the base model only.
Risks and caveats
Absolute levels stay low on some benchmarks even after training: 9.1% pass@3 on Terminal-Bench 4 and 6.0% on the Software Terminal-Bench. The 34.3% figure describes how many more tasks three harnesses solve together than the best single harness in the recorded pool; it is not an improvement of the trained model over the base model. The critic's leakage screening exists because verifier and solution leakage into the rewritten trajectories is a concern the authors designed against. No number of runbook revisions or recursion depth is given, so the cost of the recursive loop is unclear from the source.
“Training on these trajectories outperforms both the base model and direct trajectory SFT.”
— From the paper's abstract