VFlash predicts whole visual plans in one pass, with a claimed 25x speedup
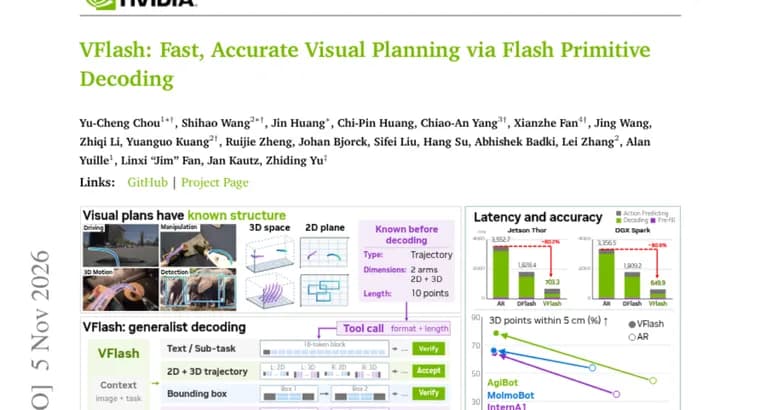
A paper on Hugging Face introduces VFlash, a method for visual planning in physical AI tasks such as robotics and autonomous driving. The starting point is that such models need not reason only in language. They can use visual plans, meaning points, bounding boxes and trajectories, to represent spatial goals and anticipate motion. The trouble is that autoregressive vision-language models generate these plans one coordinate token at a time, so richer predictions get increasingly costly.
VFlash tackles this with what it calls Flash Primitive Decoding. It exploits the known structure of visual primitives to predict their coordinates jointly. A lightweight drafter generates an entire primitive in one forward pass. The drafter's layout adapts to the primitive's type, dimensionality and length, so it can handle compact boxes as well as long, variable-length trajectories.
The paper's central argument is that spatial accuracy need not require reproducing an autoregressive model's exact token sequence. Because of that, VFlash trains on annotated primitives and directly accepts structurally valid predictions without target-token agreement.
The reported results come in three parts. Across the evaluated 2D and 3D robot trajectory tasks, VFlash consistently reduces prediction errors relative to autoregressive decoding, though no numeric error reductions are given. Preliminary single-rollout measurements indicate approximately 25x faster generation for 3D point motion forecasting. And a world action model conditioned on VFlash plans achieves 70.2% average success across four MolmoSpaces task suites, compared with 62.6% for the baseline, a gap of 7.6 percentage points.
Key facts
- VFlash uses a lightweight drafter that generates an entire visual primitive (point, box or trajectory) in one forward pass, instead of one coordinate token at a time.
- Preliminary single-rollout measurements indicate approximately 25x faster generation for 3D point motion forecasting.
- Across the evaluated 2D and 3D robot trajectory tasks, the paper says VFlash consistently reduces prediction errors relative to autoregressive decoding.
- A world action model conditioned on VFlash plans reaches 70.2% average success across four MolmoSpaces task suites, against 62.6% for the baseline.
- Training uses annotated primitives, and structurally valid predictions are accepted without target-token agreement.
Why it matters
Visual plans such as points, boxes and trajectories are a way for robotics and driving models to express spatial goals without reasoning only in language. Generating them one coordinate token at a time makes longer or richer plans increasingly expensive. VFlash attacks that cost by decoding a whole primitive in a single forward pass, and it drops the requirement that output match an autoregressive model's exact token sequence.
Who it affects
The target is work on physical AI, namely robotics and autonomous driving, where vision-language models produce spatial plans. Researchers building such planners, and teams that condition a world action model on visual plans, are the natural audience.
How to use it
The source gives no code release, model size, training data or hardware details, so there is nothing concrete to run yet. Conceptually, the recipe is to train a lightweight drafter on annotated primitives, size its layout to the primitive's type, dimensionality and length, and accept structurally valid outputs directly.
How solid is it
This is a preprint abstract. The speedup is explicitly described as preliminary, from single-rollout measurements, and is stated only for 3D point motion forecasting; no speedup is given for 2D tasks, boxes or other primitive types. The error reduction is described only as consistent, with no numbers. The MolmoSpaces result is an average over four suites with no per-suite breakdown, and the baseline and the world action model are not named beyond that description.
Risks and caveats
The 25x figure should not be read as a general speedup. It comes from preliminary single-rollout measurements on one task type. The 70.2% versus 62.6% comparison is an average, and without per-suite results or a named baseline it is hard to judge how broad the gain is. Authors and institutions are not named in the source text, and no independent replication is mentioned.
“spatial accuracy need not require reproducing an autoregressive model's exact token sequence”
— VFlash paper abstract