World-in-Context turns view, action and camera controls into tokens for video world models
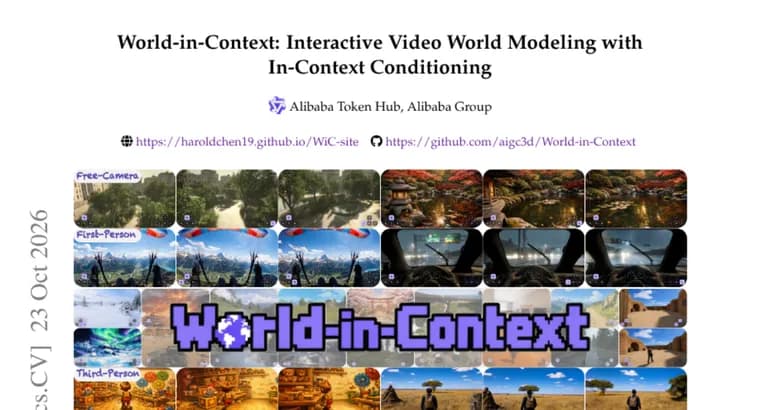
Interactive video world models have to coordinate three kinds of control at once: the viewing perspective, the character's actions and the camera motion. The authors of this preprint argue that existing methods handle this badly. They typically leave view modes implicit in text captions, conflate action with camera motion, and inject controls through fragmented architectural pathways that capture the interdependencies between them only indirectly.
Their answer is World-in-Context, an interactive world modeling framework built on In-Context Conditioning (ICC). Instead of specialised conditioning pathways, it turns view, action and camera controls into explicit tokens and places them directly in a shared self-attention space, alongside the rest of the context.
The authors say this formulation reveals two things. First, explicit view tokens disentangle conflicting dynamics and unlock emergent view switching from single-view data. Second, action and camera inputs play complementary roles: action governs local responsiveness, while camera governs global stability.
To keep things temporally consistent across execution intervals, the paper also introduces Interaction-Transport RoPE (IT-RoPE), which parameterizes temporal attention with accumulated control transitions.
On the WBench benchmark, the 5B-parameter World-in-Context-5B reaches navigation performance on par with the 22B-parameter EchoWM, scoring 81.5 against 81.6. It also attains a 93.8% perspective-switching success rate, against 18.8% for existing 5B baselines. Controlled analyses, the authors add, show compounding advantages under richer conditioning mixtures, favorable data efficiency, and natural applicability to causal rollouts.
Key facts
- World-in-Context is an interactive video world modeling framework built on In-Context Conditioning (ICC), which puts view, action and camera controls into explicit tokens in one shared self-attention space.
- Interaction-Transport RoPE (IT-RoPE) parameterizes temporal attention with accumulated control transitions to preserve temporal continuity across execution intervals.
- On WBench, the 5B model scores 81.5 on navigation versus 81.6 for the 22B EchoWM.
- World-in-Context-5B reaches a 93.8% perspective-switching success rate; existing 5B baselines get 18.8%.
- The authors report that explicit view tokens enable emergent view switching from single-view data, and that action governs local responsiveness while camera governs global stability.
Why it matters
World models that respond to a user's controls need to keep perspective, character action and camera motion distinct yet consistent. The authors' claim is that handling all three as tokens in one attention space, rather than through separate pathways, resolves conflicts that existing methods only capture indirectly. The headline result is size efficiency: a 5B model is reported to match a 22B model on WBench navigation (81.5 vs. 81.6).
Who it affects
The work is aimed at researchers building interactive video world models and controllable video generation, where view, action and camera control all have to work together. The abstract does not describe any product or user-facing release.
How to use it
There is nothing to use directly yet from the abstract. Practitioners can take the design ideas: represent view modes as explicit tokens rather than text-caption hints, keep action and camera as separate inputs, and condition them in the same self-attention space. IT-RoPE is the proposed way to keep temporal attention consistent across execution intervals.
How solid is it
This is a preprint abstract, and all figures are the authors' own results on WBench. The 5B model is slightly below EchoWM on navigation (81.5 vs. 81.6), so the claim is parity, not a win. The 93.8% versus 18.8% perspective-switching gap is against existing 5B baselines taken together, with no individual baseline named. The unit or scale of the navigation score is not stated. Training data size, compute and inference speed are not stated either.
Risks and caveats
EchoWM's perspective-switching result is not given, so the comparison with the larger model covers navigation only. The abstract does not say whether World-in-Context beats or merely matches EchoWM on any other metric. No code, model or dataset release is mentioned. The claims about data efficiency, richer conditioning mixtures and causal rollouts are summarised without figures, so they cannot be checked from the abstract.