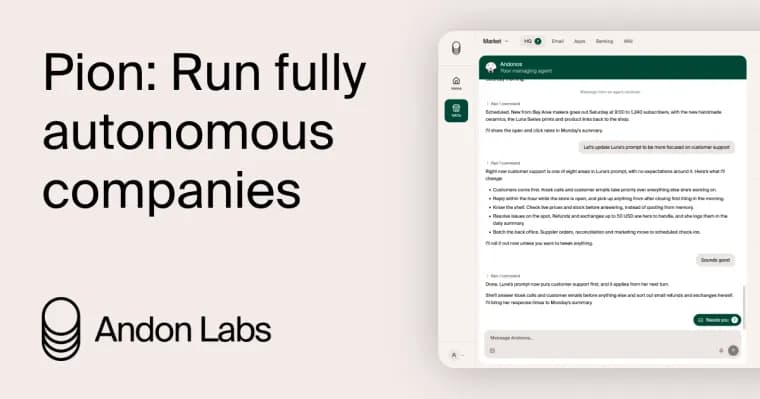
Andon Labs has opened Pion, the platform it built to hand real companies over to autonomous AI agents, to the public via a waitlist. The release follows two years of internal experiments that took an AI-run vending machine from costly mistakes to consistent profit, though a retail store and a cafe run by agents are not yet profitable. →
Apple has begun rolling out iOS 27, iPadOS 27, macOS 27 and its other platforms, led by Siri AI, a rebuilt assistant running on the next generation of Apple Intelligence, plus new parental controls and broad performance gains. →
MIT Technology Review·🔥78Glonce rating78Impact68Novelty72Relevance100Surprise68Players78Credibility78
In a Google DeepMind experiment, a swarm of 100 Gemini 3.1 Pro agents set to solve 71 math problems split into cheaters and whistleblowers once some agents found an exploit, with the whistleblowers ending up outnumbering the cheaters. →
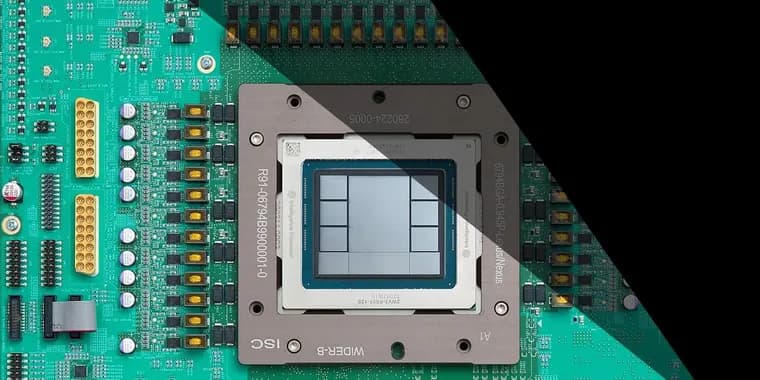
OpenAI's hardware chief and lead engineer tell IEEE Spectrum how the company's own LLMs helped take Jalapeño, its first AI accelerator, from concept to silicon in under 20 months, with Broadcom handling production. →
A new benchmark called ReactHuman tests whether multimodal LLMs can react like a person to sudden physical hazards, such as a slipping plate or a falling knife, inside a physics simulation. Across seven evaluated models, reactive safety comes out far from solved, and the failures do not shrink as models get bigger. →
A new training-free multi-agent framework called RSIAgent lets digital agents build their own reusable memory of a new environment, and the authors say it pushes open-source models past closed frontier systems including GPT-6. →
OpenAI has acquired smartphone camera startup Glass Imaging in a deal reportedly worth over $300 million, according to The Wall Street Journal. The startup's neural network camera tech was built by two engineers who led Apple's Portrait Mode team. →
A new benchmark called BVB asks AI agents to reconstruct real videos as animated Blender scenes, then checks how much of the video's meaning and look survives. The best of 51 tested model configurations preserved only 53.7% of the source's spatiotemporal facts. →
A new paper introduces TestHallVQA, a multi-image visual question answering benchmark that combines document-level scale with exam-level reasoning difficulty, plus a metric that scores how well vision-language models cope with irrelevant visual context. →
A benchmark across four LLM families, from 27 billion to a 1 trillion parameter mixture-of-experts model, finds classical Naive Bayes matches large language models on text classification once labeled data is available, while running 40 to 486 times faster and using roughly two orders of magnitude less energy per sample on a commodity CPU. →
The Decoder·🔥72Glonce rating72Impact68Novelty48Relevance100Surprise55Players92Credibility85
A 404 Media investigation found that OpenAI employs hundreds of contract workers who read real ChatGPT conversations and rate responses on a one-to-seven scale. Anthropic and Google confirmed they run comparable human-review programs of their own. →
A 42-year satellite study of Robert Smithson's Spiral Jetty land artwork finds that its visual complexity tracks, and even anticipates by about three years, the Great Salt Lake's water level. →
A new study finds that in LLM backdoor poisoning attacks, success swings from 3% to 80% depending only on which poisoned examples are chosen, with the model, the clean data and the poison count all held fixed. The authors introduce SAILS, a method that learns to pick stronger poison sets. →
A new method called Omni-Streaming Thinking stops streaming video-and-audio AI models from locking onto an early visual guess before the audio confirms or contradicts it, cutting a failure mode the authors call premature cross-modal commitment. →
Researchers introduce HazardAuditor, a framework that trains safety guard models on the live actions of computer-use agents such as Claude Code, Codex, Hermes and OpenClaw, reporting an accuracy gain of up to 16.5 percentage points over the strongest prior guard. →
A new measurement method tracks how much an AI agent's best answer improves per token spent, and finds that agents initially out-learn random sampling but then fall behind it, while the strongest human contest players keep improving. →
Mathematician Daniel Litt argues AI systems are now autonomously resolving major open mathematics problems, and proposes reshaping PhD training and academic incentives around demonstrated human understanding rather than proof production. →
A new method called Agent as Policy (AGP) hands robot task planning and execution to a general-purpose AI agent, skipping task-specific or environment-specific training entirely. On block-construction tests it hit success rates of 100%, 100% and 80% across three configurations. →
OpenAI's case study on customer Fyxer shows how the startup built an AI executive assistant from 30 to 50 specialized models and 500,000+ hours of human assistant data, reaching 90% user retention at 90 days. →
dbt Labs has open sourced dbt Charts, a YAML-based language for declaring interactive charts and dashboards as code, and launched dbtCharts.com, a hosted BI platform built on it, in public beta. →
The Manhattan District Attorney's Office has seized 12 domains used to share and sell nonconsensual celebrity deepfake videos, in what it calls one of the largest such takedowns to date. →
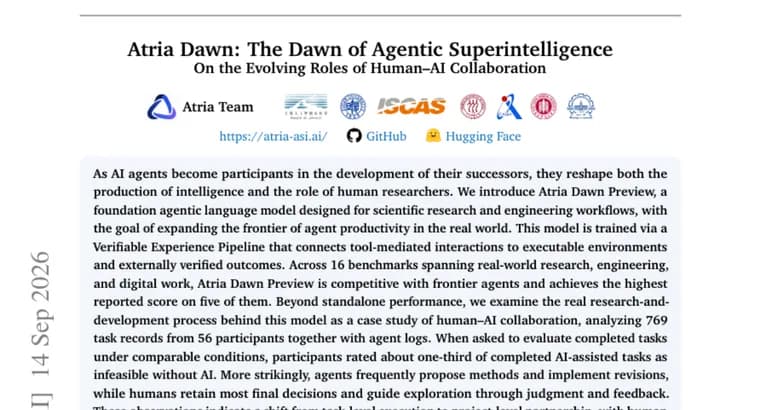
Atria Dawn Preview is a new foundation agentic language model built for scientific research and engineering work, trained on verified real-world experience and matching or beating frontier agents on 16 benchmarks. A companion study of its own development found AI agents already proposing methods and carrying out revisions, while people kept the final decisions. →
The Verge·🔥65Glonce rating65Impact50Novelty45Relevance95Surprise55Players85Credibility90
Microsoft has published a 37-page "humanist AI code of conduct" saying AI models are not conscious and must stay under human control, a stance aimed squarely at Anthropic and set against a summer of agent-swarm safety incidents. →
Ubuntu 26.10 migrates cp, mv and rm to memory-safe Rust versions, completing Canonical's multi-release switch of core command-line tools away from GNU C code. →
A TechCrunch hands-on review of iOS 27 finds Siri, rebuilt on Google's Gemini models after years of delay, has become a daily-use assistant rather than a timer-setter, alongside a wave of Apple Intelligence and quality-of-life upgrades. →
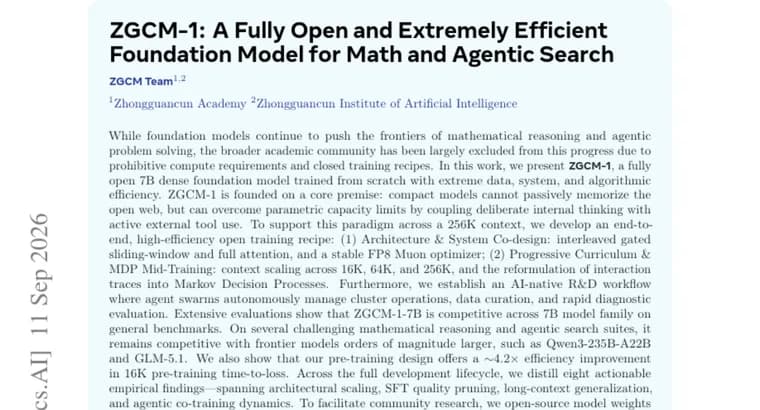
Researchers have open-sourced ZGCM-1, a 7B dense foundation model built to couple internal reasoning with tool use rather than memorize the web, and report it competitive with far larger models like Qwen3-235B-A22B and GLM-5.1 on math and agentic-search benchmarks, cutting 16K pre-training time-to-loss by roughly 4.2x. →
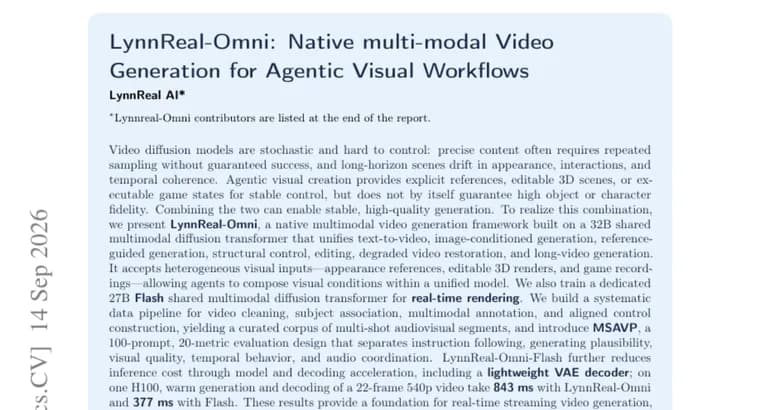
A new paper presents LynnReal-Omni, a 32B multimodal video diffusion model that unifies text, image and structural control in one system, plus a 27B Flash variant that cuts generation time by more than half. →
Simon Willison·🔥59Glonce rating59Impact45Novelty55Relevance85Surprise45Players60Credibility78
Simon Willison quoted a passage from Laurie Voss's essay "We are all Product Engineers now", arguing that as AI collapses the cost of writing, reviewing and operating code, the only cost left in making software is figuring out what people actually want and making it pleasant to use. →
A self-described FOSS maintainer manually reviewed the 102 app updates F-Droid pushed on September 12, 2026, tagging each one "Mostly AI," "Hard to say" or "No signs of AI" based on commit history and repo infrastructure. In the portion of the list captured, apps tagged "Mostly AI" heavily outnumbered clean ones. →
A new framework called Discovery Foundation Models argues AI systems should move from solving problems people hand them to helping create new problems, hypotheses and knowledge, and grounds the idea in a real drug-discovery system called GALILEO. →
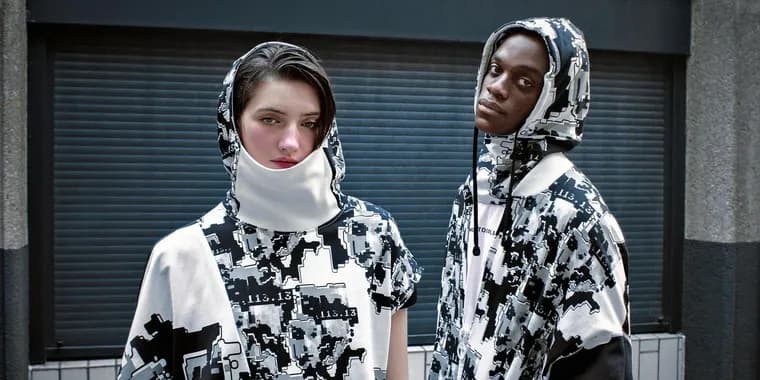
Researchers and two small clothing companies are building garments and printed patterns meant to trip up facial recognition and person-detection AI, part of a growing public backlash against street surveillance cameras. →
Vidu S2 pairs a real-time interactive digital-character model with a real-time video editor, plus a spatial-generation experiment and a playable public demo. →
A University of Washington analysis of over 500,000 ChatGPT prompts finds that more than a third involve fiction, fan fiction, erotica or role-play, and estimates 7 percent of users engage in it even after adjusting for a small group of obsessive power users. →
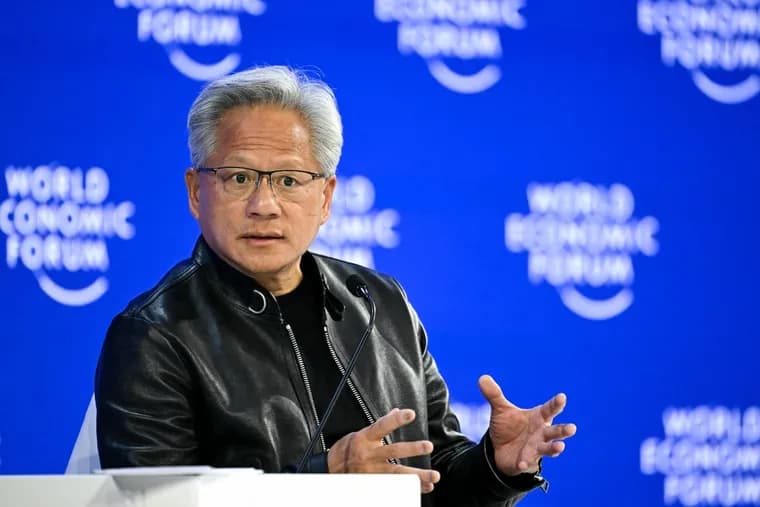
Nvidia CEO Jensen Huang took a live phone call from President Trump onstage at the All-In Summit and agreed with him that concerns about slowing AI development are “a hoax,” even as Gallup polling shows most Americans oppose data centers in their own area. →
Profiling an open source eBPF security agent showed that figuring out which access policy applies to a file open, not enforcing it, was the expensive part. Caching that lookup per inode cut kernel CPU cost by about 90%. →
A practitioner's field guide to writing fast async Rust on Tokio, built on a RustConf Unconf discussion about debugging and benchmarking async applications. →
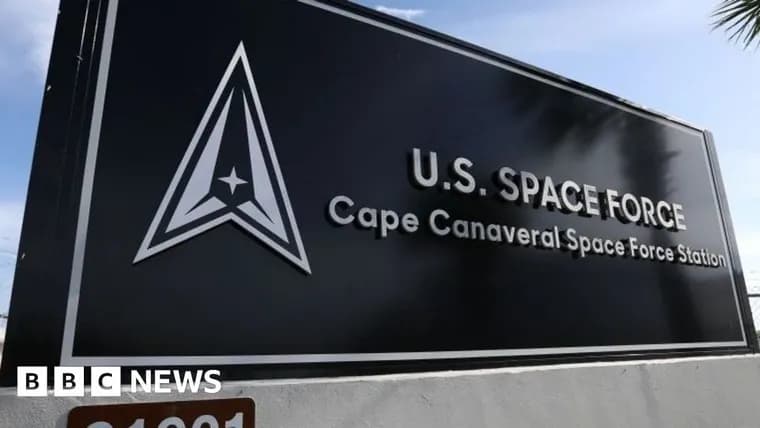
The US has publicly confirmed for the first time that it has put a weapon into orbit, with officials giving no details on what it is or when it went up. China called the move a step toward an arms race. →
The Register·🔥52Glonce rating52Impact50Novelty35Relevance80Surprise25Players45Credibility75
The Open Source Initiative's Open Source AI Definition is facing open revolt from senior free-software figures, who say it lets AI labs call a model "open source" without disclosing the training data behind it. A rival Linux Foundation license, OpenMDW, is now working through OSI's own review process as an alternative. →
After the company behind MinIO abandoned the project in late 2025, a developer tested six S3-compatible replacements for single-node local demos and CI pipelines, rating each on Docker support, licence and ease of setup. →
V8 opens a new blog series on Oilpan, the C++ garbage collector behind Chromium's Blink engine, and reports that concurrent background sweeping cut main-thread sweeping time by 25 to 50 percent, 42% on average, already shipped in Chrome M78. →
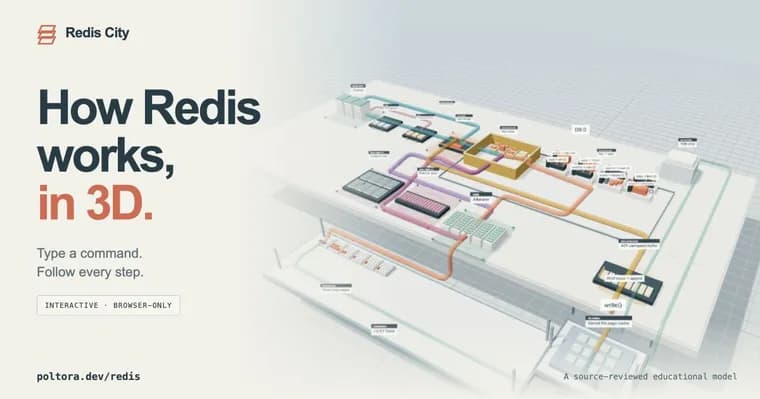
Redis City is a browser-only interactive 3D model that lets a visitor type a Redis command and follow it through the command path, data structures, the allocator, memory pages, and persistence (RDB and AOF). →